First screen, captured .
Looks similar
My finetuned models beat OpenAI's GPT-4(mlops.systems)
376 points by majc2 | 86 comments
Blog post evaluating finetuned Mistral, Llama3 and Solar LLMs against OpenAI's GPT-4 on accuracy for structured data extraction from press releases.
TabPFN and TabICL vs. tuned XGBoost: the model that doesn't train won 14/14(efraingaray.com)
21 points by EfrainGaray | 9 comments
Blog post benchmarking TabPFN and TabICL foundation models against tuned XGBoost on fourteen tabular datasets, finding the no-training models won all fourteen.
Related stories
AI Made Writing Code Easier. It Made Being an Engineer Harder(ivanturkovic.com)
343 points by saikatsg | 242 comments
Blog post by Ivan Turkovic arguing that AI tools make producing code easier while making the broader job of being a software engineer harder.
Phi-4: Microsoft's Newest Small Language Model Specializing in Complex Reasoning(techcommunity.microsoft.com)
399 points by lappa | 136 comments
Microsoft AI Platform Blog post announcing Phi-4, a small language model specializing in complex reasoning.
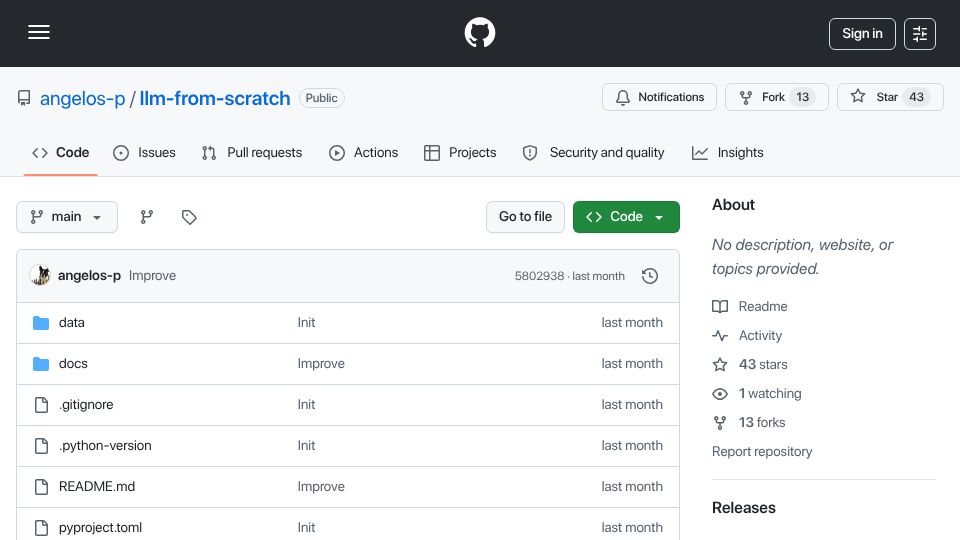
Train Your Own LLM from Scratch(github.com)
376 points by kristianpaul | 43 comments
GitHub repository by angelos-p providing code and docs for training your own large language model from scratch.
Training LLMs from ground zero as a startup(yitay.net)
360 points by swyx | 92 comments
Yi Tay's blog post on the experience of training large language models from scratch at a startup (Reka), covering compute, infrastructure, and lessons learned.
The new skill in AI is not prompting, it's context engineering(philschmid.de)
832 points by robotswantdata | 467 comments
Blog post by Philipp Schmid arguing that context engineering, supplying LLMs with the right information and tools, matters more than prompting for AI agents.
We no longer use LangChain for building our AI agents(octomind.dev)
431 points by ma_za | 253 comments
Octomind blog post explaining why the company stopped using LangChain for its AI agents and what it learned using it in production.