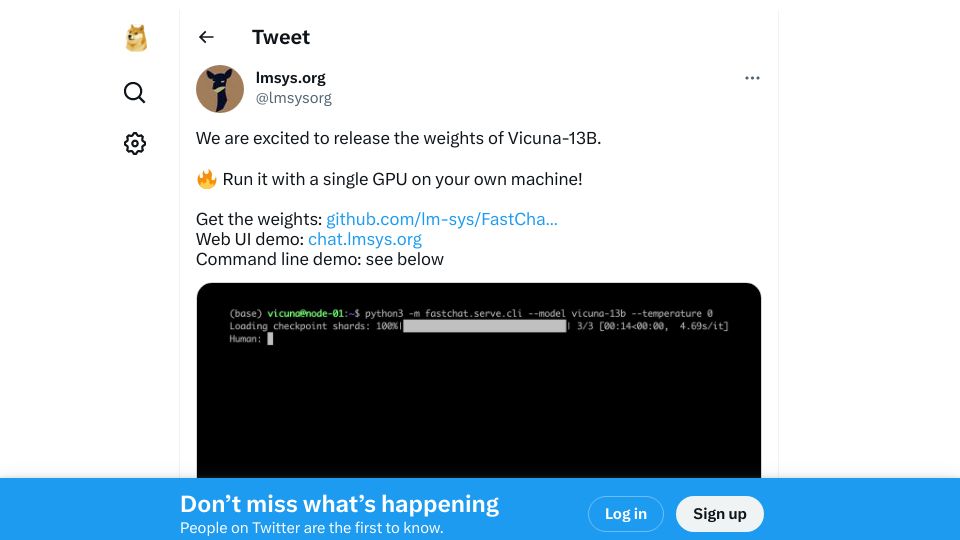
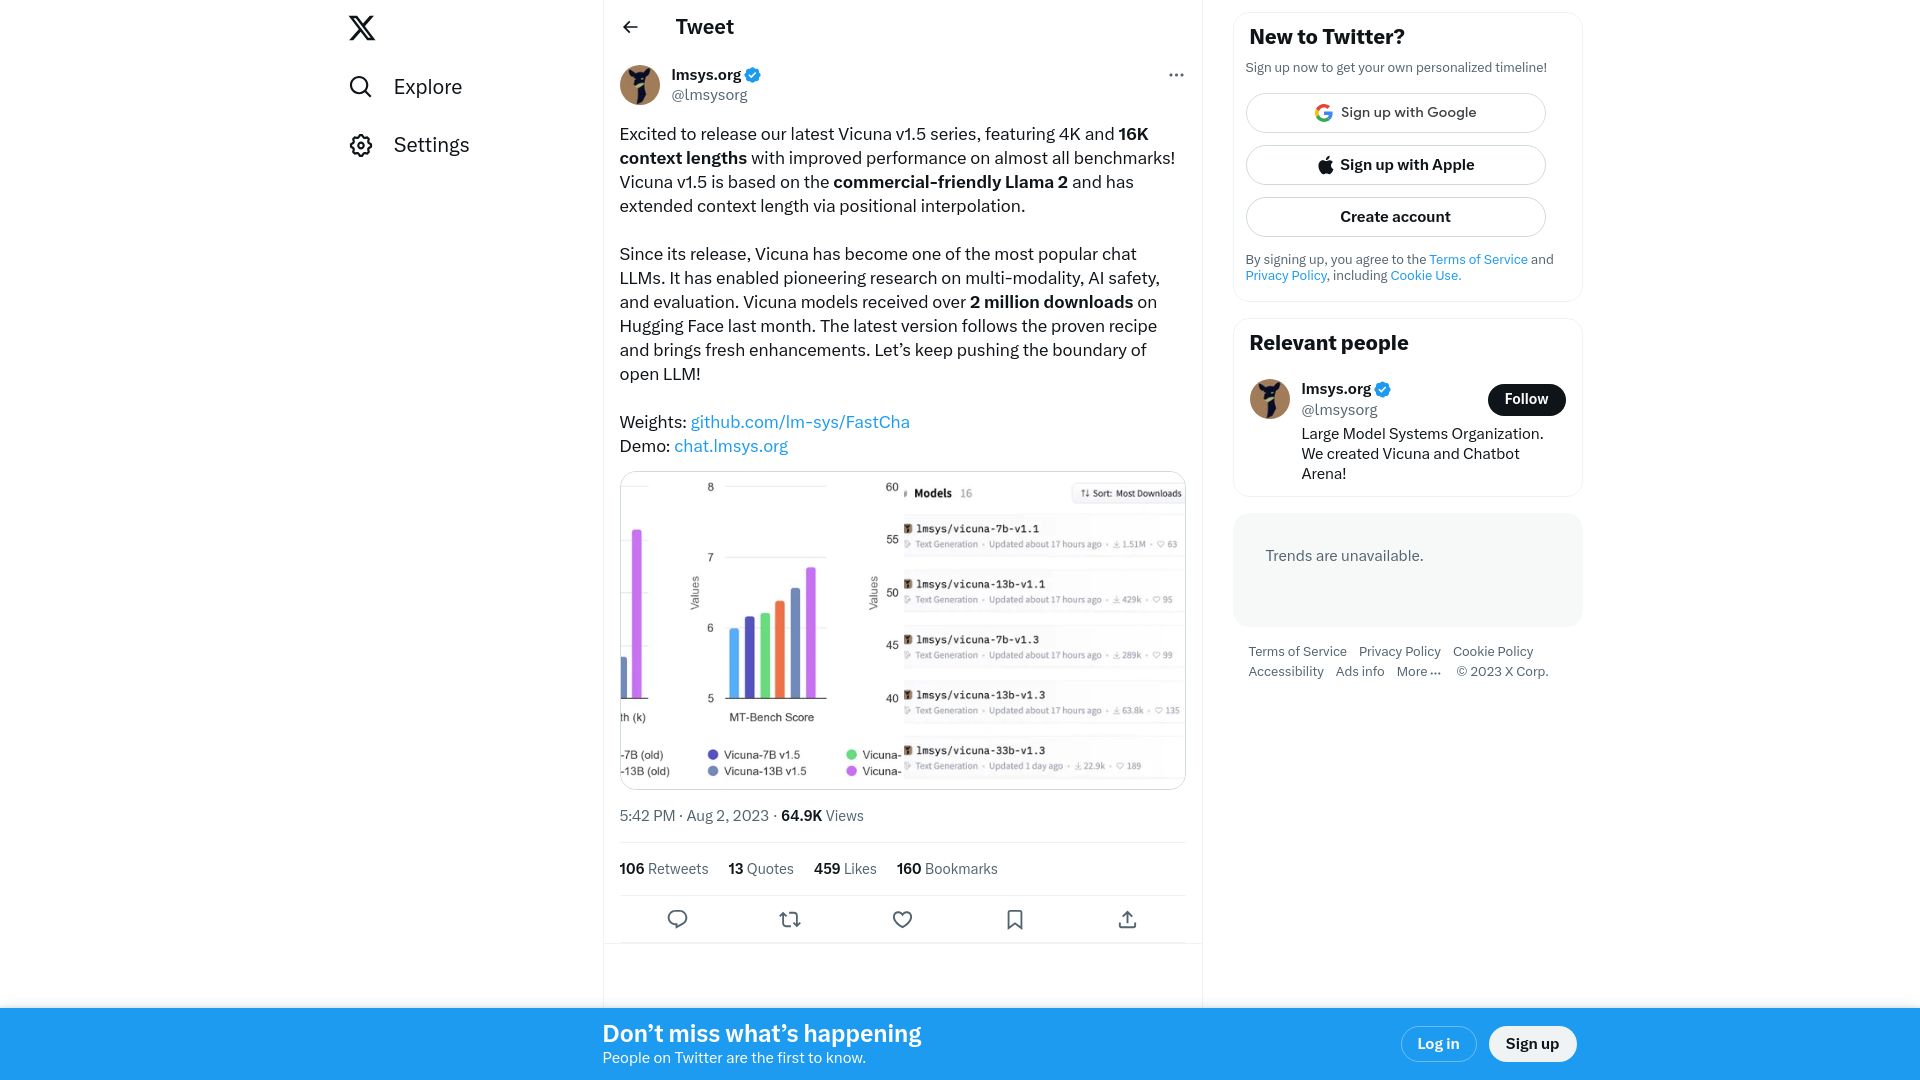
State-of-the-art open-source chatbot, Vicuna-13B, just released model weights(twitter.com)241 points by weichiang 3 years ago | 113 comments
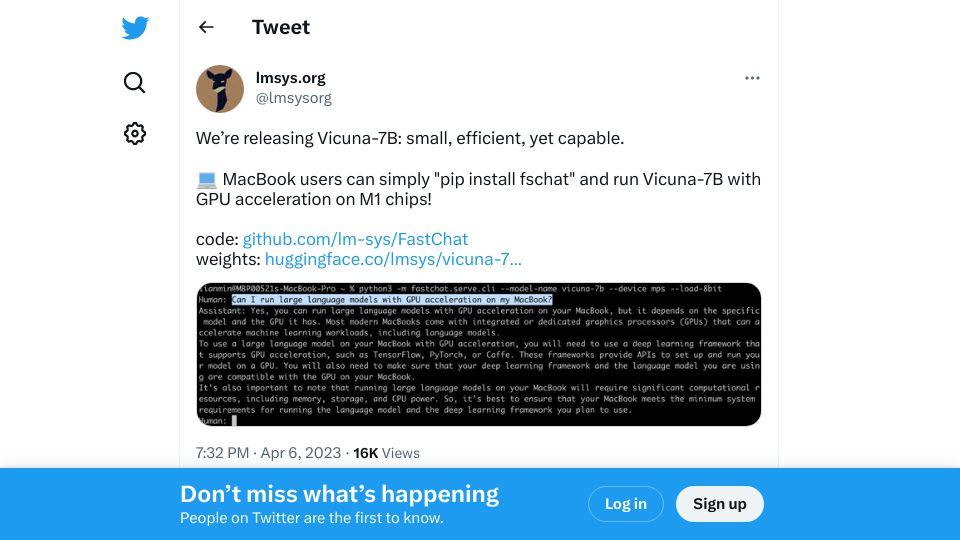
State-of-the-Art Chatbot, Vicuna-7B, now runs on MacBook with GPU acceleration(twitter.com)81 points by weichiang 3 years ago | 54 comments
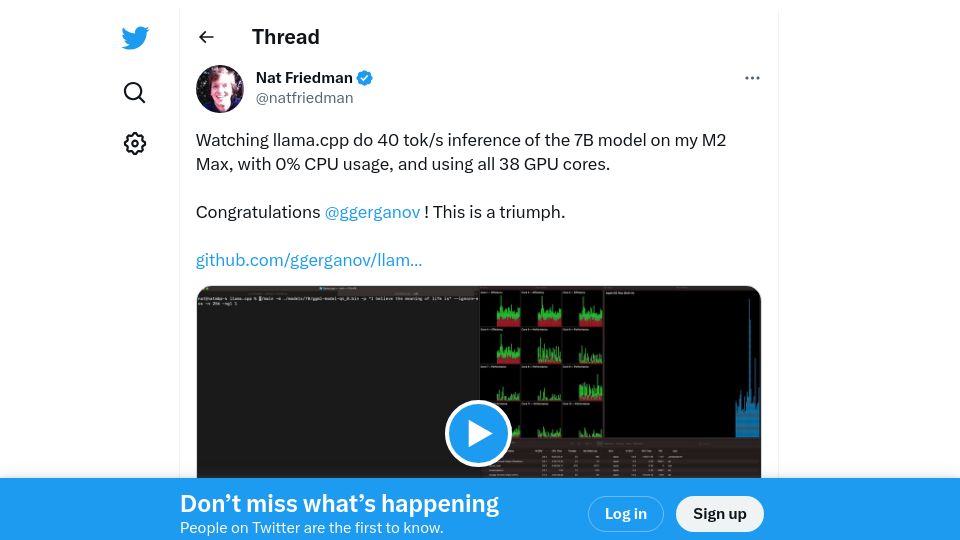
Llama.cpp can do 40 tok/s on M2 Max, 0% CPU usage, using all 38 GPU cores(twitter.com)40 points by samwillis 3 years ago | 9 comments
Justine creates llamafile. Cross platform single binary for any LLM weights(twitter.com)10 points by klohto 2 years ago | 0 comments
LeCun: Qualcomm working with Meta to run Llama-2 on mobile devices(twitter.com)85 points by birriel 3 years ago | 50 comments