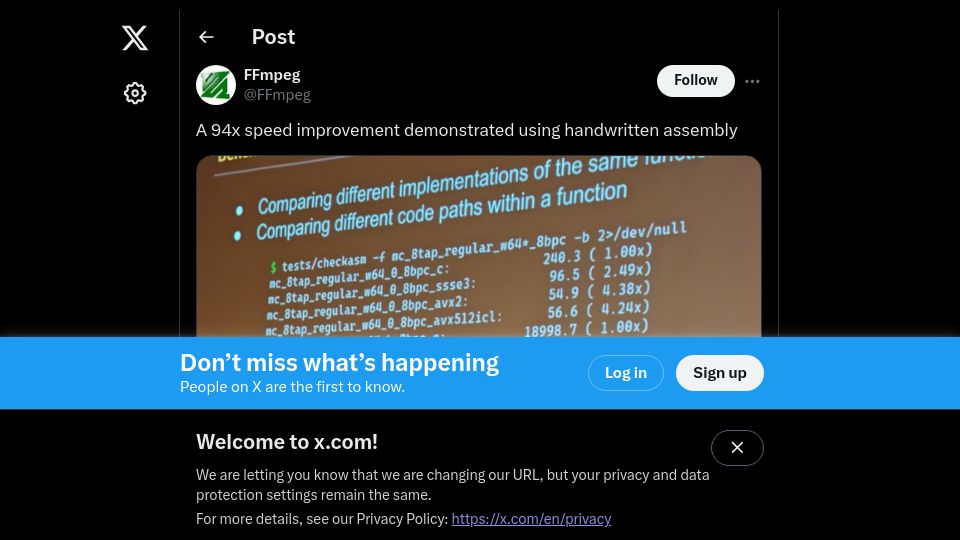
A 94x speed improvement demonstrated using handwritten assembly(twitter.com)43 points by doener 2 years ago | 29 comments
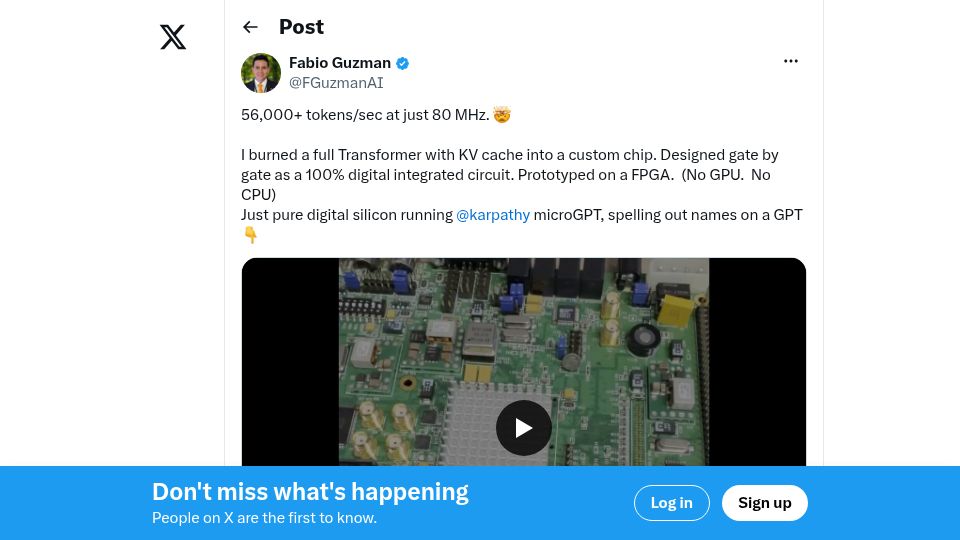
GateGPT: 56k tokens per second Transformer (KV cache) on FPGA at 80 MHz(twitter.com)27 points by laxmena 4 months ago | 8 comments
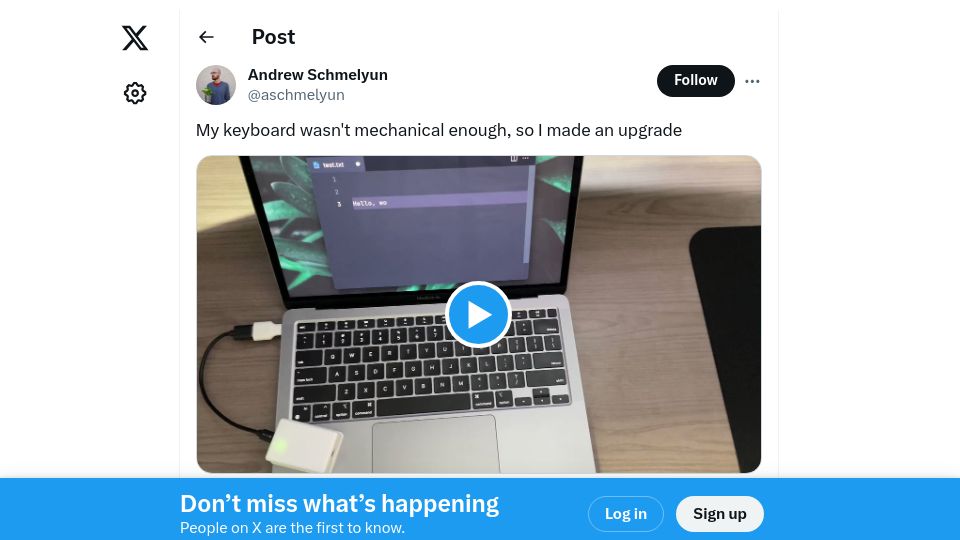
My keyboard wasn't mechanical enough, so I upgraded to a rotary phone(twitter.com)49 points by aschmelyun 2 years ago | 15 comments
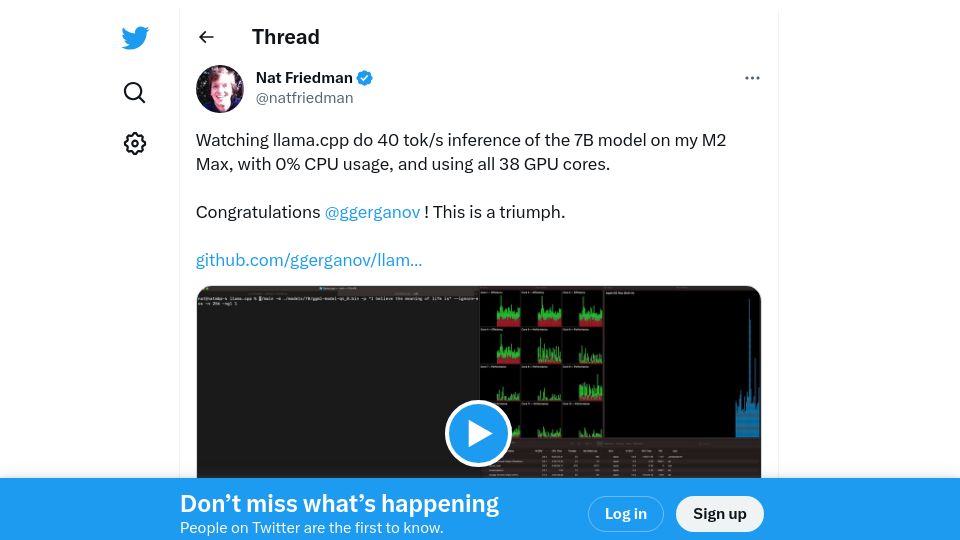
Llama.cpp can do 40 tok/s on M2 Max, 0% CPU usage, using all 38 GPU cores(twitter.com)40 points by samwillis 3 years ago | 9 comments
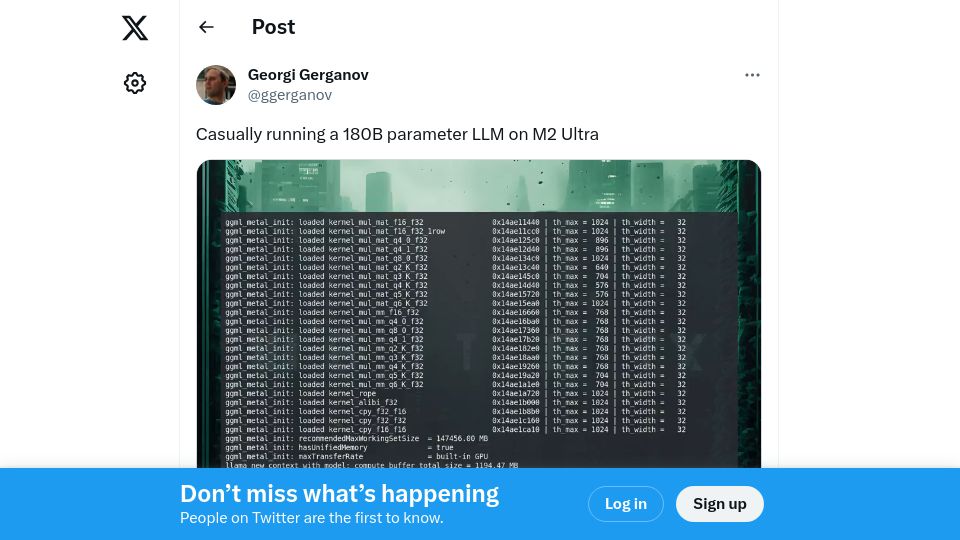
Running a 180B parameter LLM on a single Apple M2 Ultra(twitter.com)209 points by tbruckner 3 years ago | 109 comments