Matrix-vector multiplication implemented in off-the-shelf DRAM for Low-Bit LLMs(arxiv.org)193 points by cpldcpu 1 year ago | 46 comments
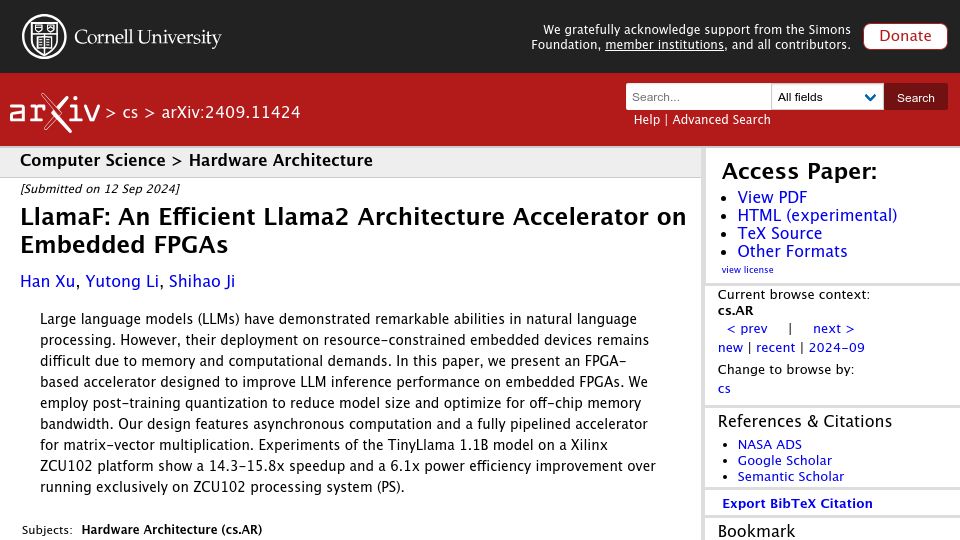
LlamaF: An Efficient Llama2 Architecture Accelerator on Embedded FPGAs(arxiv.org)110 points by PaulHoule 2 years ago | 28 comments
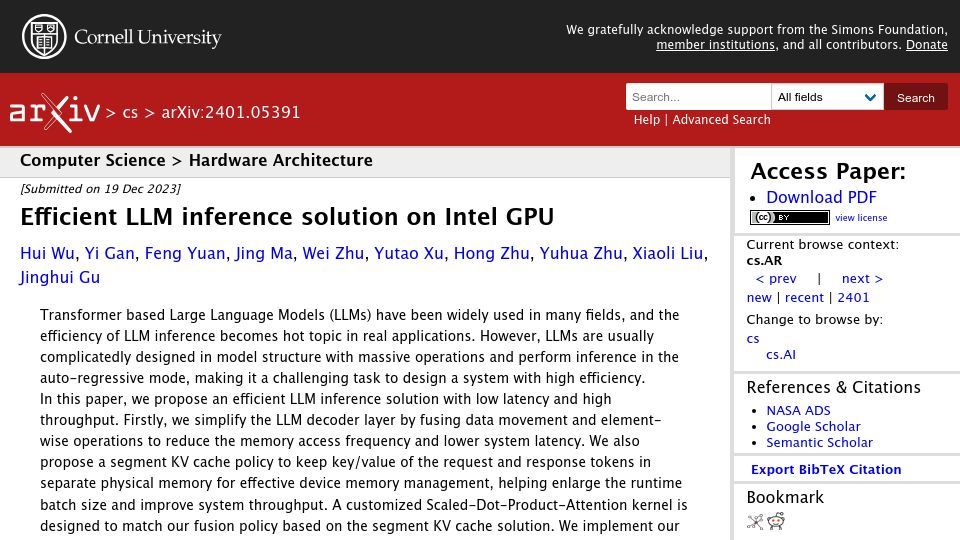
Efficient LLM inference solution on Intel GPU(arxiv.org)87 points by PaulHoule 2 years ago | 20 comments