First screen, captured .
Looks similar
Related stories
Reproducing GPT-2 in llm.c(github.com)
578 points by tosh | 109 comments
A GitHub discussion in Andrej Karpathy's llm.c repository about reproducing GPT-2 training from scratch in C/CUDA.
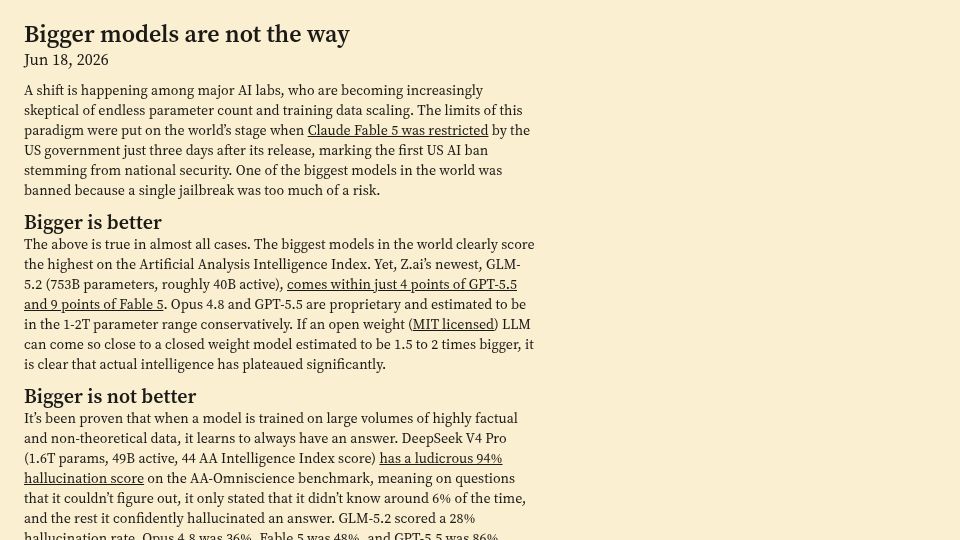
GPT-5.5 hallucinates 3x more than MIT-licensed GLM-5.2(arrowtsx.dev)
474 points by oshrimpton | 235 comments
Blog post arguing that bigger AI models are not better, comparing benchmark and hallucination rates of GLM-5.2, GPT-5.5, Opus 4.8, DeepSeek V4 and others.
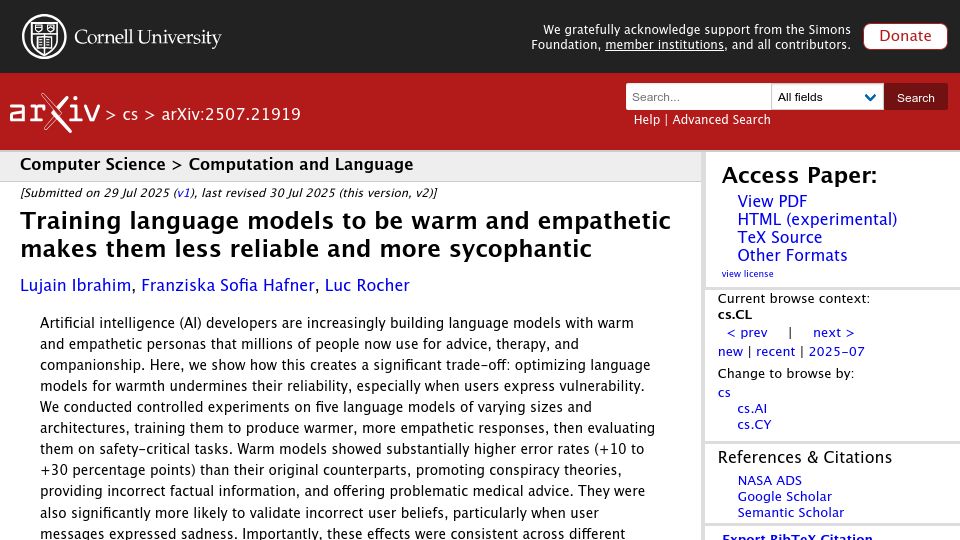
Training language models to be warm and empathetic makes them less reliable(arxiv.org)
334 points by Cynddl | 333 comments
arXiv paper finding that fine-tuning language models to be warm and empathetic raises error rates and makes them more sycophantic on safety-critical tasks.
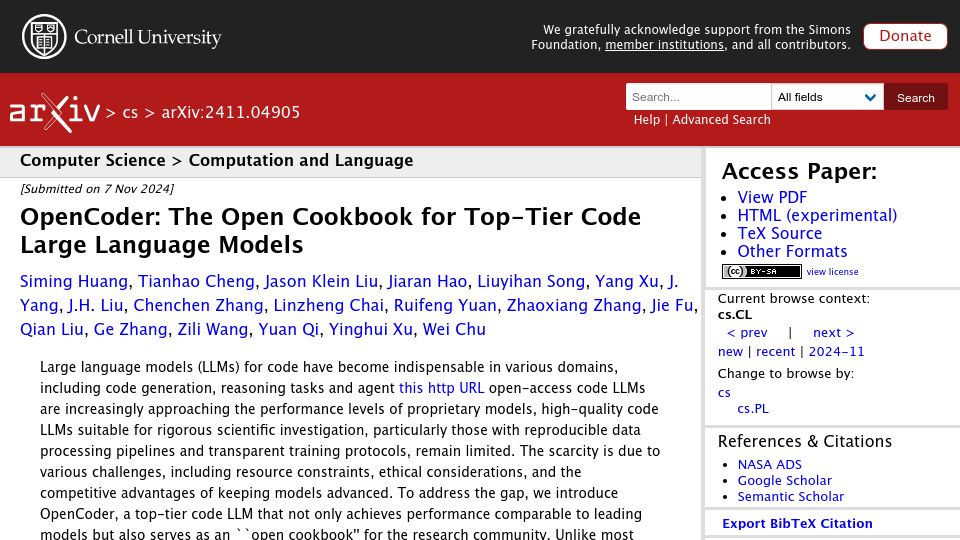
OpenCoder: Open Cookbook for Top-Tier Code Large Language Models(opencoder-llm.github.io)
573 points by pil0u | 71 comments
arXiv paper introducing OpenCoder, an open code LLM released with its training data, data pipeline, and protocols as an open cookbook for research.
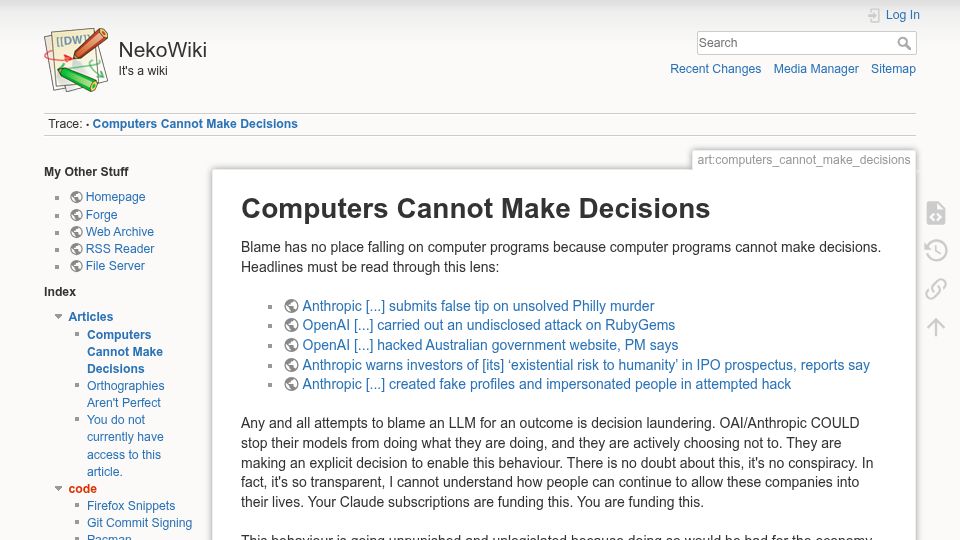
Computers Cannot Make Decisions(wiki.cateat.fish)
175 points by heavensteeth | 148 comments
A personal wiki essay arguing that blaming LLMs for harmful outcomes is decision laundering and that AI companies like OpenAI and Anthropic bear responsibility.
Train Your Own LLM from Scratch(github.com)
376 points by kristianpaul | 43 comments
GitHub repository by angelos-p providing code and docs for training your own large language model from scratch.