First screen, captured .
Looks similar
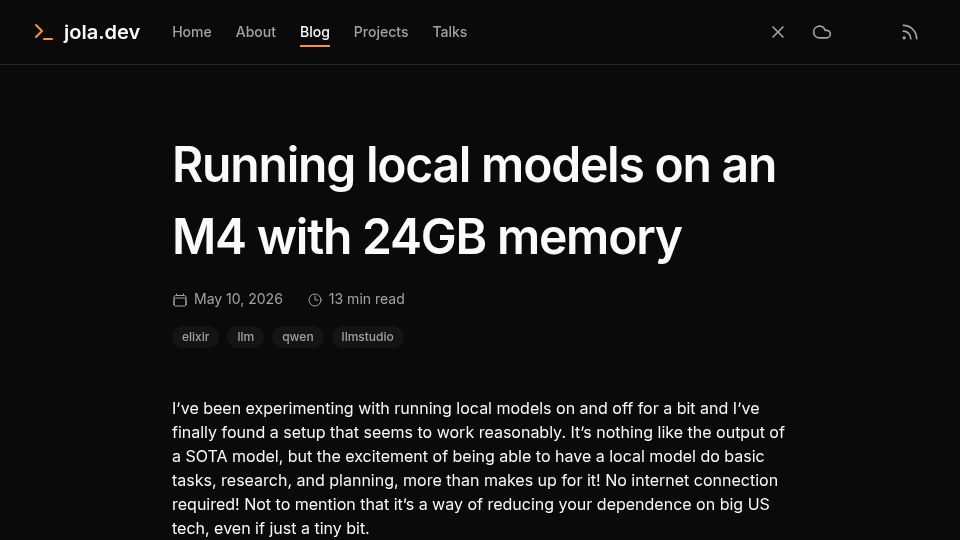
Running local models on an M4 with 24GB memory(jola.dev)
525 points by shintoist | 156 comments
A blog post describing a setup for running local LLMs such as Qwen via LM Studio on an Apple M4 Mac with 24GB of memory.
4-Bit Quantization and QLoRA(huggingface.co)
25 points by tosh | 5 comments