First screen, captured .
Looks similar
Learning to Reason with LLMs(openai.com)
1573 points by fofoz | 1186 comments
OpenAI research post introducing o1, a large language model trained with reinforcement learning to reason using a long internal chain of thought before answering.
The Deep Research problem(ben-evans.com)
275 points by cratermoon | 118 comments
Tailscale didn't stop the Hugging Face intrusion(tailscale.com)
556 points by bluehatbrit | 206 comments
Tailscale blog post discussing a security intrusion at Hugging Face and explaining that Tailscale did not prevent it.
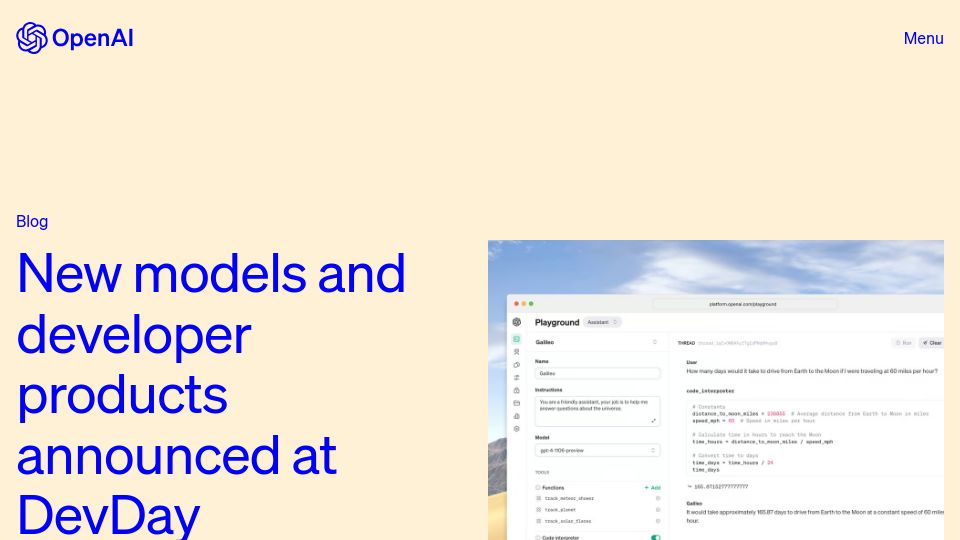
New models and developer products(openai.com)
1081 points by kevin_hu | 521 comments
OpenAI blog post announcing new models and developer products at DevDay, including GPT-4 Turbo and the Assistants API.