Are AI labs pelicanmaxxing?(dylancastillo.co)
632 points by dcastm | 237 comments
Blog post investigating whether AI labs are optimizing their LLMs for Simon Willison's 'SVG of a pelican riding a bicycle' informal benchmark.
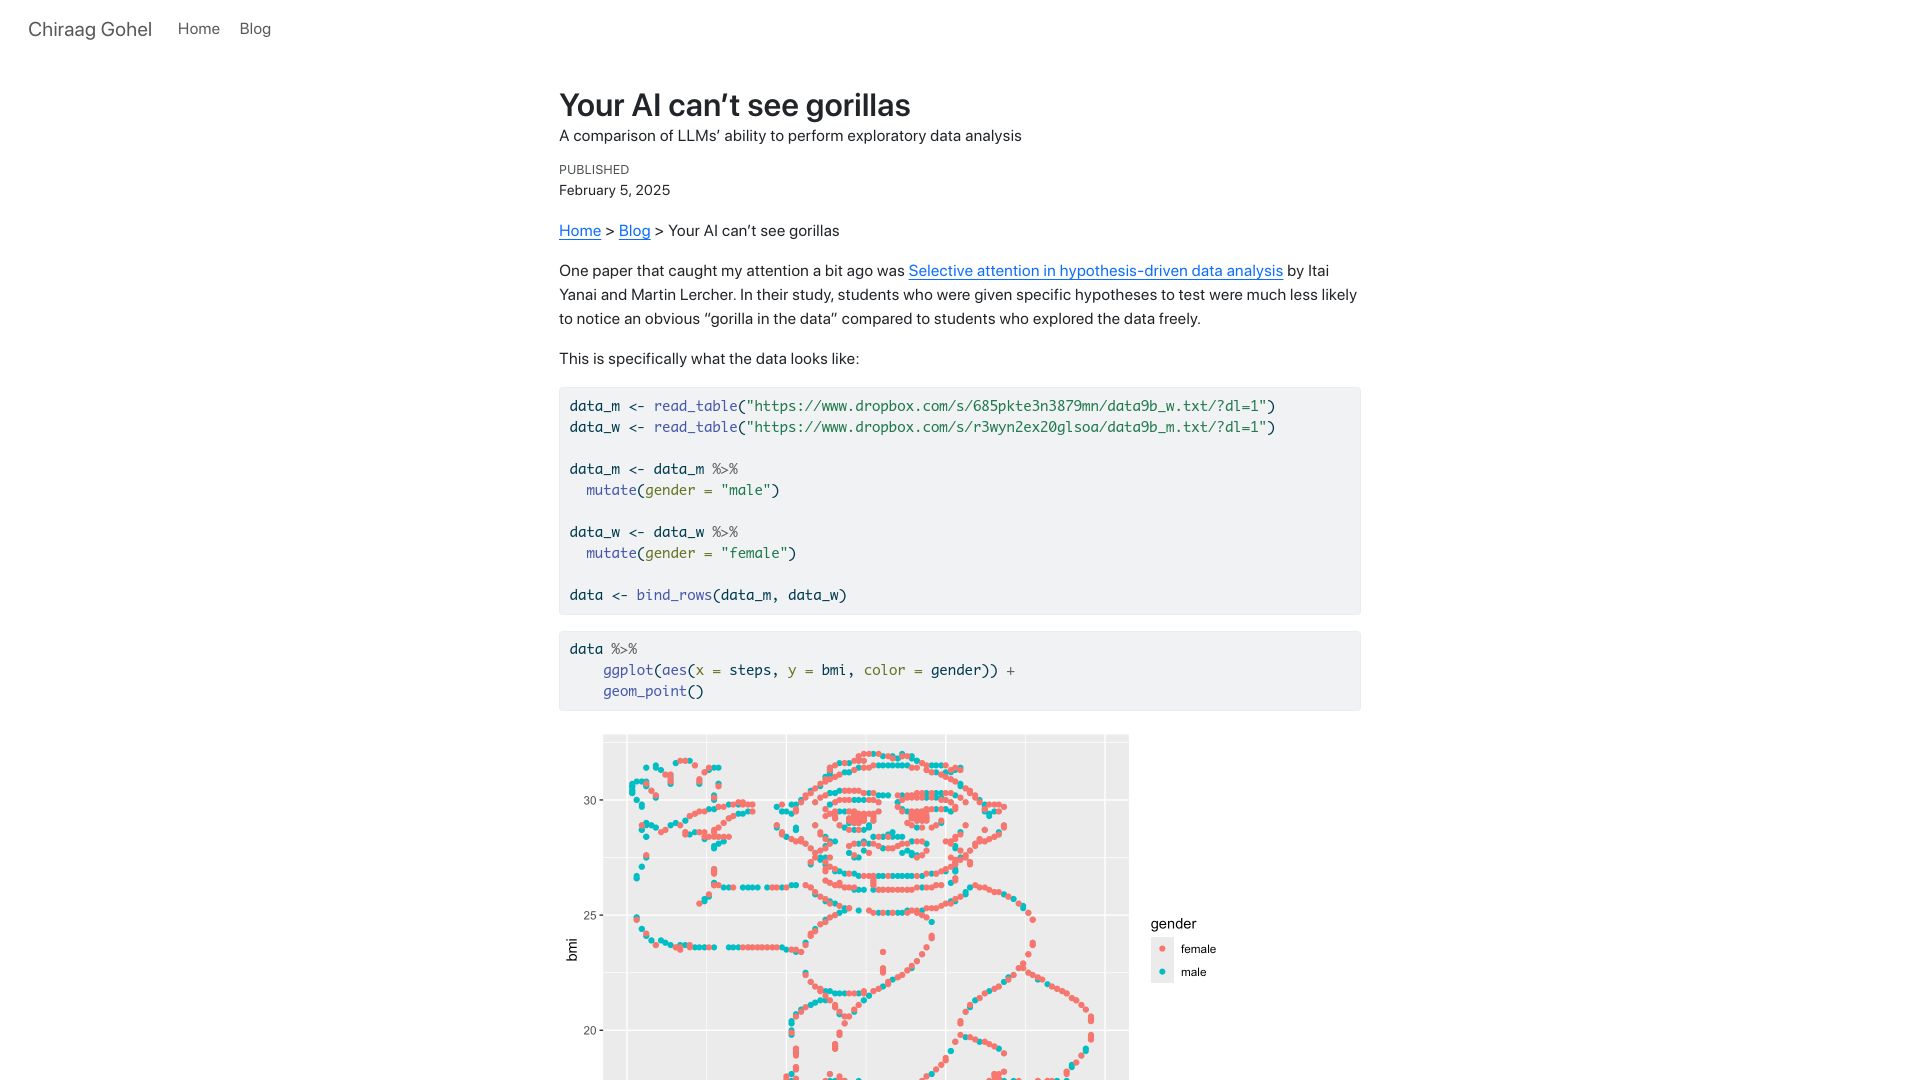
First screen, captured .
632 points by dcastm | 237 comments
Blog post investigating whether AI labs are optimizing their LLMs for Simon Willison's 'SVG of a pelican riding a bicycle' informal benchmark.
802 points by jasondavies | 320 comments
Databricks blog post from the Mosaic Research team announcing DBRX, a new open large language model claimed to be state-of-the-art.
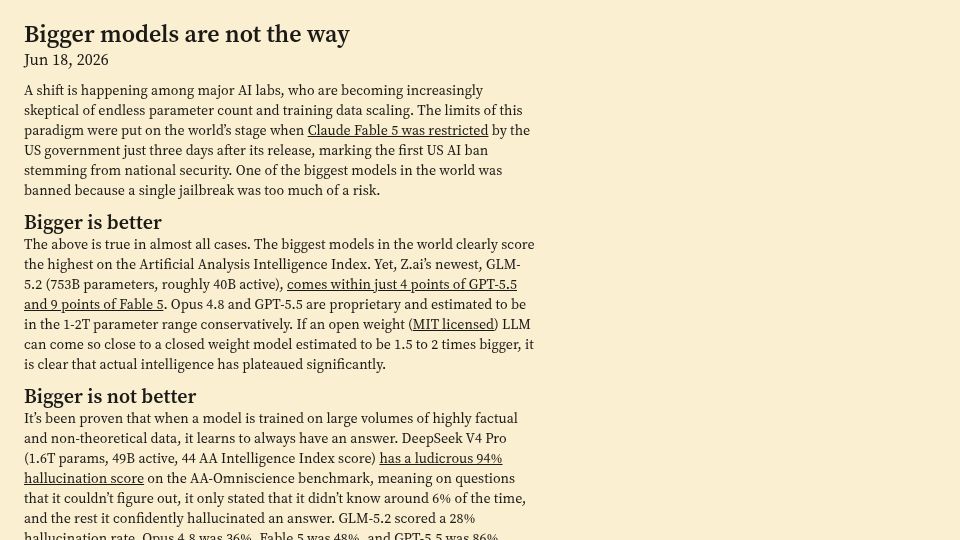
474 points by oshrimpton | 235 comments
Blog post arguing that bigger AI models are not better, comparing benchmark and hallucination rates of GLM-5.2, GPT-5.5, Opus 4.8, DeepSeek V4 and others.
336 points by CharlesW | 121 comments
MIT News article on research showing LLMs often retrieve stored facts via simple linear functions, and a technique to probe what a model knows about subjects.
404 points by pretext | 217 comments
Z.ai research blog post announcing GLM-4.7, a language model with improved agentic coding, terminal tasks, and UI generation, with benchmark results.
541 points by antirez | 365 comments
Blog post by antirez (Redis creator) giving an update on how he uses frontier LLMs like Gemini 2.5 Pro and Claude for programming in summer 2025.
27 points by rizsyed1 | 32 comments
Blog post by Iris Meredith on deadSimpleTech arguing that AI and LLM adoption is not inevitable, calling the claim a thought-terminating cliché.