Search-R1: Training LLMs to Reason and Leverage Search Engines with RL(arxiv.org)87 points by jonbaer 1 year ago | 9 comments
Absolute Zero: Reinforced Self-Play Reasoning with Zero Data(arxiv.org)63 points by leodriesch 1 year ago | 15 comments
Evolving Reservoirs for Meta Reinforcement Learning(arxiv.org)50 points by PaulHoule 2 years ago | 4 comments
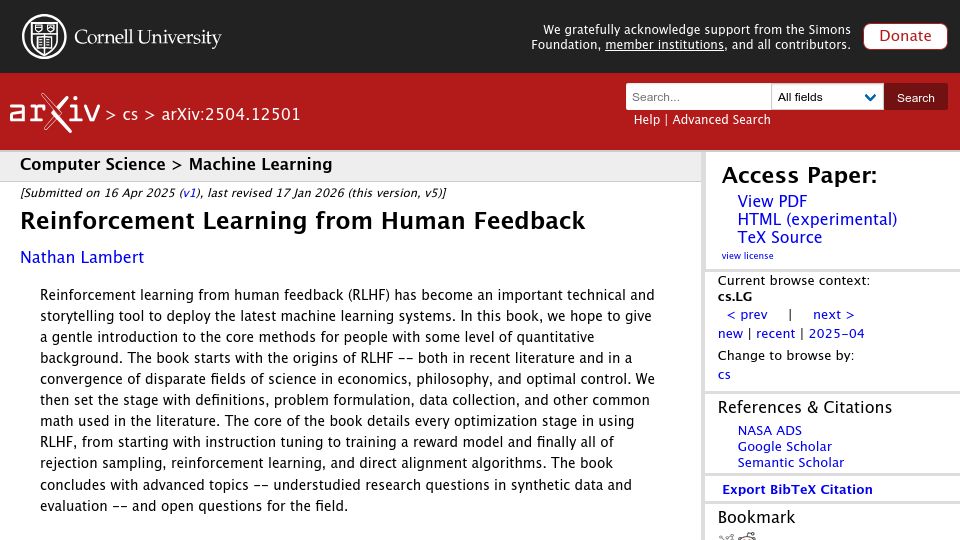
Reinforcement Learning from Human Feedback(rlhfbook.com)118 points by onurkanbkrc 8 months ago | 5 comments
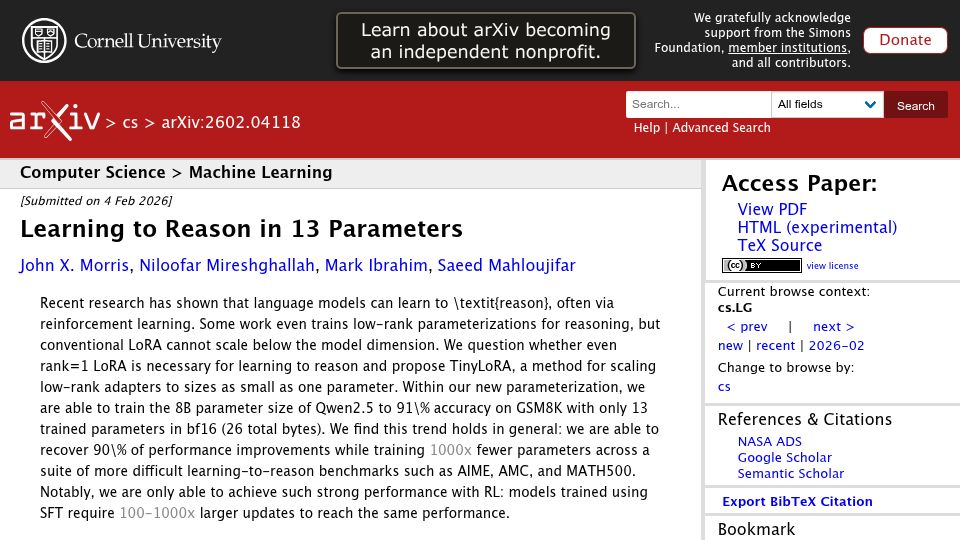
TinyLoRA – Learning to Reason in 13 Parameters(arxiv.org)227 points by sorenjan 7 months ago | 42 comments
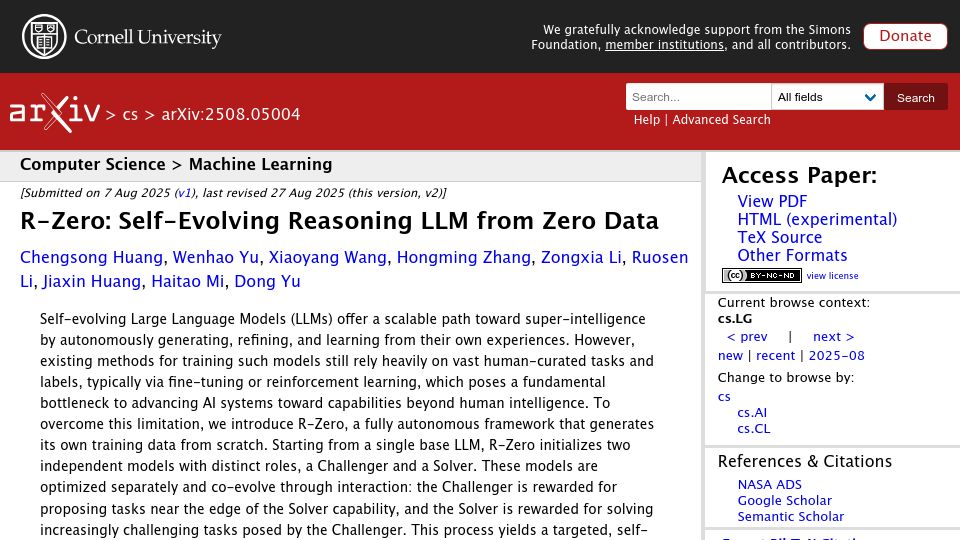
R-Zero: Self-Evolving Reasoning LLM from Zero Data(arxiv.org)102 points by lawrenceyan 1 year ago | 53 comments