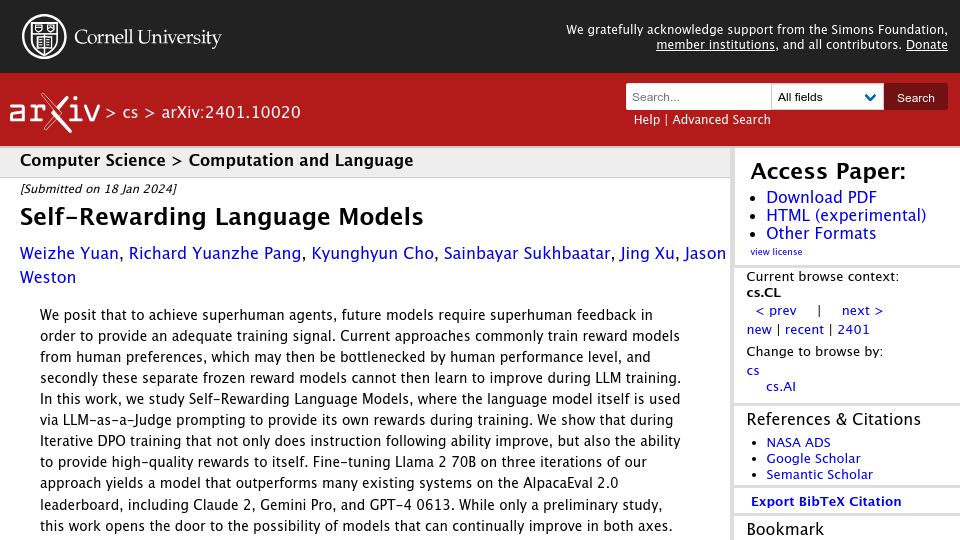
Self-Rewarding Language Models(arxiv.org)
56 points by jph00 | 49 comments
First screen, captured .
56 points by jph00 | 49 comments
339 points by fofoz | 103 comments
arXiv paper introducing LADDER, a framework where LLMs self-improve by recursively generating simpler problem variants, plus TTRL test-time reinforcement learning.
135 points by schmuhblaster | 23 comments