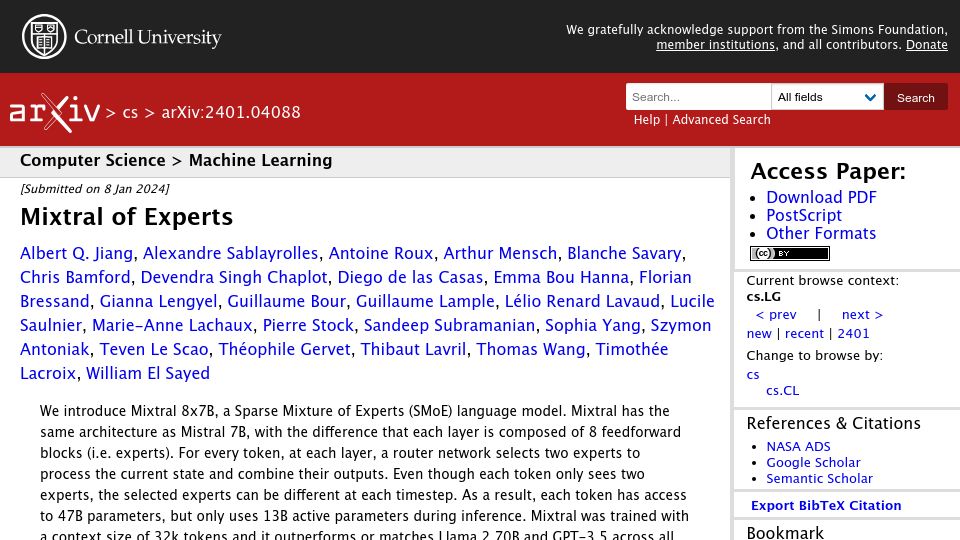
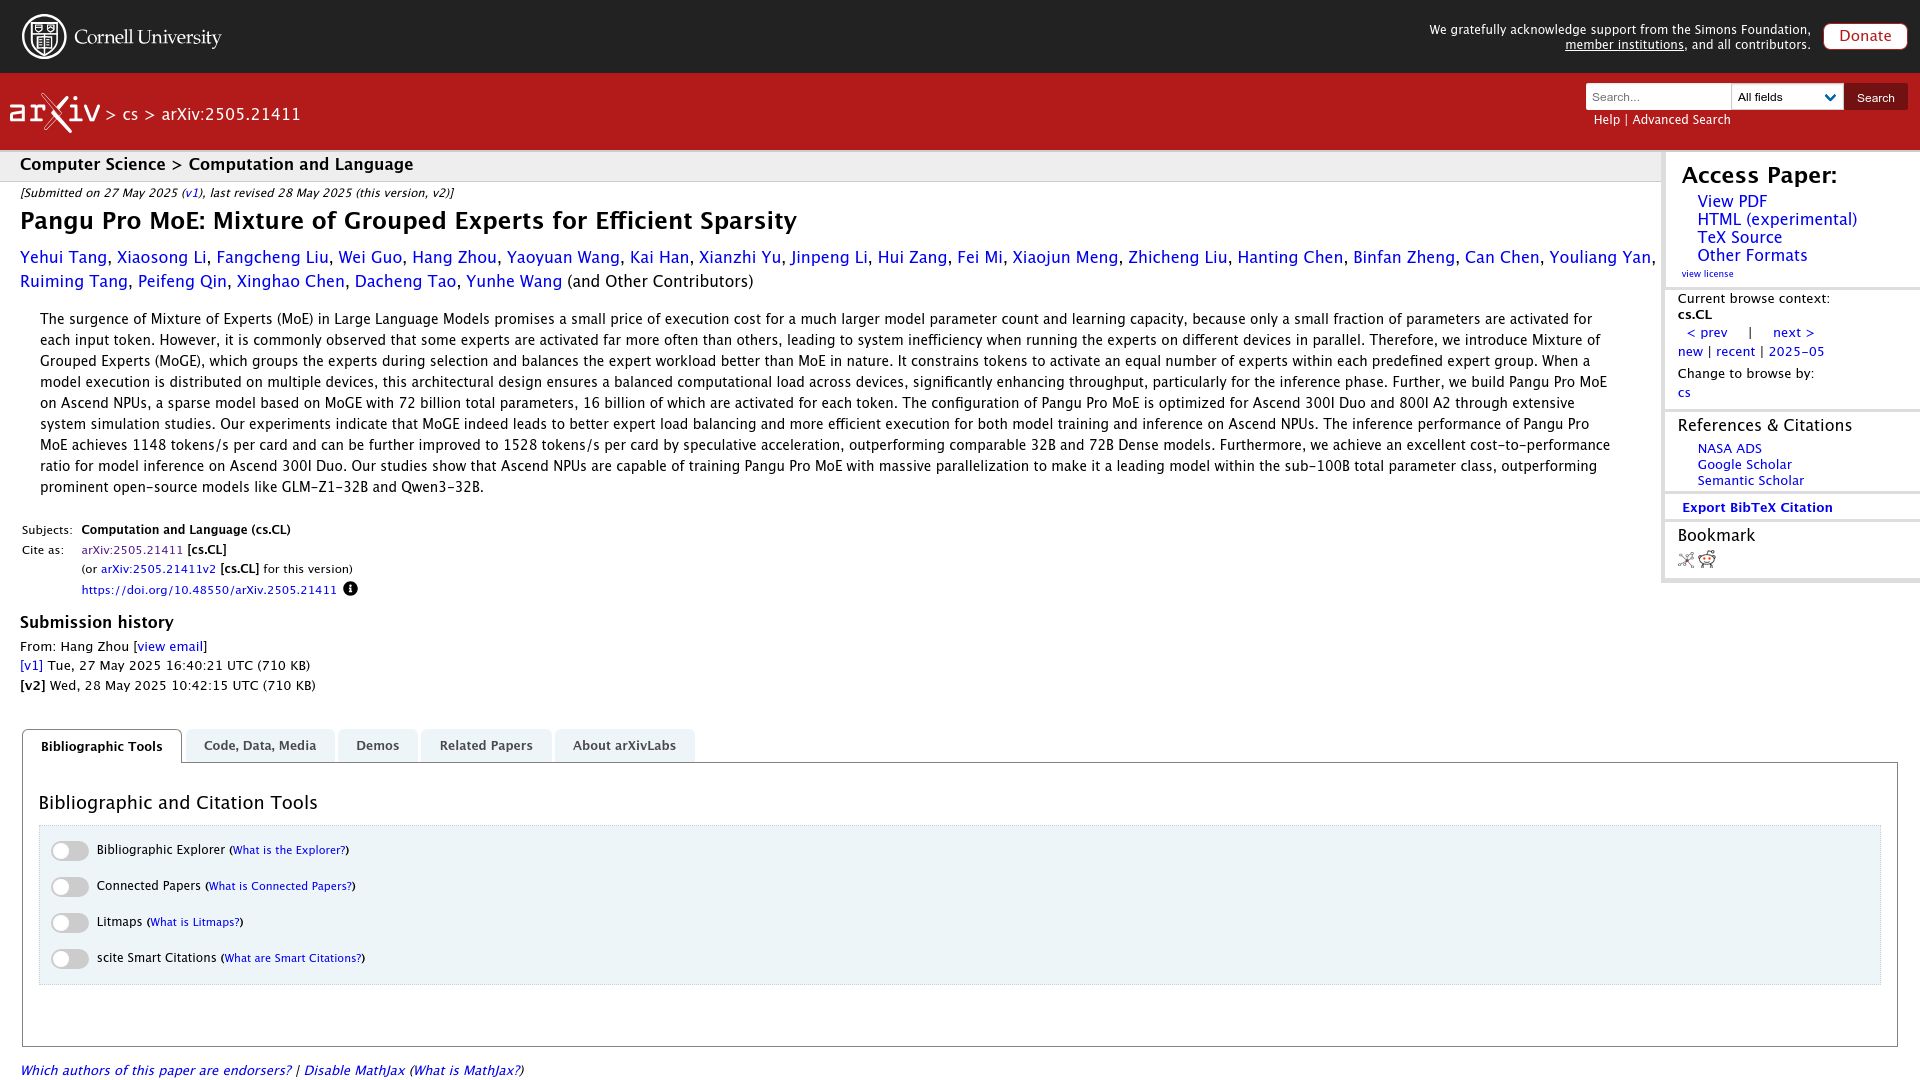
First screen, captured .
Looks similar
Scalable MatMul-Free Language Modeling(arxiv.org)
177 points by lykahb | 27 comments
Parametric Matrix Models(arxiv.org)
50 points by evanb | 5 comments
First screen, captured .
177 points by lykahb | 27 comments
50 points by evanb | 5 comments