First screen, captured .
Looks similar
LFM2.5-24B-A2B: Built for fast on-device agents(liquid.ai)
271 points by gmays | 72 comments
Liquid AI blog post announcing LFM2.5-24B-A2B, a sparse language model with about 2B active parameters designed for fast on-device agents.
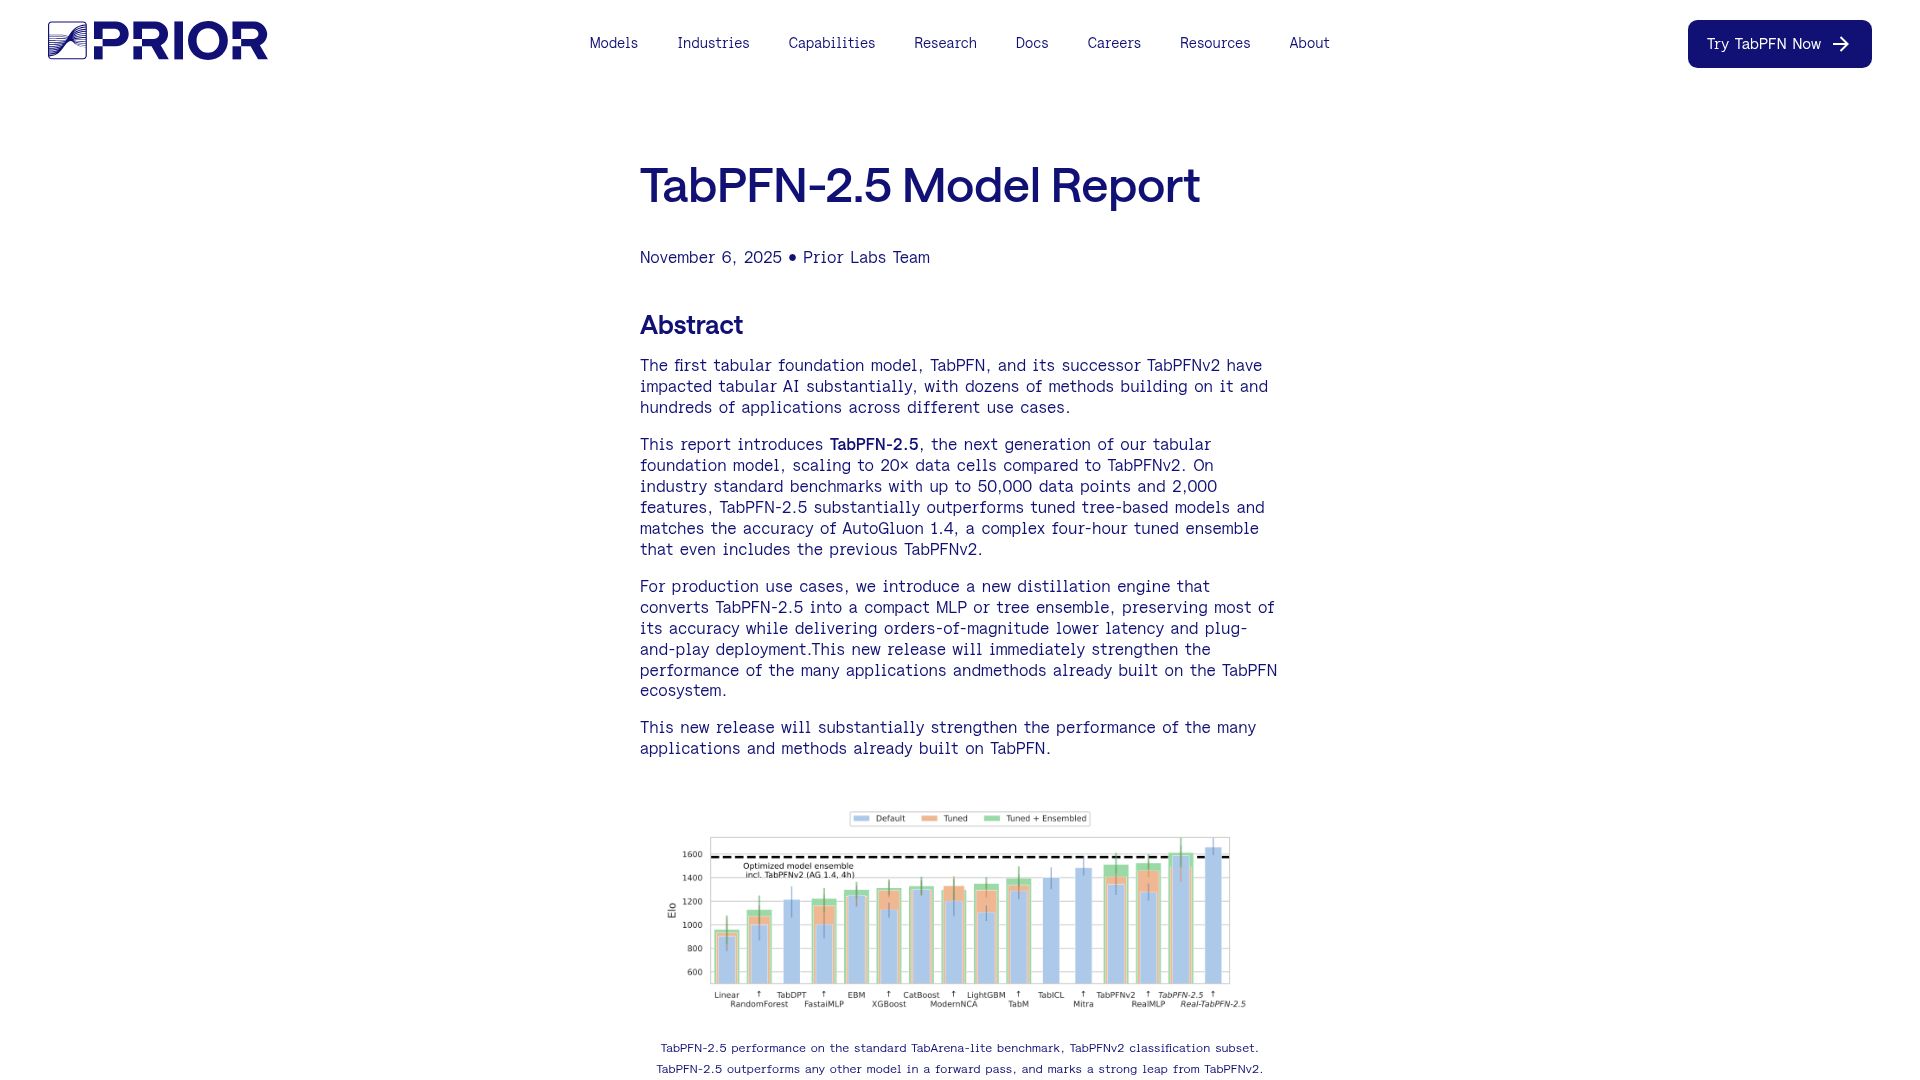
TabPFN and TabICL vs. tuned XGBoost: the model that doesn't train won 14/14(efraingaray.com)
21 points by EfrainGaray | 9 comments
Blog post benchmarking TabPFN and TabICL foundation models against tuned XGBoost on fourteen tabular datasets, finding the no-training models won all fourteen.