First screen, captured .
Looks similar
TabPFN and TabICL vs. tuned XGBoost: the model that doesn't train won 14/14(efraingaray.com)
21 points by EfrainGaray | 9 comments
Blog post benchmarking TabPFN and TabICL foundation models against tuned XGBoost on fourteen tabular datasets, finding the no-training models won all fourteen.
The real prices of frontier models(playcode.io)
145 points by ianberdin | 72 comments
Related stories
Claude Fable 5: mid-tier results on coding tasks(endorlabs.com)
373 points by bugvader | 217 comments
Endor Labs blog post benchmarking Claude Fable 5 on 200 real-world coding tasks for its Agent Security League, reporting middling functional and security results.
Gemini: Google's most capable AI model yet(blog.google)
711 points by tosh | 415 comments
Google blog post by Sundar Pichai and Demis Hassabis announcing Gemini, Google's largest and most capable AI model, dated December 6, 2023.
GPT 5.6 Sol is the best "vision" model OpenAI ever released(blog.roboflow.com)
355 points by plurby | 164 comments
Roboflow blog post evaluating OpenAI's GPT 5.6 Sol model on vision tasks such as object detection and OCR, calling it OpenAI's best vision model.
Claude Fable 5(anthropic.com)
2521 points by Philpax | 2018 comments
Anthropic announcement post introducing two new AI models, Claude Fable 5 and Claude Mythos 5, dated June 9, 2026, with a linked system card.
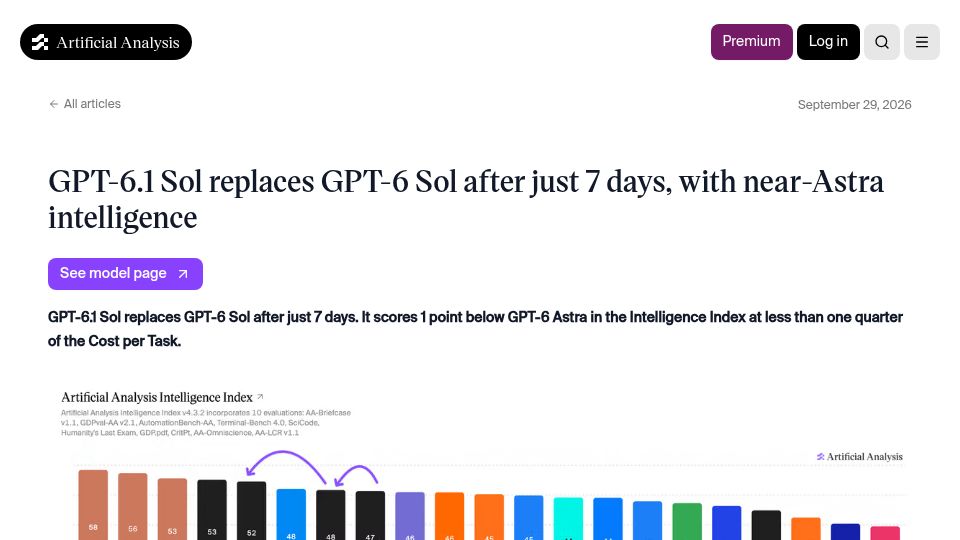
GPT-6.1 Sol replaces GPT-6 Sol after just 7 days, with near-Astra intelligence(artificialanalysis.ai)
46 points by theanonymousone | 48 comments
Artificial Analysis article reporting that GPT-6.1 Sol replaces GPT-6 Sol after 7 days, scoring near GPT-6 Astra on its Intelligence Index at under a quarter of the cost.
Opus 4.5 is not the normal AI agent experience that I have had thus far(burkeholland.github.io)
797 points by tbassetto | 1203 comments
Burke Holland's blog post arguing that Anthropic's Claude Opus 4.5 is a step change in AI coding agent experience.