Harbor github.com ↗
A framework for running agent evaluation task suites.
ToolAI & MLevalsbenchmarkingagents
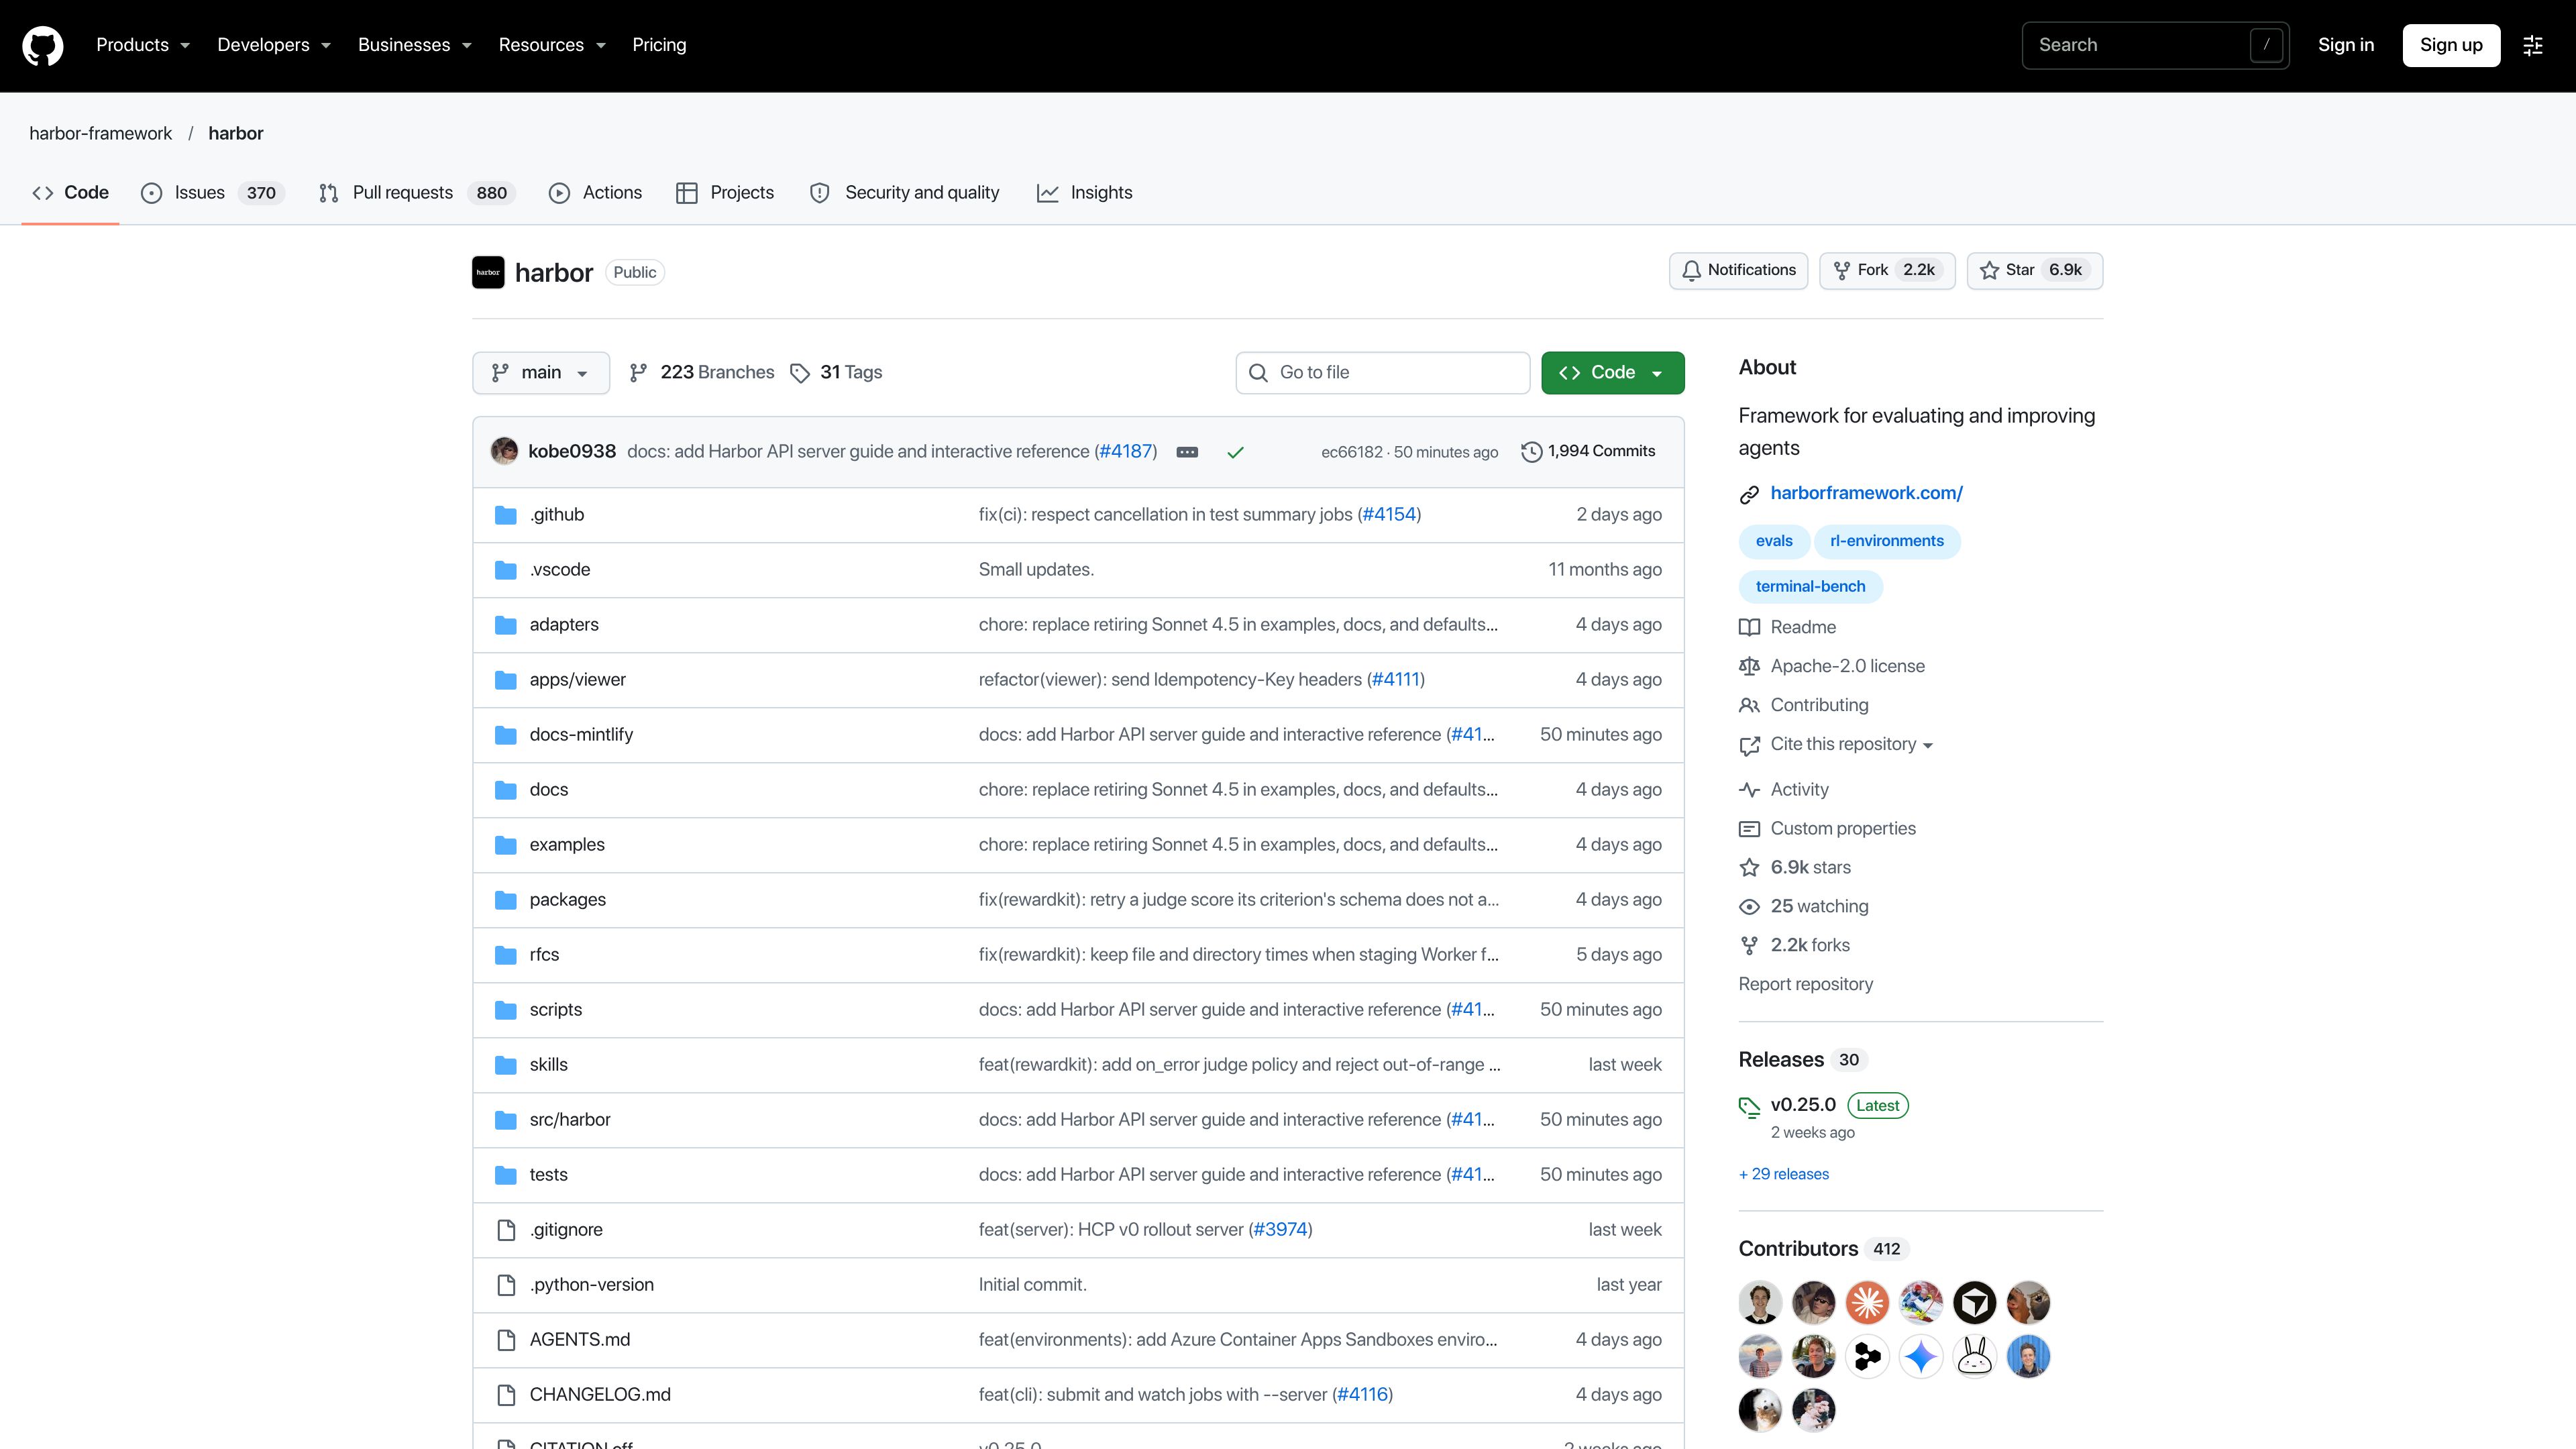
Captured
Recommended in 1 thread
 Muse Ember: Our smallest, most efficient model
research.meta.ai ·
Suggested for building custom, workload-specific evals.
Similar tools
- 1 thread
- DataAgentBench ↗AI & ML1 thread
A UC Berkeley benchmark and leaderboard for data agents that query multiple sources.
- 3 threads
- 4 threads
- TaxCalcBench ↗AI & ML1 thread
An open benchmark from Column Tax for evaluating AI models on tax calculations.
- 0 threads
- Artificial Analysis ↗AI & ML7 threads
A site benchmarking and comparing AI models on quality, price and speed.
- 1 thread
Also in AI & ML
- 19 threads
- 12 threads
- 12 threads
- 11 threads
- 9 threads
- 8 threads
- 7 threads
- 7 threads
- 5 threads
- 5 threads
- 4 threads
- 4 threads
Link from a commenter, not checked or endorsed by us: ↗ https://github.com/harbor-framework/harbor