llama-swap github.com ↗
A proxy that swaps between local LLM inference servers on demand.
ToolAI & MLlocal-inferenceproxymodel-switching
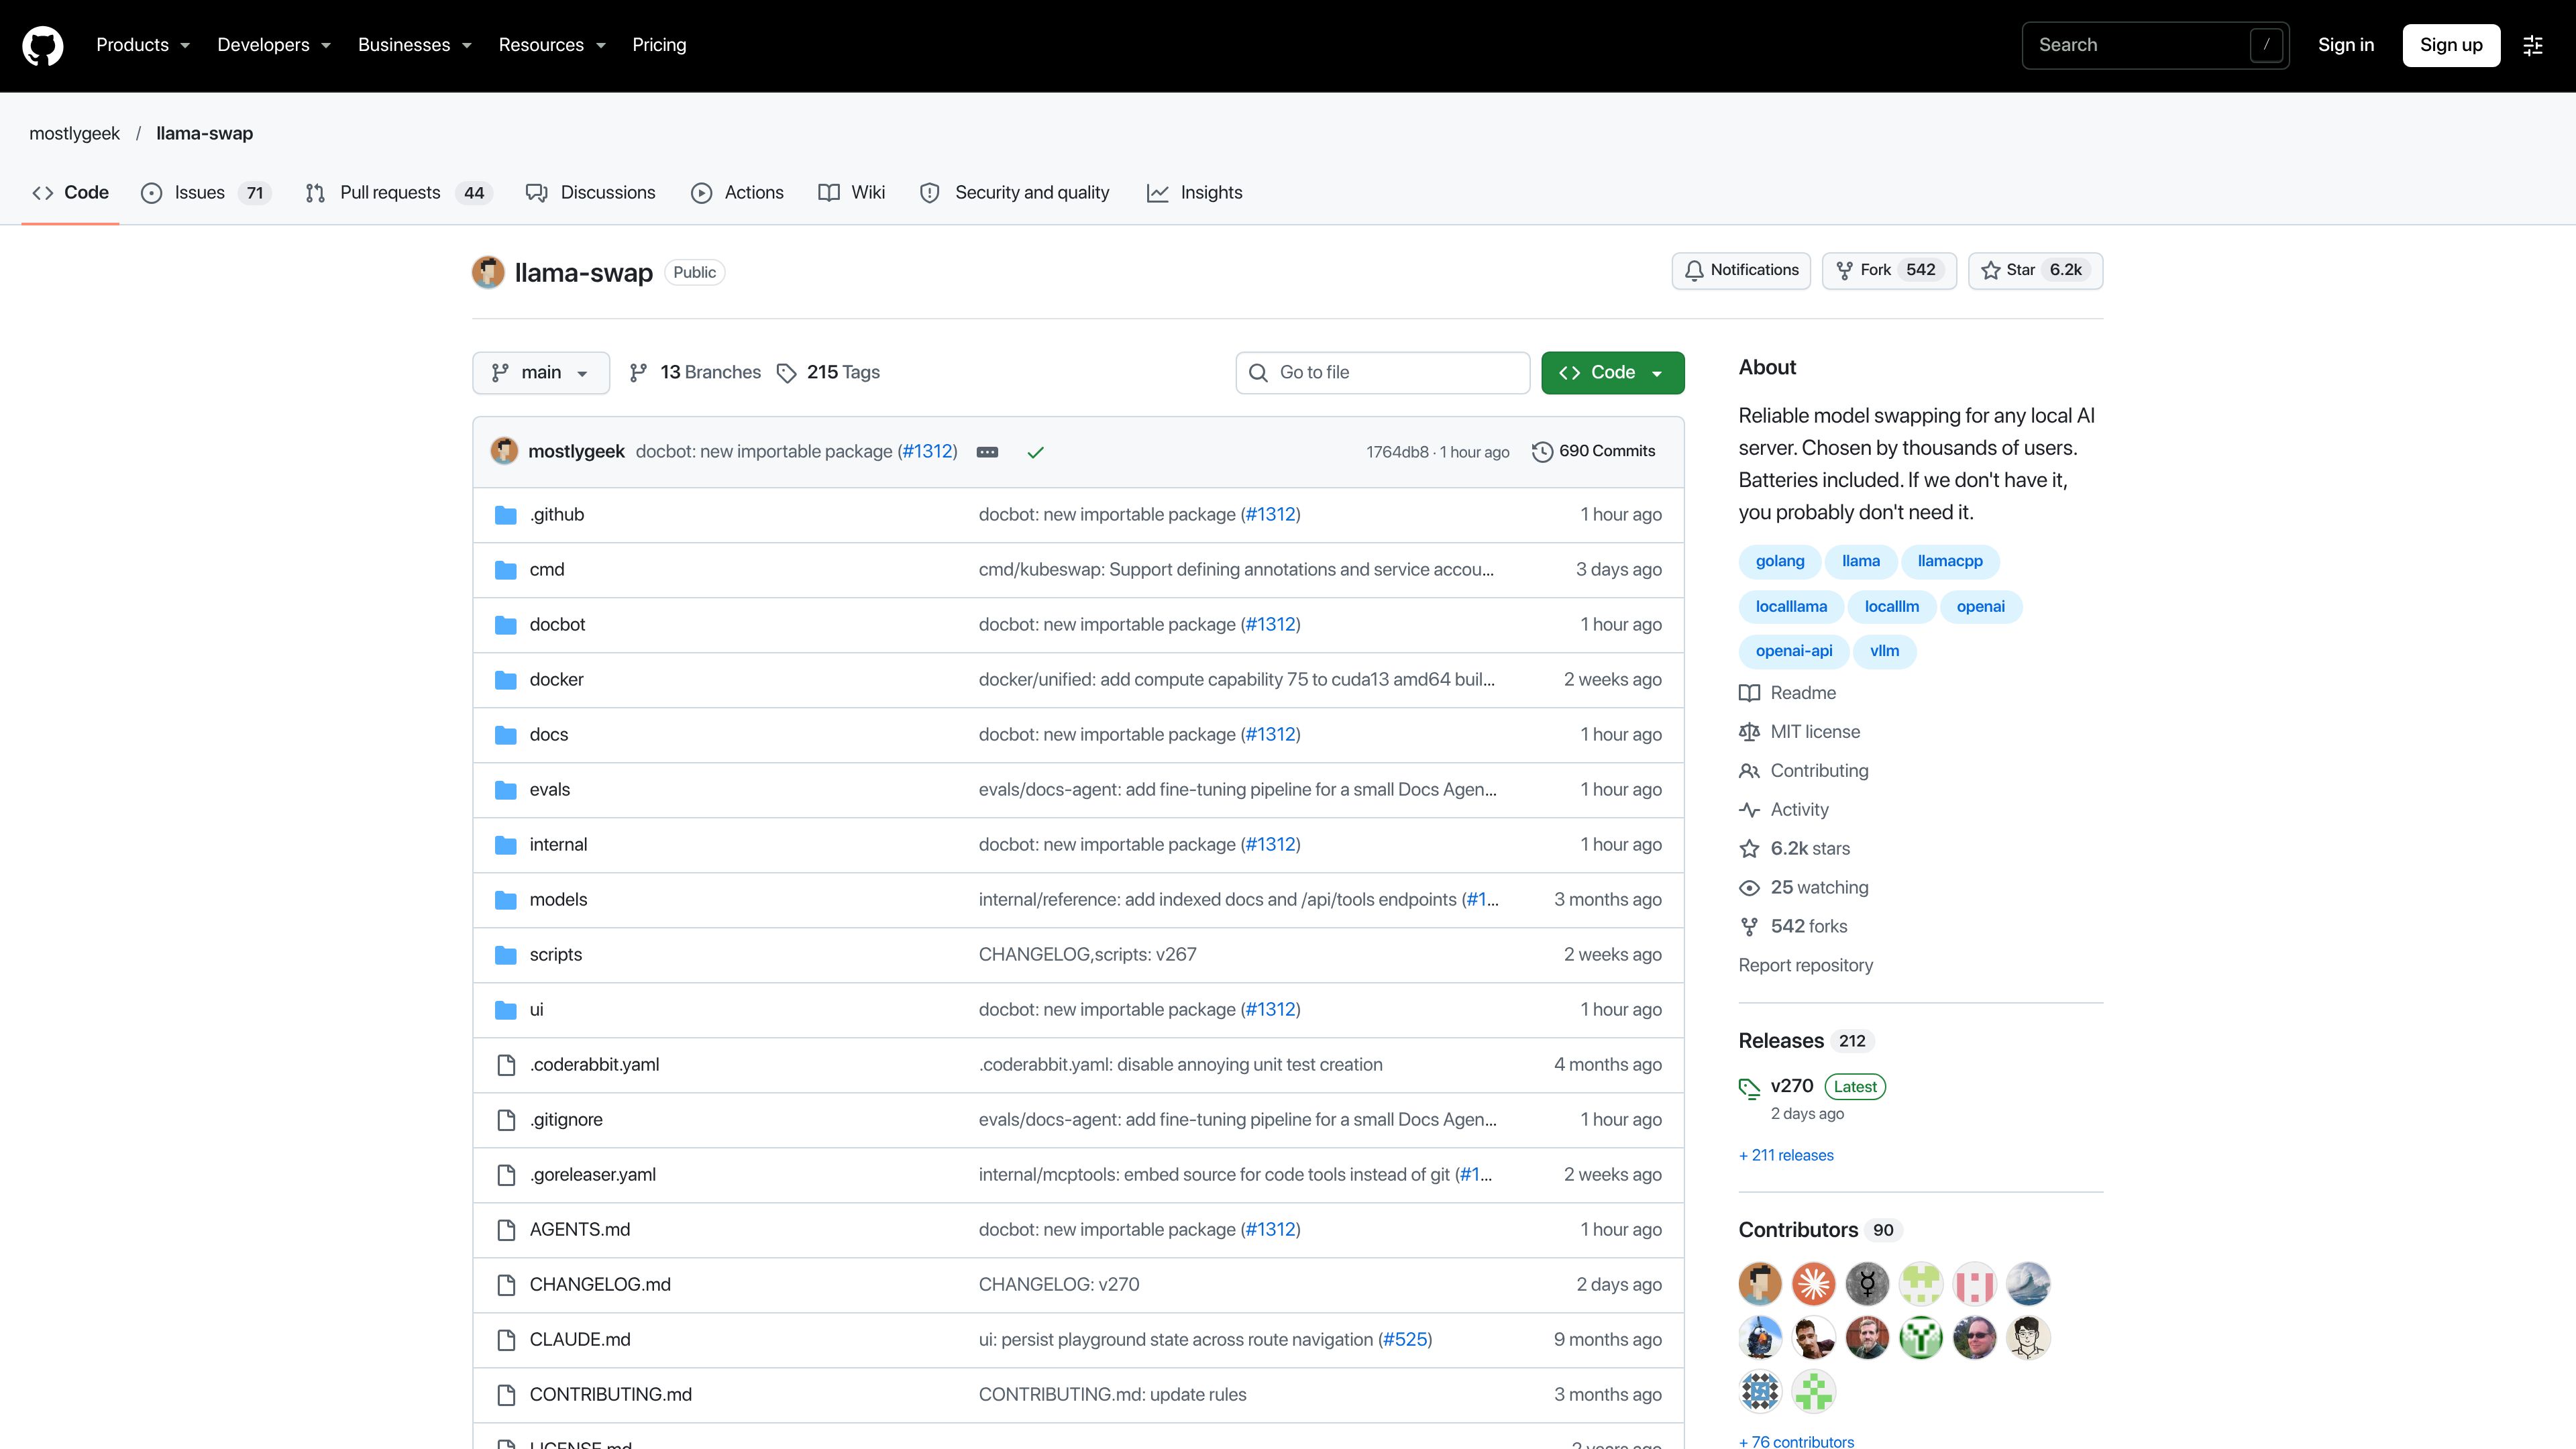
Captured
Recommended in 2 threads
 Llama-modchip: 284B DeepSeek on 64GB RAM, no GPU
github.com ·
Lets users juggle multiple llama.cpp forks transparently.
 Anthropic IPO buyers see valuation as low as $1.1T
bloomberg.com ·
Used to route opencode to a local inference server.
Similar tools
Also in AI & ML
- 19 threads
- 12 threads
- 12 threads
- 11 threads
- 9 threads
- 8 threads
- 7 threads
- 7 threads
- 5 threads
- 5 threads
- 4 threads
- 4 threads
Link from a commenter, not checked or endorsed by us: ↗ https://github.com/mostlygeek/llama-swap