First screen, captured .
Looks similar
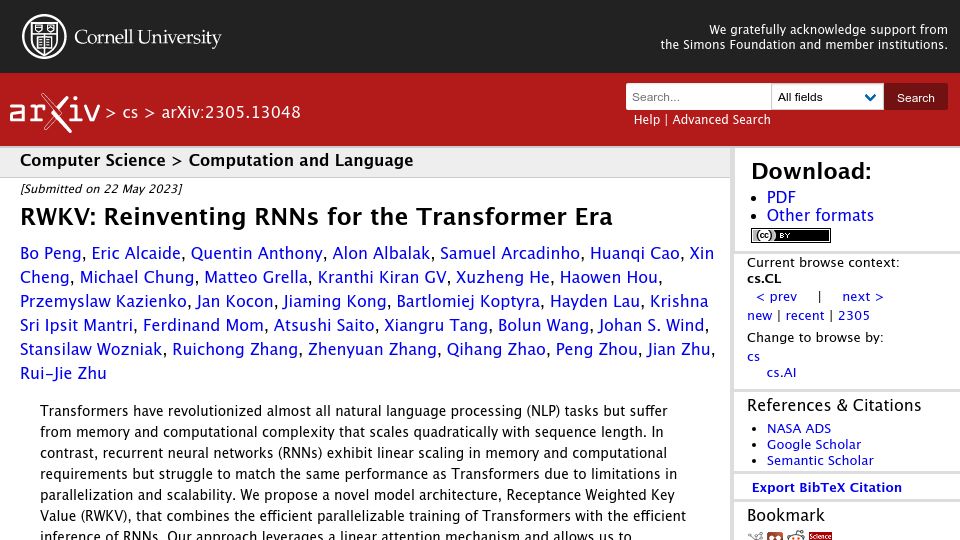
RWKV: Reinventing RNNs for the Transformer Era(arxiv.org)
318 points by ianbutler | 164 comments
arXiv paper introducing RWKV, a model architecture combining Transformer-style parallel training with efficient RNN inference via linear attention.