Attention Is Not What You Need (2025)(arxiv.org)
160 points by westurner | 55 comments
arXiv paper proposing an attention-free sequence model using Grassmann flows and Plucker coordinates, compared against Transformers on Wikitext-2 and SNLI.
59 stories tagged transformers, newest first.
160 points by westurner | 55 comments
arXiv paper proposing an attention-free sequence model using Grassmann flows and Plucker coordinates, compared against Transformers on Wikitext-2 and SNLI.
41 points by gmays | 5 comments
Blog post by Joe Barrow explaining that speculative decoding speeds up LLM inference by changing the kind of GPU work rather than reducing FLOPs.
602 points by speckx | 133 comments
Blog post by Alex Wang explaining transformer layers (MLPs, gated MLPs, self-attention) as associative memory stores, with code and an interactive app.
27 points by baraa_ | 2 comments
An online book guiding readers through building a large language model from scratch in NodeJS and TypeScript, covering dataloaders, embeddings, and attention.
58 points by bcaulfield | 52 comments
Quanta Magazine article exploring whether the attention mechanism is central to intelligence in AI and brains.
269 points by E-Reverance | 79 comments
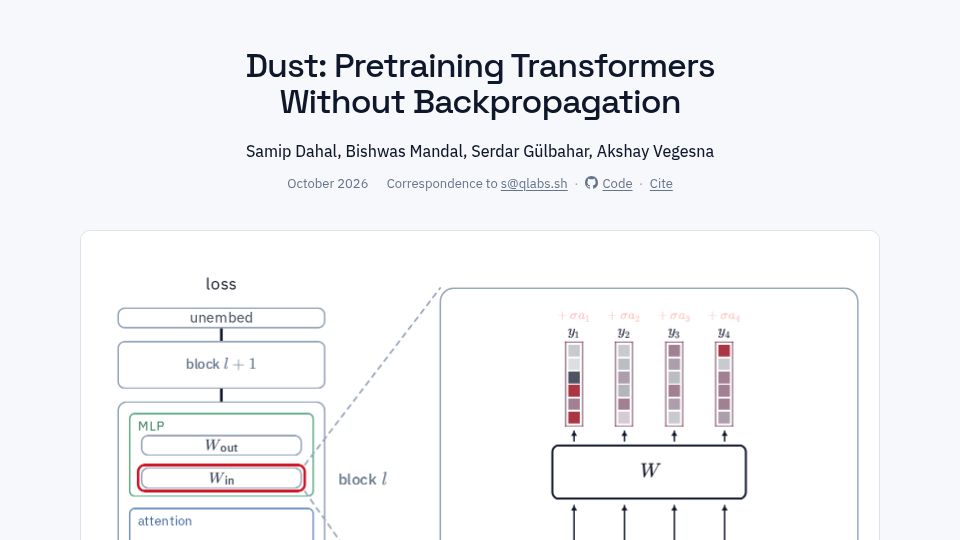
Research page from QLabs presenting Dust, a method for pretraining transformer models without backpropagation, with authors, code link, and architecture diagram.
181 points by Anon84 | 9 comments
Sebastian Raschka's Ahead of AI newsletter post giving a visual guide to text classification, from bag-of-words through RNNs, CNNs, and transformers to Jev-like APIs and calibration.
114 points by keeda | 60 comments
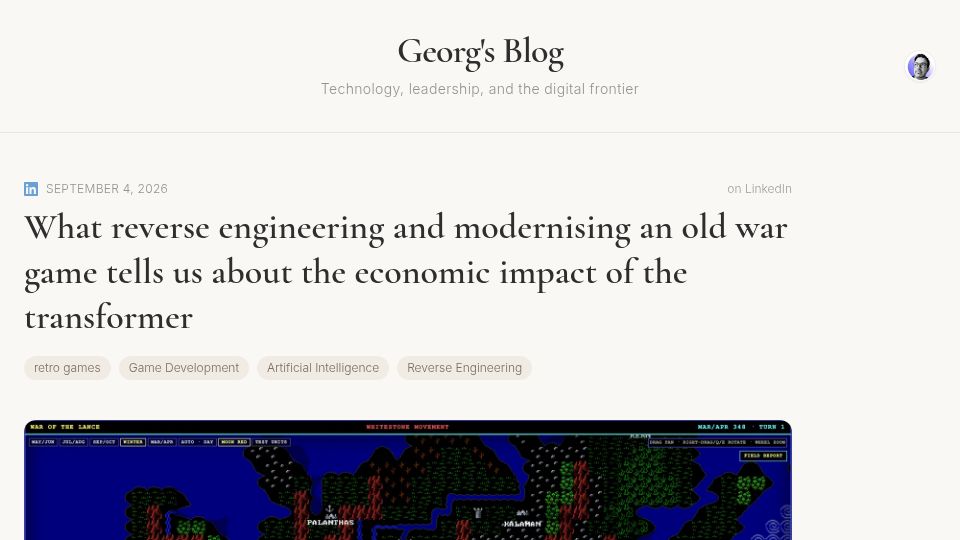
Blog post about reverse engineering and modernising the old war game War of the Lance with AI, and what it suggests about the economic impact of transformers.
576 points by aray07 | 85 comments
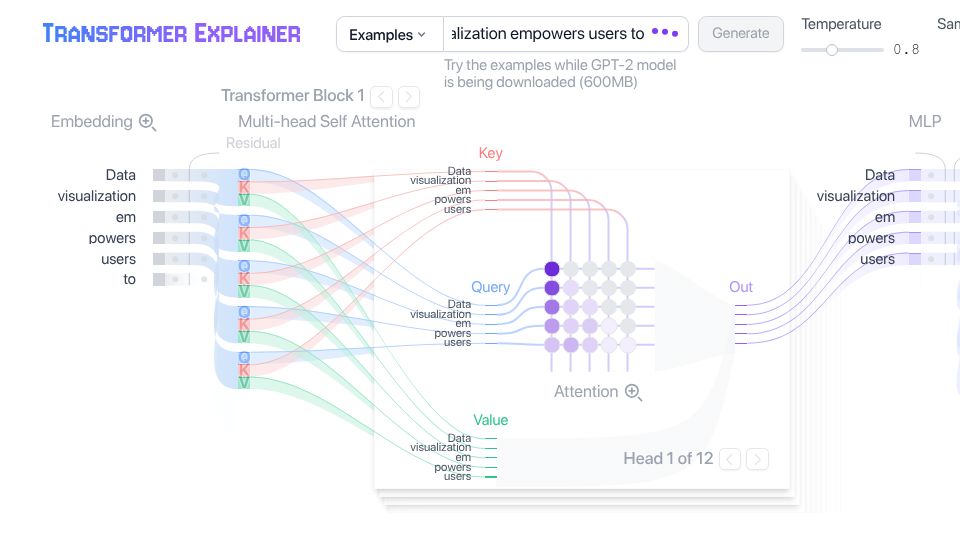
Transformer Explainer is an interactive in-browser visualization that runs GPT-2 and shows how embeddings, multi-head self-attention, and MLP layers process text.
578 points by porridgeraisin | 149 comments
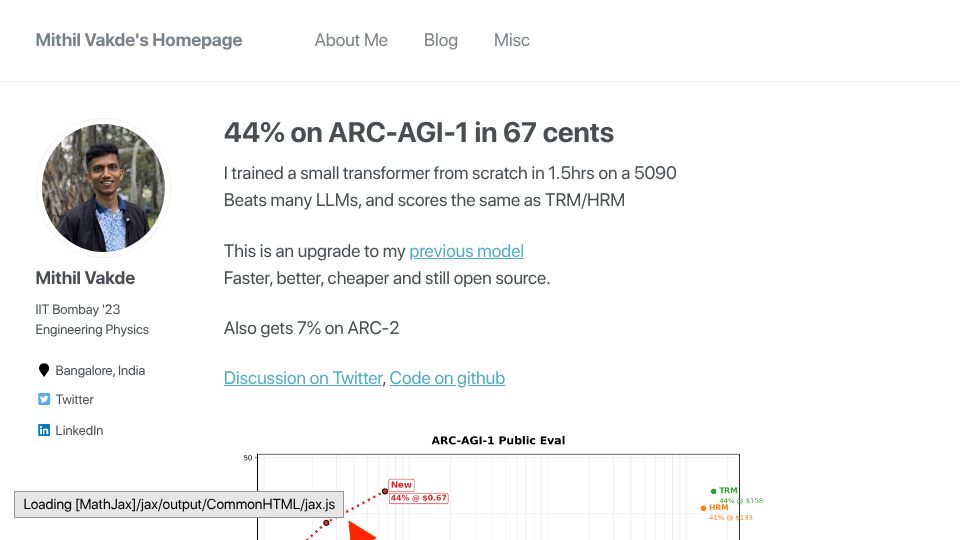
Personal blog post describing a small transformer trained from scratch in 1.5 hours on an RTX 5090 that scores 44% on ARC-AGI-1 for 67 cents.
533 points by simedw | 110 comments
Blog post describing training a 125M-parameter transformer that autocompletes MIDI piano performances in real time on an iPhone, covering representation, data cleaning, and DPO.

834 points by 0xkato | 228 comments
A blog post giving a math-light walkthrough of how transformer-based large language models work internally.
418 points by dagenix | 115 comments
Project page for GenCAD, an MIT research model that generates CAD designs from images using transformer-based contrastive representations and diffusion priors.
459 points by tzury | 34 comments
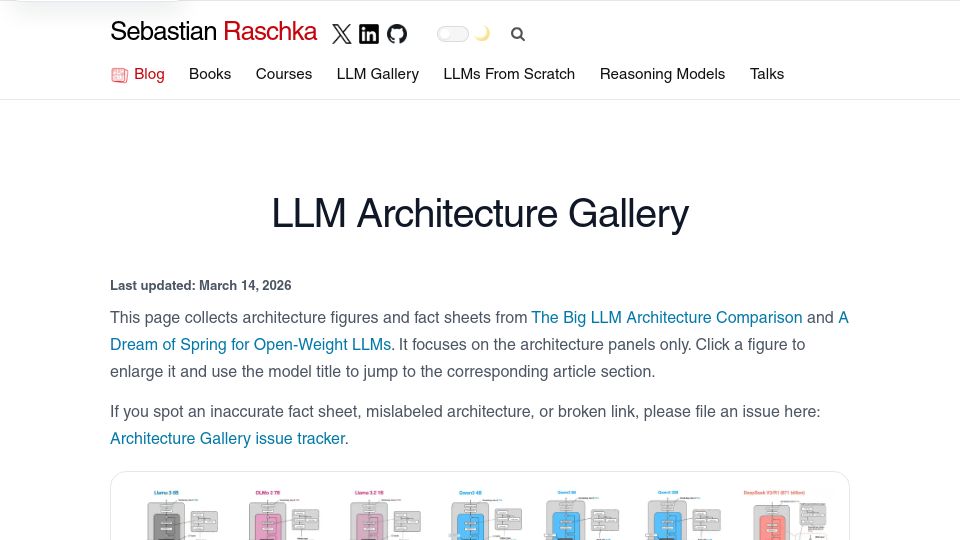
Sebastian Raschka's gallery of architecture diagrams and fact sheets for open-weight LLMs such as Llama, OLMo, Qwen, and DeepSeek.
1807 points by tambourine_man | 302 comments
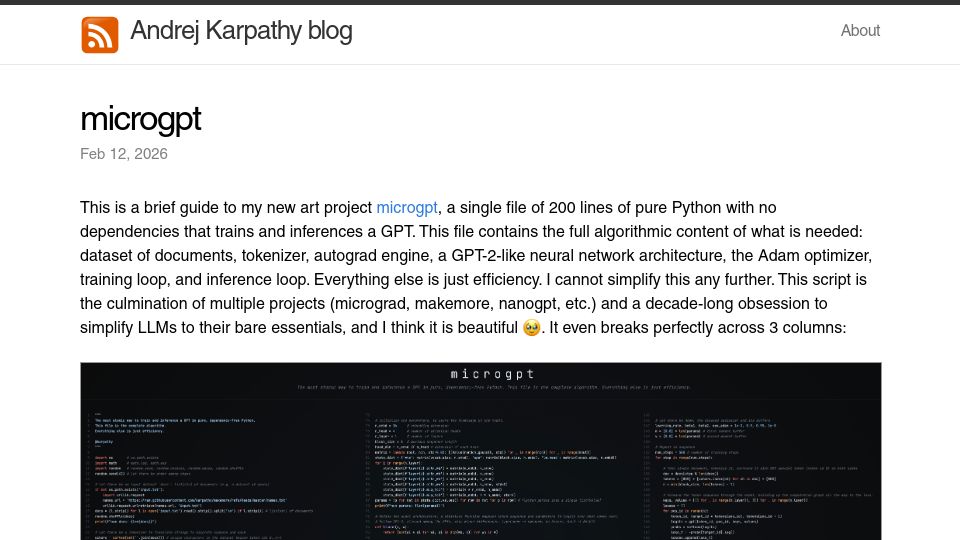
Andrej Karpathy's blog post introducing microgpt, a dependency-free 200-line Python file that trains and runs inference on a GPT.
553 points by Alifatisk | 176 comments
Google Research blog post introducing the Titans architecture and MIRAS framework for giving AI models long-term memory.
705 points by melded | 339 comments
GitHub repository for Heretic, an AGPL-licensed tool for fully automatic censorship removal (abliteration) in transformer language models.
363 points by achow | 185 comments
VentureBeat article in which Sakana AI's CTO, a coauthor of 'Attention Is All You Need', says he is sick of transformers; the capture shows only a Vercel security checkpoint.
435 points by nathan-barry | 102 comments
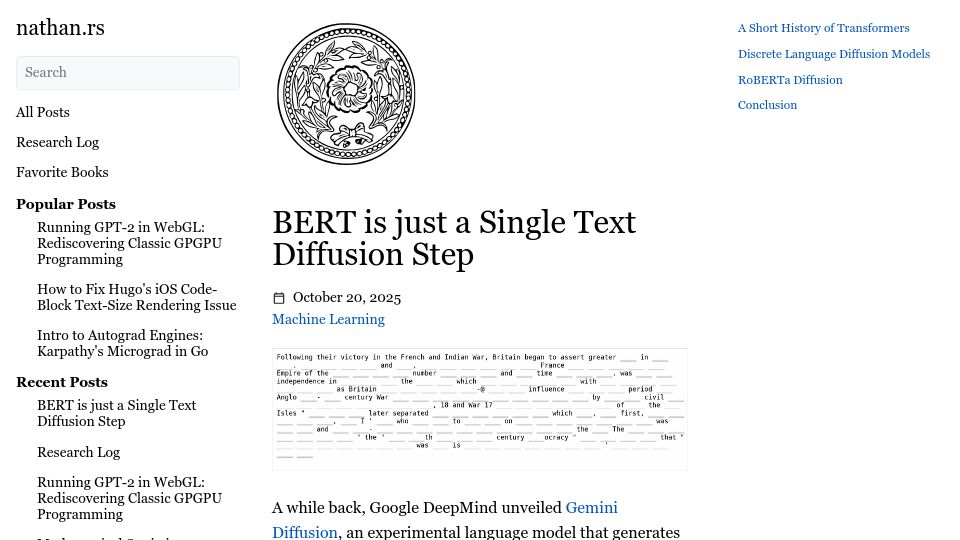
Blog post arguing BERT-style masked language modeling is a single step of discrete text diffusion, with experiments fine-tuning RoBERTa as a diffusion text generator.
568 points by gmays | 39 comments
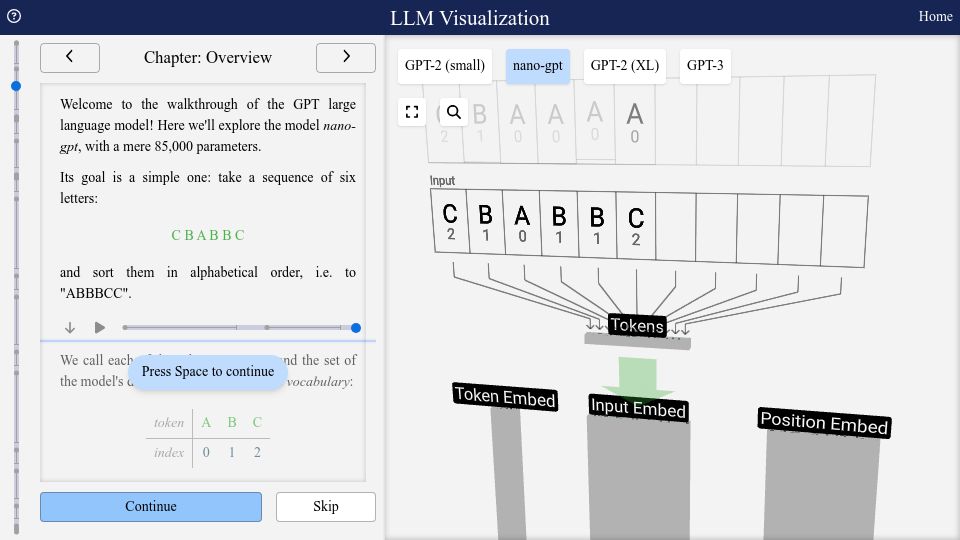
An interactive 3D visualization and walkthrough of how a GPT large language model works, starting with a tiny nano-gpt model that sorts letters.
476 points by ingve | 173 comments
Sean Goedecke's blog post on training the best small GPT-style model possible on a MacBook Pro in five minutes, landing on a ~1.8M-parameter transformer trained on TinyStories.
450 points by ModelForge | 95 comments
Sebastian Raschka's Ahead of AI article analyzing the architecture of OpenAI's open-weight gpt-oss models, tracing changes since GPT-2 and comparing them to Qwen3.
357 points by mdp2021 | 23 comments
Sebastian Raschka's Ahead of AI article comparing the architectures of modern LLMs, from DeepSeek-V3 to Kimi K2.
549 points by chmaynard | 134 comments
Rachel Thomas blog post on how a high-profile Nature paper using a Transformer to predict enzyme functions contained many errors that received far less attention than the original result.
322 points by gpjt | 61 comments
Blog post, part 13 of a series working through Raschka's 'Build a Large Language Model (from Scratch)', explaining why self-attention's matrix multiplications work.
350 points by gpjt | 26 comments
Blog post, part 8 of a series working through Raschka's 'Build a Large Language Model (from Scratch)', explaining self-attention with trainable weights.
438 points by iNic | 161 comments
arXiv paper introducing FFTNet, an FFT-based adaptive spectral filtering framework offering O(n log n) token mixing as an alternative to self-attention.
415 points by amrrs | 52 comments
GitHub repository for smolGPT, a minimal PyTorch implementation for training a small GPT-style language model from scratch.
366 points by zxexz | 83 comments
Meta AI research publication page for the Byte Latent Transformer paper, which proposes byte-level patches instead of tokens for scaling language models.
340 points by lawrenceyan | 150 comments
GitHub repository from Google DeepMind with code, data, and checkpoints for the paper 'Grandmaster-Level Chess Without Search'.
343 points by shchegrikovich | 122 comments
Substack post arguing that having LLMs generate Prolog code can improve their reasoning, given the limits of autoregressive transformer generation.
525 points by weirdcat | 166 comments
arXiv paper introducing Diff Transformer, which computes attention as the difference of two softmax maps to cancel noise and improve long-context modeling and reduce hallucination.
466 points by beefman | 245 comments
arXiv paper proposing minimal LSTM and GRU variants without hidden-state gate dependencies that can be trained in parallel, rivaling recent sequence models.
344 points by felipemesquita | 45 comments
GitHub repository for transformers-ruby by ankane, a Ruby port of state-of-the-art transformer models, licensed under Apache-2.0.
987 points by Hadi7546 | 246 comments
GitHub repository with a Jupyter notebook implementing Meta's Llama 3 model from scratch, one matrix multiplication at a time.
387 points by huhhuh | 46 comments
A 3Blue1Brown YouTube video giving a visual introduction to GPT and the transformer architecture, chapter 5 of its deep learning series.
324 points by bubblehack3r | 78 comments
News article announcing AI21 Labs' Jamba, a hybrid SSM-Transformer language model billed as the first production-grade Mamba-based model.
350 points by marban | 218 comments
Wired Backchannel feature by Steven Levy on the eight Google researchers who wrote the Transformers paper that underpins modern AI.
1409 points by evanmays | 160 comments
Landing page for a project that teaches how large language models work using a real LLM implemented entirely in Excel, with video lessons and a demo.
318 points by nmca | 91 comments
GitHub repository for OpenAI's Transformer Debugger, a tool for investigating internal behaviors of small language models, including neuron explainer and viewer.
1038 points by thunderbong | 70 comments
Blog post from Explain Extended implementing a GPT-style large language model inference in about 500 lines of SQL, as a New Year's post.
411 points by tplrbv | 72 comments
A long blog post analyzing how a small ~10M parameter transformer trained from Karpathy's tutorial turns attention outputs into next-token predictions.
408 points by LaserPineapple | 94 comments
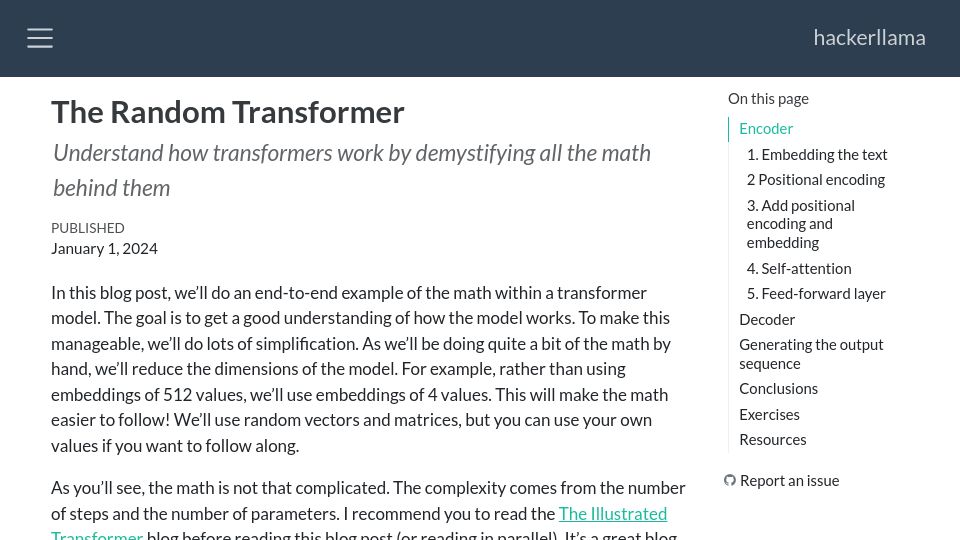
A hackerllama blog post walking through an end-to-end worked example of transformer math using small random vectors and matrices.
910 points by jonbaer | 1 comments
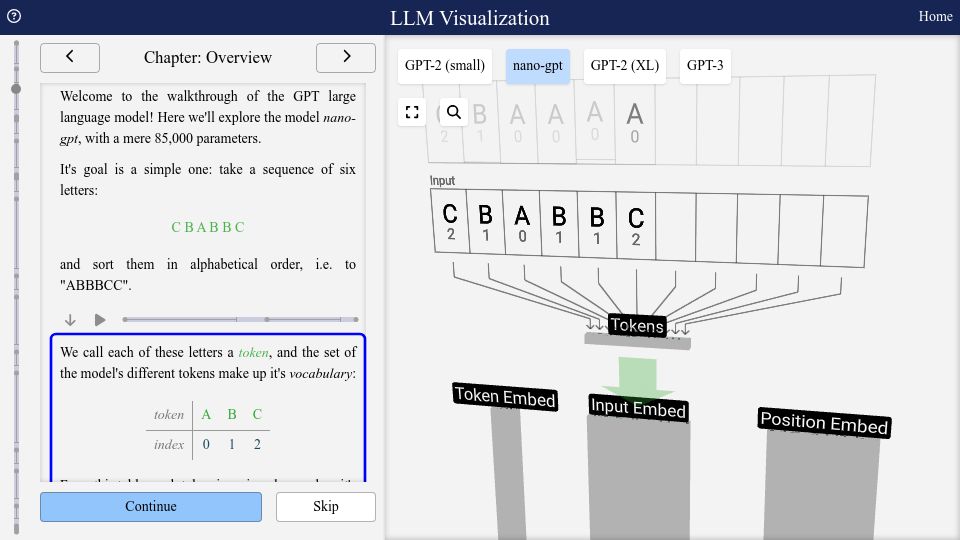
An interactive 3D walkthrough visualizing how a GPT-style large language model works, step by step, using nano-gpt, GPT-2, and GPT-3 examples.
1512 points by plibither8 | 129 comments
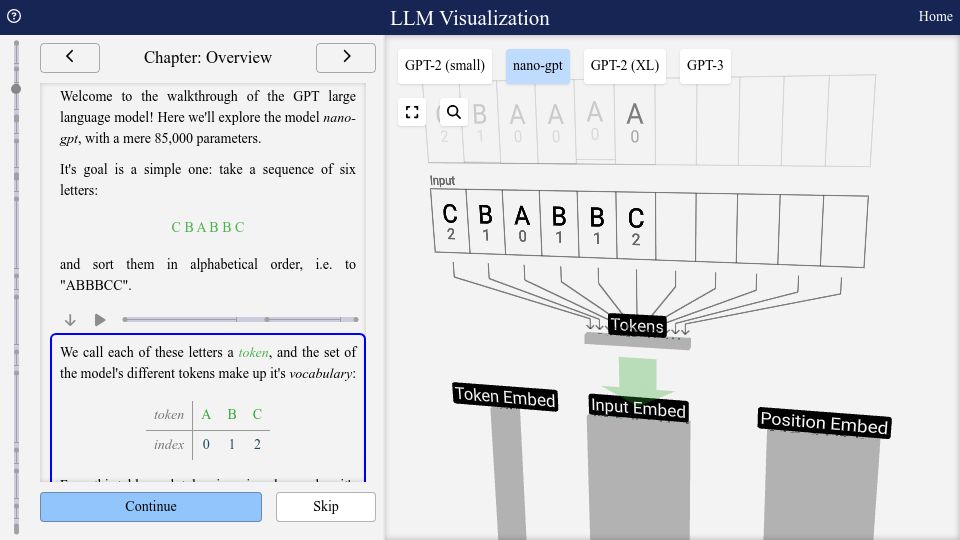
An interactive 3D walkthrough visualizing how a GPT large language model works, starting with a tiny nano-gpt model that sorts letters.
684 points by jackcook | 148 comments
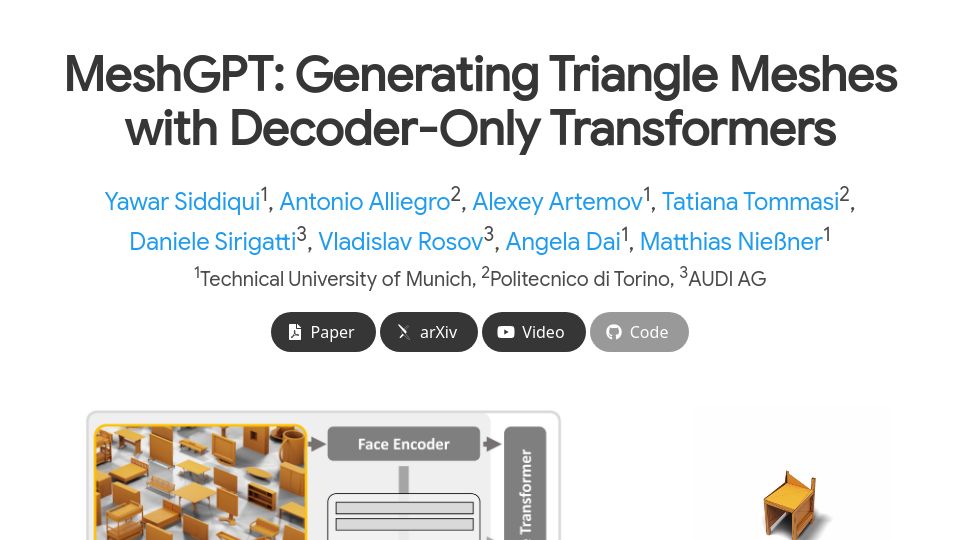
Project page for MeshGPT, a research paper from TU Munich, Politecnico di Torino and Audi that generates triangle meshes using decoder-only transformers.
401 points by guywithabowtie | 65 comments
GitHub repository from MIT HAN Lab for StreamingLLM, code for efficient streaming language models using attention sinks.
442 points by nojito | 218 comments
Blog post by Jack Cook investigating the Transformer language model Apple ships for inline predictive text in iOS and macOS.
444 points by bkitano19 | 39 comments
A blog tutorial by Brian Kitano on implementing a scaled-down Llama language model from scratch trained on TinyShakespeare, with tips for implementing research papers.
959 points by elbasti | 307 comments
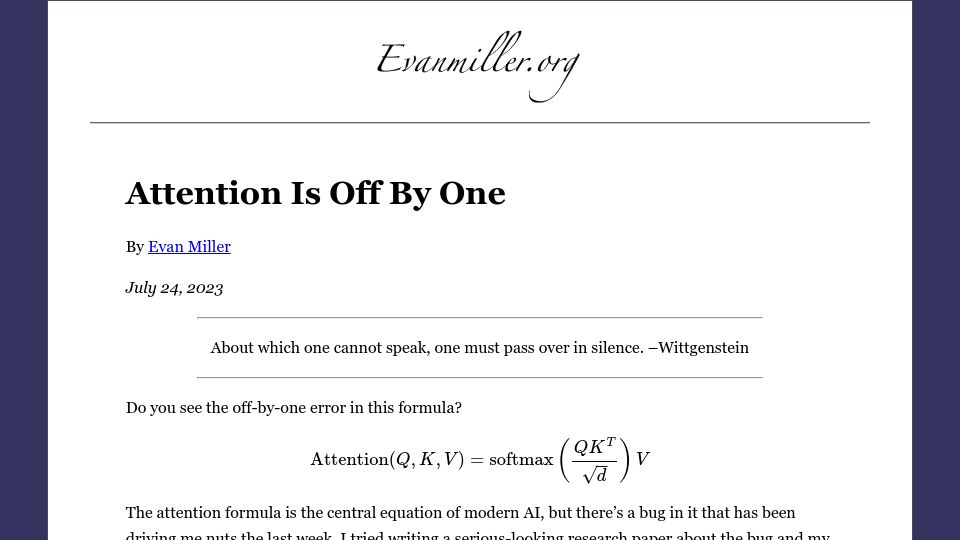
Evan Miller's blog post arguing that the softmax in the transformer attention formula has an off-by-one flaw and proposing a modified softmax.
659 points by anjneymidha | 158 comments
GitHub repository by Andrej Karpathy for llama2.c, a minimal implementation for running Llama 2 model inference in a single file of pure C.
406 points by T-A | 92 comments
A Medium blog post explaining techniques for speeding up large language models and enabling context windows of 100K tokens.
393 points by og_kalu | 282 comments
Project page for MusicGen, Meta's single-stage transformer language model for text- and melody-conditioned music generation, with abstract and samples.
318 points by ianbutler | 164 comments
arXiv paper introducing RWKV, a model architecture combining Transformer-style parallel training with efficient RNN inference via linear attention.
515 points by Sai_ | 196 comments
Ask HN thread requesting a simple explanation of transformer models and the "Attention Is All You Need" paper, with community replies and resource links.
594 points by jasim | 46 comments
A long-form tutorial explaining how transformer neural networks work from the ground up, covering matrix multiplication, attention, and backpropagation.
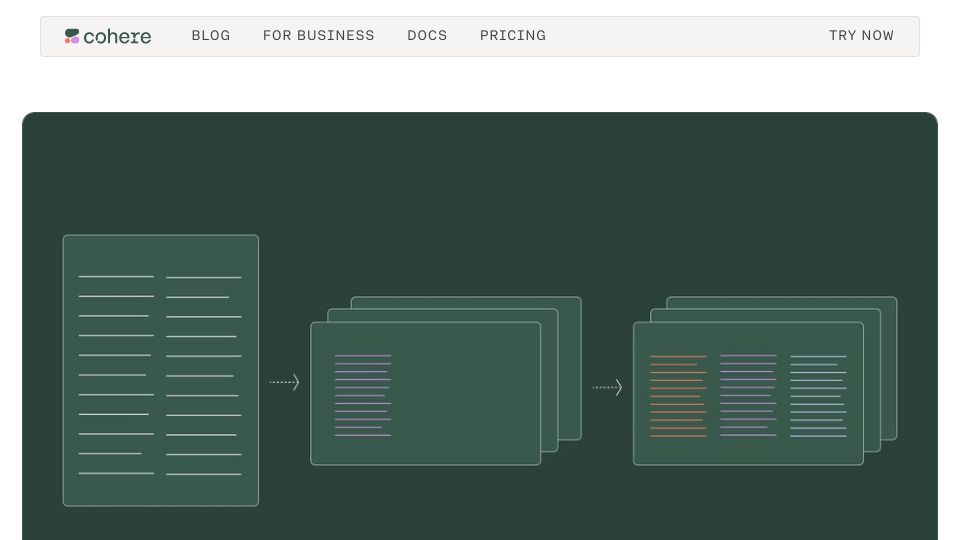
380 points by tomcam | 91 comments
Cohere blog post explaining what transformer models are and how they work in natural language processing.
396 points by tosh | 89 comments
Tweet by Andrej Karpathy showing a tiny GPT with two tokens and context length 3 viewed as a finite state Markov chain, explaining learned transition probabilities.
451 points by headalgorithm | 98 comments
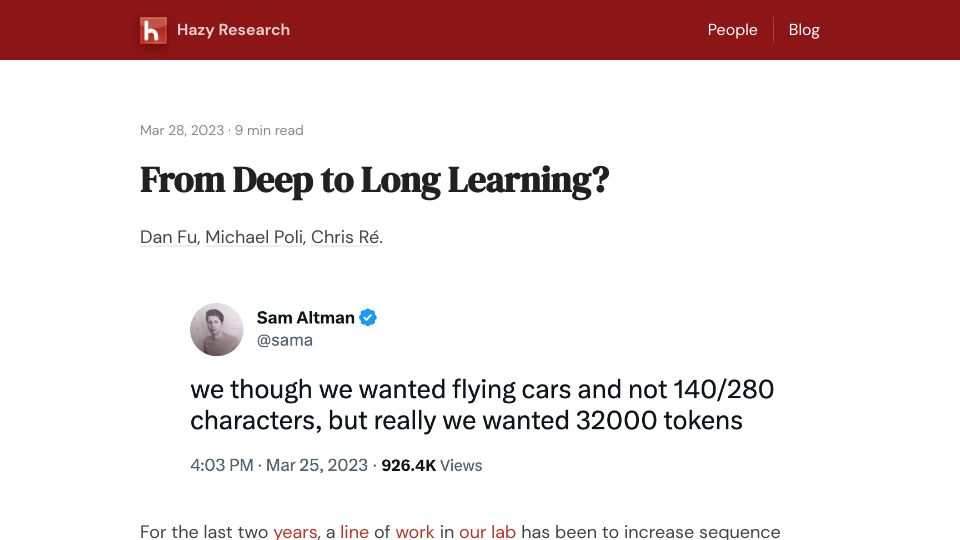
Stanford Hazy Research blog post by Dan Fu, Michael Poli, and Chris Ré on their lab's work increasing sequence length in deep learning models.