Fixing Tool-Call Accuracy in vLLM(ubicloud.com)
20 points by coffeemug | 1 comments
Ubicloud blog post explaining tool-call schema accuracy problems when serving open-weight models like Kimi K2.6 in vLLM and how constrained decoding fixes them.
72 stories tagged llm-inference, newest first.
20 points by coffeemug | 1 comments
Ubicloud blog post explaining tool-call schema accuracy problems when serving open-weight models like Kimi K2.6 in vLLM and how constrained decoding fixes them.
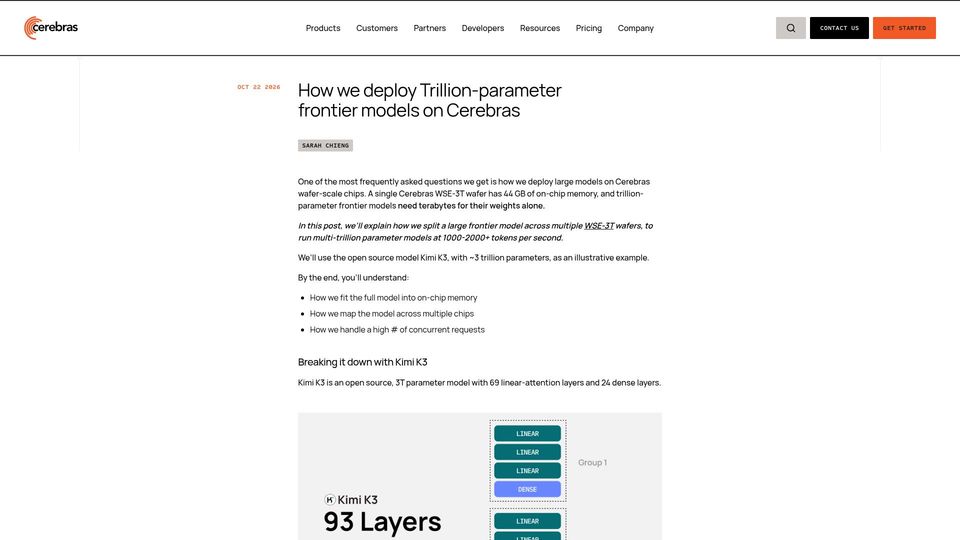
349 points by gmays | 127 comments
Cerebras blog post explaining how trillion-parameter models like Kimi K3 are split across multiple WSE-3T wafers for pipelined, high-throughput inference.
2273 points by ggcr | 890 comments
GitHub repository for DeepInfer, DeepSeek's open-source high-performance, large-scale inference framework for DeepSeek models.
4 points by zniturah | 0 comments
GitHub repository for vllm-torchtpu, a PyTorch-native TPU backend for the vLLM LLM inference engine.
41 points by gmays | 5 comments
Blog post by Joe Barrow explaining that speculative decoding speeds up LLM inference by changing the kind of GPU work rather than reducing FLOPs.
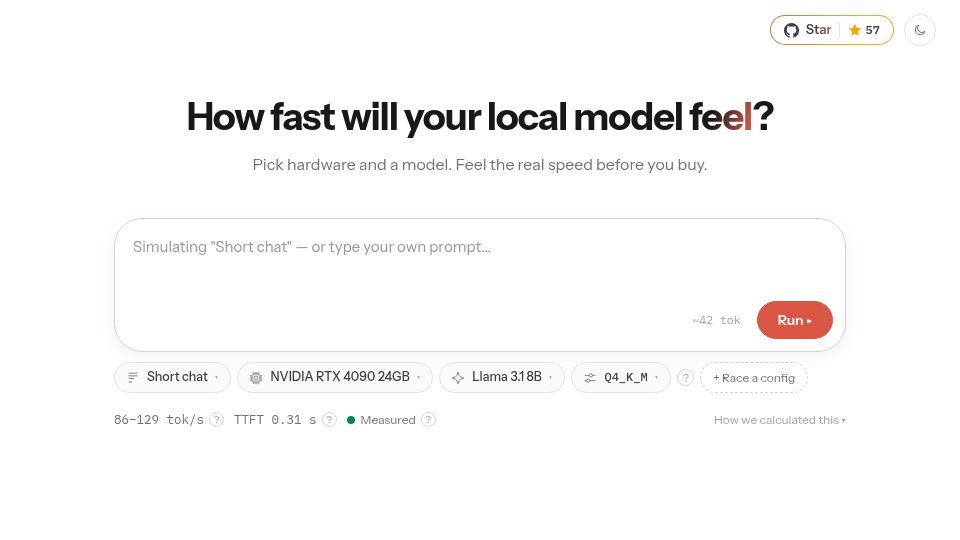
308 points by albinstman | 85 comments
Llmspeed is a web tool that simulates the token generation speed of local LLMs on chosen hardware, model, and quantization settings before buying hardware.
355 points by antipaul | 188 comments
Apple Machine Learning Research post on running large LLM inference locally and distributed across Mac Studio machines using MLX and RDMA.
7 points by Ir0n | 0 comments
A page from meshapplied.com about running a Qwen LLM at 255 tokens per second on a single Nvidia RTX 5090 GPU; no page content was captured.
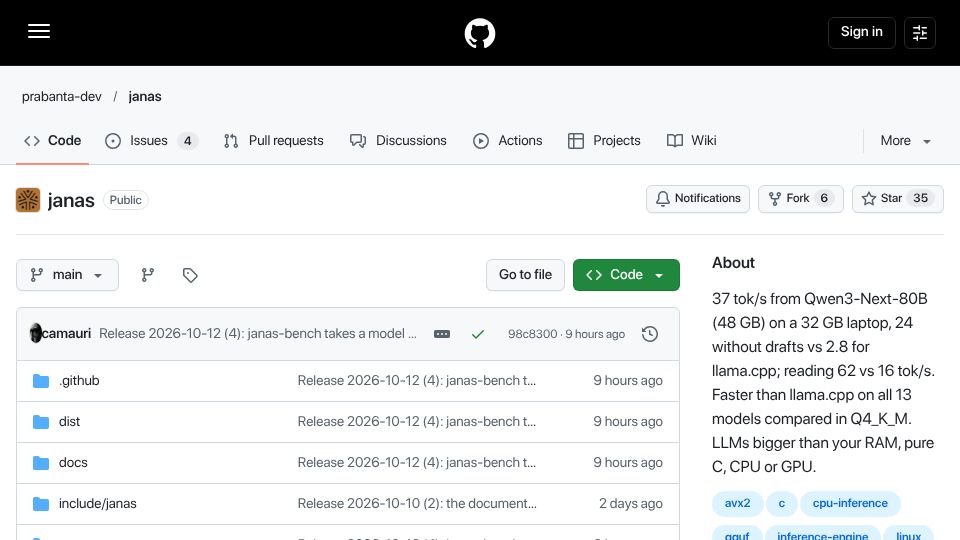
207 points by khalidkhair | 77 comments
GitHub repository for Janas, a pure C inference engine that runs LLMs larger than RAM by streaming MoE experts from SSD, on CPU or GPU.
14 points by kmavm | 4 comments
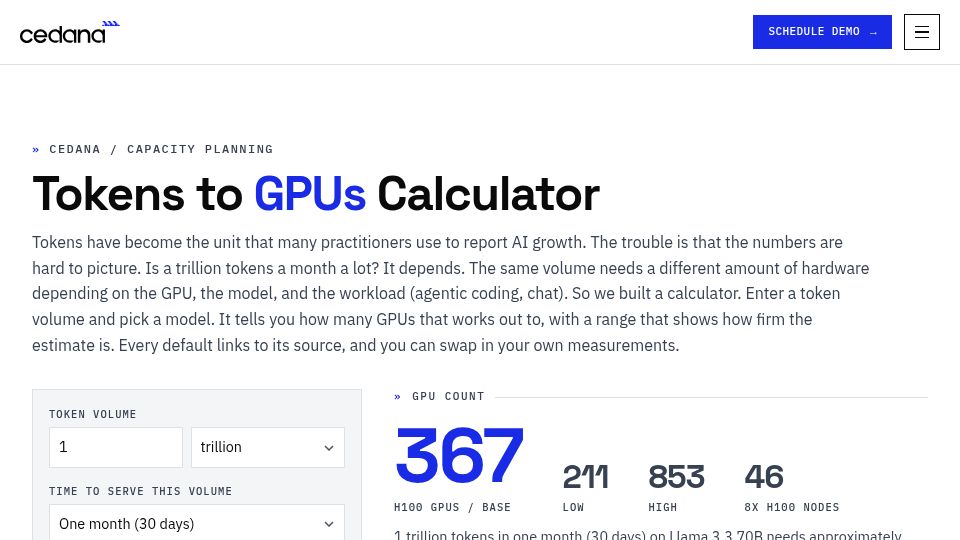
Cedana's interactive calculator that converts a token volume and model choice into an estimated number of GPUs (e.g., H100s) needed to serve it.
326 points by fsbonetto | 371 comments
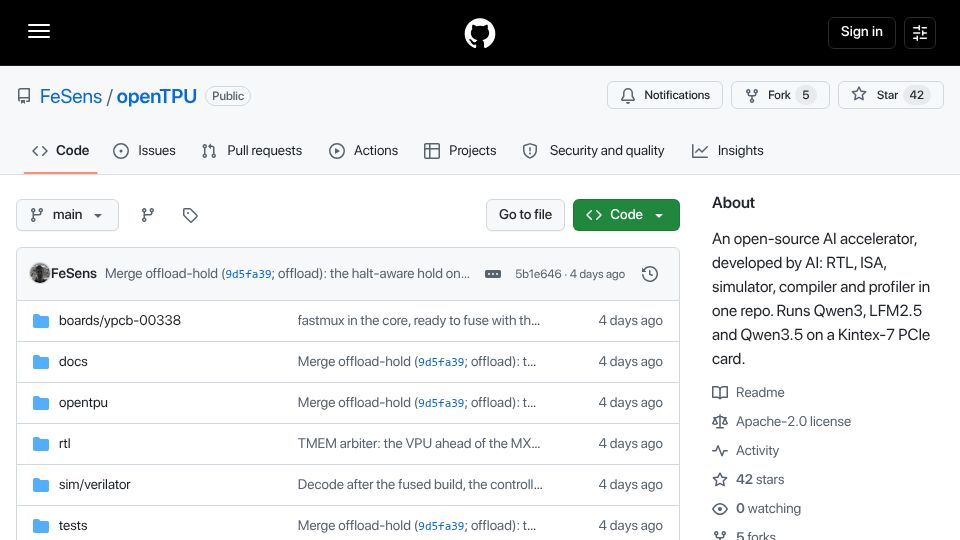
GitHub repository for openTPU, an open-source AI accelerator with RTL, ISA, simulator, compiler and profiler that runs Qwen3 and LFM2.5 on a Kintex-7 PCIe card.
892 points by snehesht | 402 comments
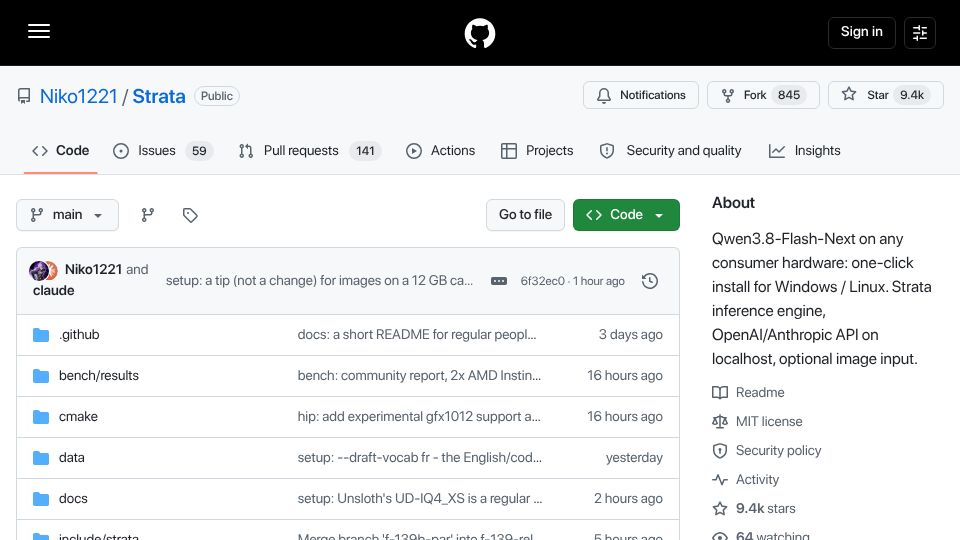
GitHub repository for Strata, an inference engine offering one-click install to run Qwen3.8-Flash-Next locally on consumer hardware with an OpenAI/Anthropic-compatible API.
5 points by echohive42 | 5 comments
An echohive field note with a short film and interactive guide imagining an AI agent producing a million output tokens per second, and what that would mean for judgment and trust.
6 points by ColinWright | 2 comments
Landing page of the Debian Inference Portal, a self-service site where Debian Developers and Maintainers log in via Salsa to get LLM inference API keys and track budgets.
92 points by Maverick617 | 17 comments
GitHub repository for Janus, an MIT-licensed AI model API router written in Go with a Vulkan-based runner for GGUF models on AMD, Intel, and Nvidia GPUs.
187 points by anerli | 88 comments
GitHub repository for Magnitude, an open source Rust inference engine for local AI agents that autotunes GPU kernels to your hardware, claiming up to 2x faster than llama.cpp.
72 points by pptadversary | 11 comments
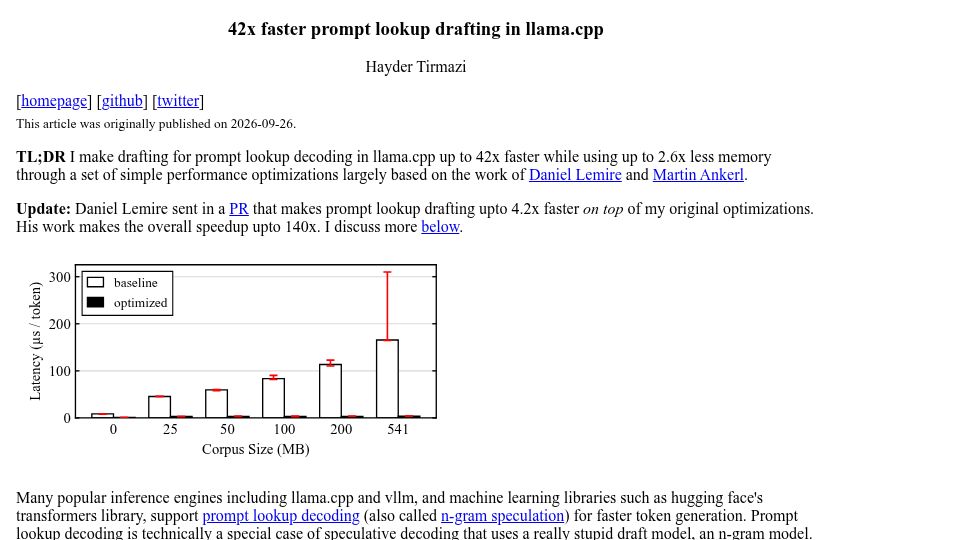
Blog post by Hayder Tirmazi describing optimizations that make prompt lookup drafting in llama.cpp up to 42x faster (140x with Daniel Lemire's follow-up PR) with less memory.
8 points by donk8r | 2 comments
A TypeTab blog post explaining which local LLM model sizes fit on Apple Silicon Macs, which free tools to use, and practical everyday uses.
36 points by marinesebastian | 25 comments
Ornn Data research paper arguing that open-weight model demand extends the economic useful life of older NVIDIA GPU families, comparing inference costs to closed models.
692 points by player85 | 189 comments
Blog post by the developer of Olly, an iMessage AI assistant, describing pitfalls and lessons learned running open models through OpenRouter's varied providers.
675 points by altertable | 221 comments
Cerebras Inference documentation page listing the models available on its public API endpoints, with links to rate limits, pricing, and dedicated endpoints.
417 points by felineflock | 171 comments
A Level1Techs forum post presenting technical experiments on how quantization and implementation differences make locally run LLMs perform worse than reference versions.
678 points by pr337h4m | 263 comments
Cerebras blog post announcing that it powers OpenAI's Ultrafast Mode for GPT-5.6 Sol in the OpenAI API, delivering up to 750 output tokens per second.
366 points by zhoutong | 88 comments
GitHub repository with patches, tuning files, and config for running DeepSeek V4 Flash on a single AMD MI300X GPU.
318 points by marcobambini | 152 comments
GitHub repository for waste, a dependency-free embeddable C inference engine that runs the 2.78-trillion-parameter Kimi K3 model by streaming weights from NVMe.
845 points by gitpusher42 | 300 comments
GitHub repo for TurboFieldfare, a Swift/Metal inference engine running 4-bit Gemma 4 26B-A4B on M-series Macs in about 2 GB RAM by streaming experts from SSD.
882 points by vforno | 223 comments
GitHub repo for Colibrì, a dependency-free C engine that runs the 744B GLM-5.2 MoE model on a ~25GB-RAM machine by streaming experts from disk.
345 points by latchkey | 133 comments
Wafer blog post on serving the GLM-5.2 model on AMD MI355X GPUs at 2626 tok/s per node and 213 tok/s single stream, at over 2x lower cost than Nvidia Blackwell.
390 points by livestyle | 175 comments
GitHub repository by jamesob collecting notes, runners, and tools for running state-of-the-art LLMs locally.
1124 points by stared | 699 comments
A Quesma blog post by Piotr Migdał arguing that the dense Qwen 3.6 27B model is the best choice for running LLMs locally for development, with impressions and setup guidance.
771 points by aurenvale | 330 comments
GitHub file view of DSpark_paper.pdf in deepseek-ai's DeepSpec repo, a paper on speculative decoding to accelerate LLM inference.
1490 points by jfb | 569 comments
Vicki Boykis blog post arguing that running LLMs locally on a 64GB M2 Mac is now practical, describing models like Mistral 7B, Gemma 3, OpenAI OSS-20B and Qwen 3.
600 points by gainsurier | 448 comments
Xiaomi MiMo blog post announcing MiMo-V2.5-Pro-UltraSpeed, a 1-trillion-parameter model served at roughly 1000 tokens per second.
411 points by caust1c | 173 comments
Blog post by antirez reflecting on the rapid popularity of DwarfStar 4 (DS4), his local AI inference project, and its future plans beyond DeepSeek v4 Flash.
461 points by tamnd | 133 comments
GitHub repository for ds4 by antirez, a local inference engine for running the DeepSeek 4 Flash model on Apple Metal, released under the MIT license.
640 points by amrrs | 309 comments
Google blog post announcing Multi-Token Prediction drafters for Gemma 4 models to reduce inference latency and improve responsiveness.
517 points by AbuAssar | 107 comments
Homepage for Lemonade, AMD's open source local LLM server that runs models on GPUs and NPUs on Windows, Linux, and macOS.
588 points by redundantly | 303 comments
Ollama blog post announcing a preview of Ollama running on Apple's MLX framework for Apple Silicon Macs.
379 points by mft_ | 119 comments
GitHub repository for Flash-MoE, a project for running a 397B-parameter mixture-of-experts model on a laptop using Metal inference code.
1375 points by ricardbejarano | 326 comments
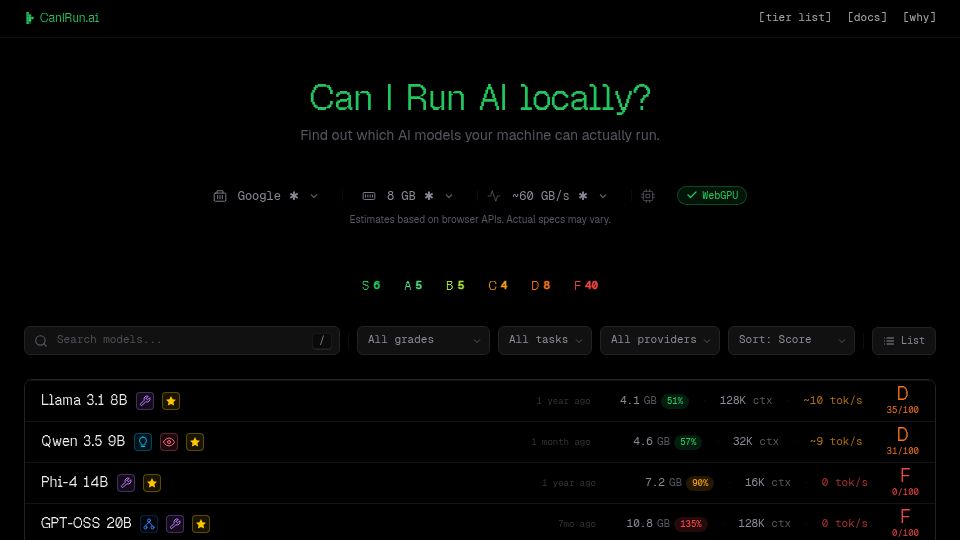
CanIRun.ai is a web tool that estimates which AI models your machine can run locally, using browser APIs to detect hardware and grading each model's expected performance.
357 points by redm | 163 comments
GitHub repository for Microsoft's BitNet, the official inference framework for 1-bit large language models.
330 points by fittingopposite | 121 comments
Inception Labs blog post by CEO Stefano Ermon announcing Mercury 2, a fast reasoning LLM built on diffusion rather than autoregressive generation.
338 points by dataminer | 121 comments
ByteShape blog post describing how they quantized Qwen3-30B-A3B-Instruct with their Shapelearn bitlength method to run in real time on a Raspberry Pi.
569 points by rbanffy | 211 comments
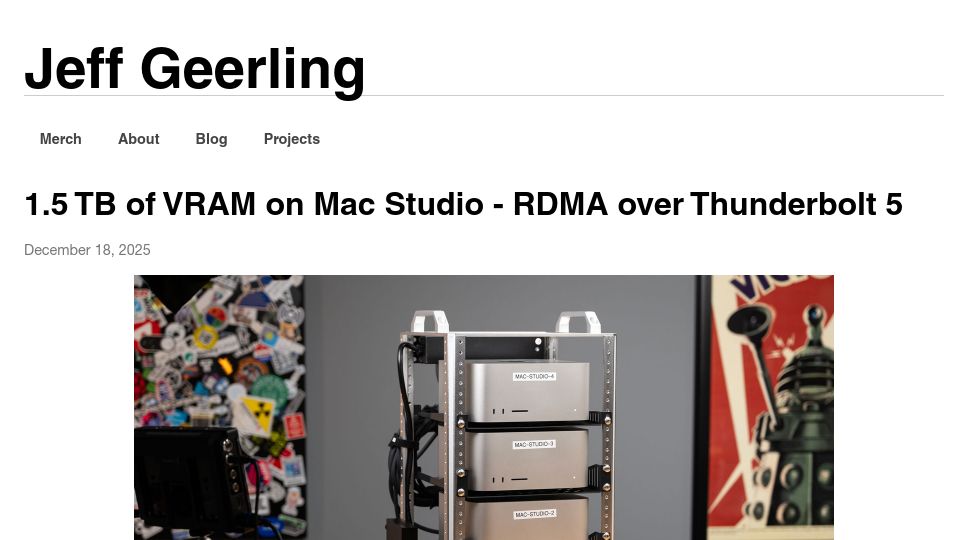
Jeff Geerling blog post about clustering four Mac Studios with RDMA over Thunderbolt 5 to pool 1.5 TB of unified memory for AI workloads.
501 points by hd4 | 286 comments
News article reporting Alibaba Cloud's Aegaeon GPU pooling system, which it says cut Nvidia GPU use by 82% when serving dozens of large language models.
472 points by sydriax | 94 comments
Stanford Hazy Research blog post introducing a throughput-optimized megakernel for tensor-parallel Llama-70B inference on H100 GPUs that overlaps compute, memory, and communication.
361 points by moatmoat | 112 comments
Anthropic engineering blog post giving a technical postmortem of three bugs that intermittently degraded Claude's responses, and what is changing.
472 points by martinald | 438 comments
Blog post by Martin Alderson doing napkin-math estimates of whether OpenAI and Anthropic actually lose money serving LLM inference at scale.
474 points by superasn | 304 comments
Ask HN thread asking how OpenAI serves ChatGPT to 700M weekly users when a GPT-4-class model is hard to run locally, seeking inference scaling insights.
404 points by amram_art | 221 comments
Ollama's Turbo preview page, a paid service for running open models on datacenter-grade hardware through the Ollama app and API.
423 points by d3vr | 165 comments
Cerebras blog post announcing Cerebras Code Pro ($50/month) and Code Max ($200/month) plans offering fast Qwen3-Coder inference at up to 2,000 tokens per second.
334 points by mihau | 140 comments
Cerebras press release announcing Qwen3-235B on its Inference Cloud with full 131K context support, billed as the world's fastest frontier AI model.
330 points by djhu9 | 18 comments
BentoML's LLM Inference in Production handbook, a glossary and guide covering inference concepts, performance metrics, optimization techniques, and operational best practices.
557 points by PaulHoule | 230 comments
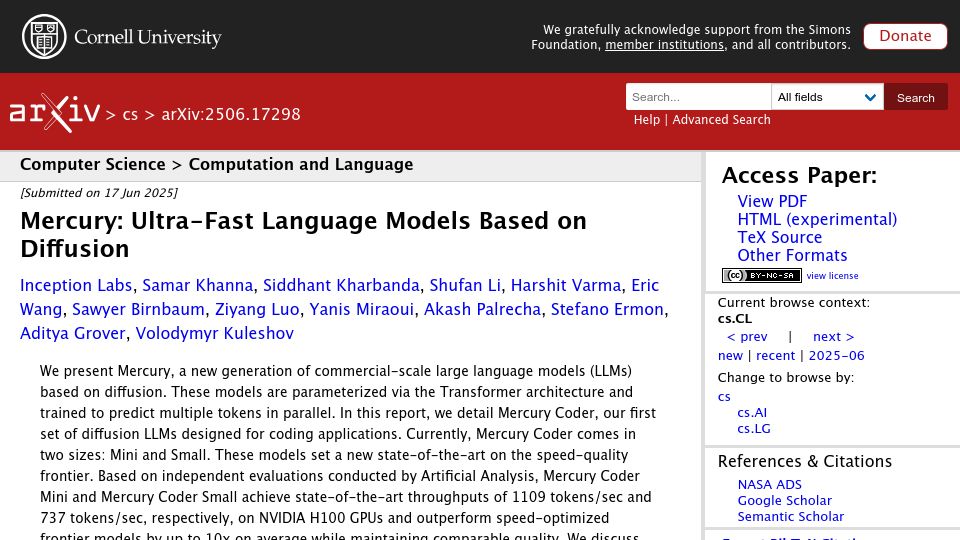
arXiv paper from Inception Labs presenting Mercury, diffusion-based large language models for coding that generate multiple tokens in parallel at very high throughput.
531 points by Palmik | 58 comments
GitHub directory in DeepSeek's open-infra-index repo with a README describing their plan for open-sourcing the DeepSeek inference engine.
473 points by helloericsf | 66 comments
GitHub repository for DeepEP, DeepSeek's open-source expert-parallel communication library for Mixture-of-Experts model training and inference.
403 points by helloericsf | 105 comments
GitHub repository for DeepSeek's FlashMLA, an open-source MLA (multi-head latent attention) decoding kernel optimized for NVIDIA Hopper GPUs.
404 points by benchmarkist | 130 comments
Cerebras blog post announcing that Llama 3.1 405B runs at 969 tokens per second on its Cerebras Inference service.
554 points by fuglede_ | 142 comments
Project page for llama.ttf, a font file that embeds a Llama language model and inference engine via HarfBuzz's Wasm shaper.
447 points by zhisbug | 94 comments
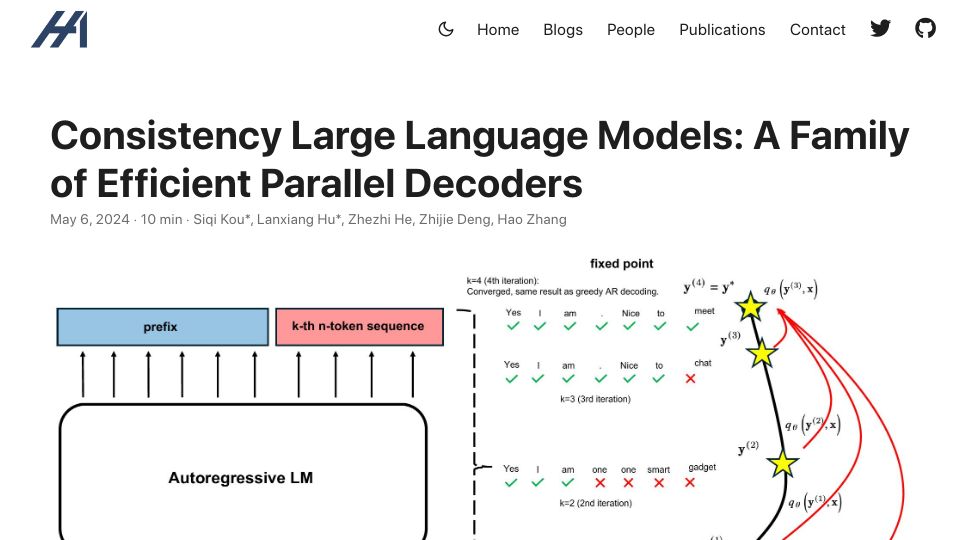
Hao AI Lab blog post introducing Consistency LLMs, a method that fine-tunes LLMs into parallel Jacobi decoders to speed up inference about 3.5x.
387 points by mfiguiere | 127 comments
GitHub repository for gemma.cpp, Google's lightweight standalone C++ inference engine for running Gemma language models.
739 points by tin7in | 431 comments
Groq's homepage, showcasing its fast LLM inference service running Mixtral 8x7B at around 500 tokens per second; the capture shows only a logo splash.
337 points by pentagrama | 137 comments
Ollama blog post from February 15, 2024 announcing a preview release of Ollama for Windows.
377 points by dataminer | 78 comments
GitHub repository for PowerInfer, an SJTU-IPADS engine for high-speed large language model inference on PCs with consumer-grade GPUs.
401 points by guywithabowtie | 65 comments
GitHub repository from MIT HAN Lab for StreamingLLM, code for efficient streaming language models using attention sinks.
404 points by udev4096 | 96 comments
Homepage of Petals, a system for running large language models like Llama 2 and BLOOM collaboratively across volunteer machines, BitTorrent-style.
648 points by birriel | 210 comments
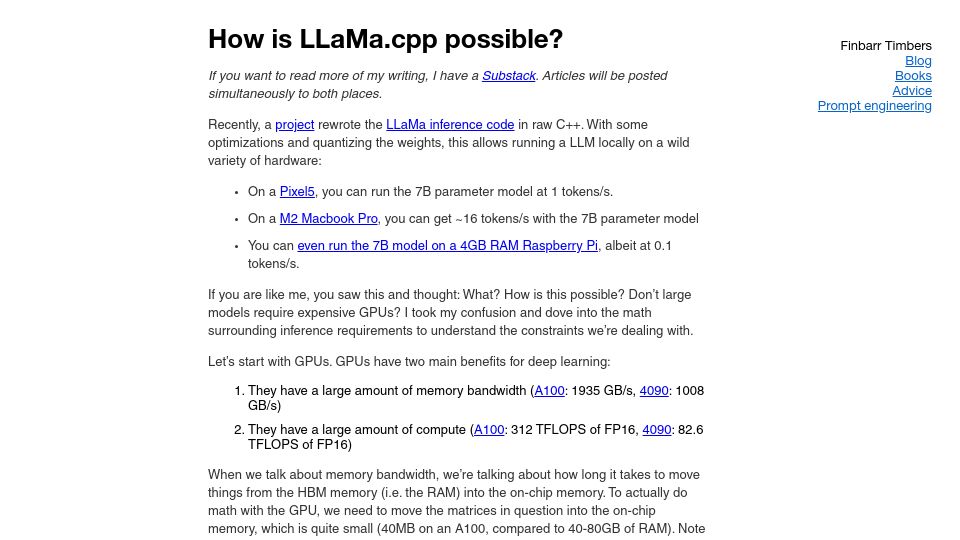
Blog post by Finbarr Timbers explaining the math of why llama.cpp can run LLaMA models locally on consumer hardware, focusing on memory bandwidth and compute limits.
360 points by 152334H | 162 comments
Blog post arguing that GPT-4's non-deterministic outputs at temperature zero are caused by its sparse mixture-of-experts architecture and batched routing.
659 points by anjneymidha | 158 comments
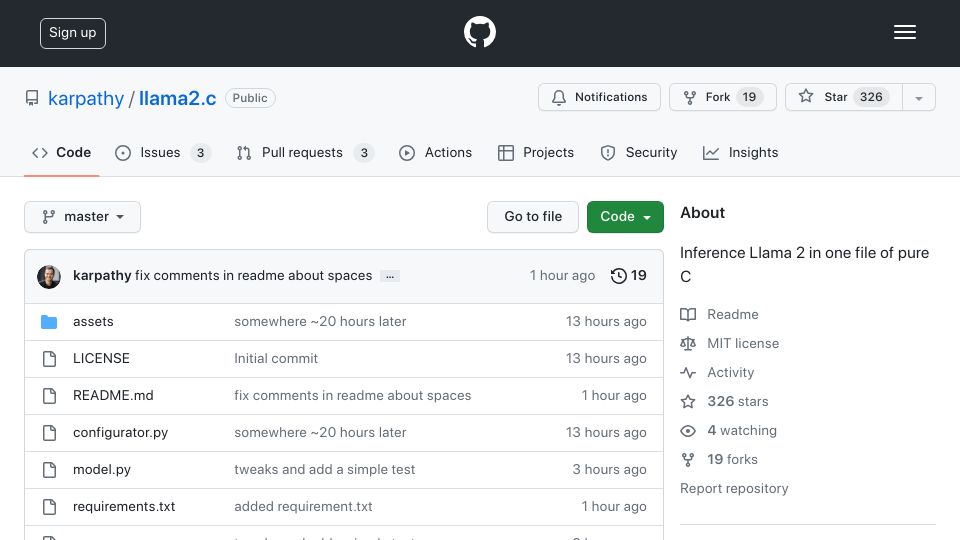
GitHub repository by Andrej Karpathy for llama2.c, a minimal implementation for running Llama 2 model inference in a single file of pure C.
379 points by davepeck | 95 comments
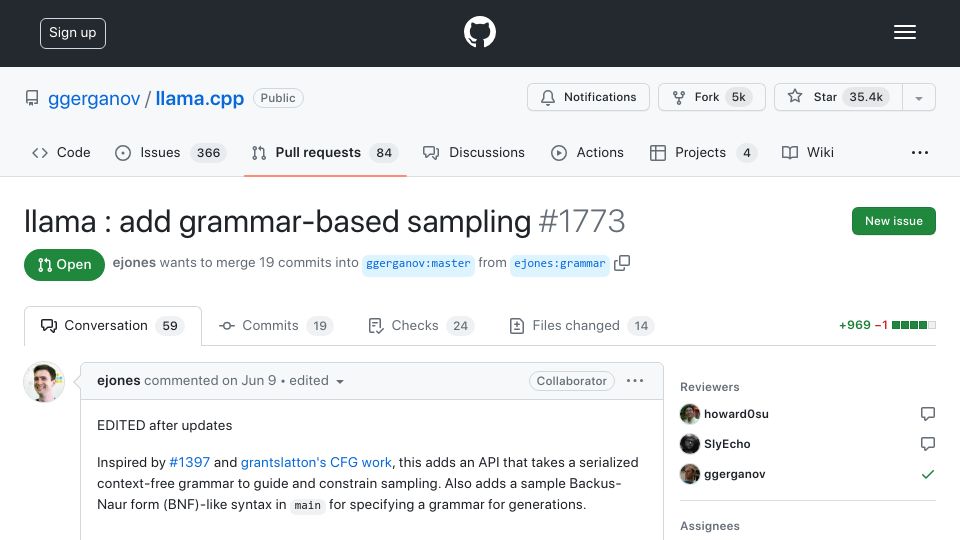
A GitHub pull request to llama.cpp adding an API for grammar-based sampling that constrains LLM output with a BNF-like context-free grammar.
640 points by gzer0 | 265 comments
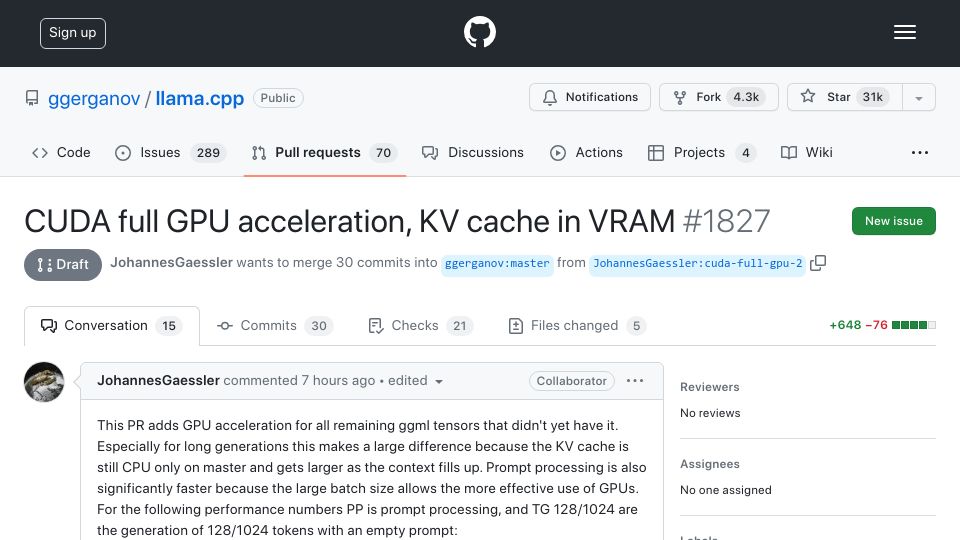
A draft GitHub pull request to llama.cpp adding full CUDA GPU acceleration for all ggml tensors, including storing the KV cache in VRAM.
1182 points by msoad | 356 comments
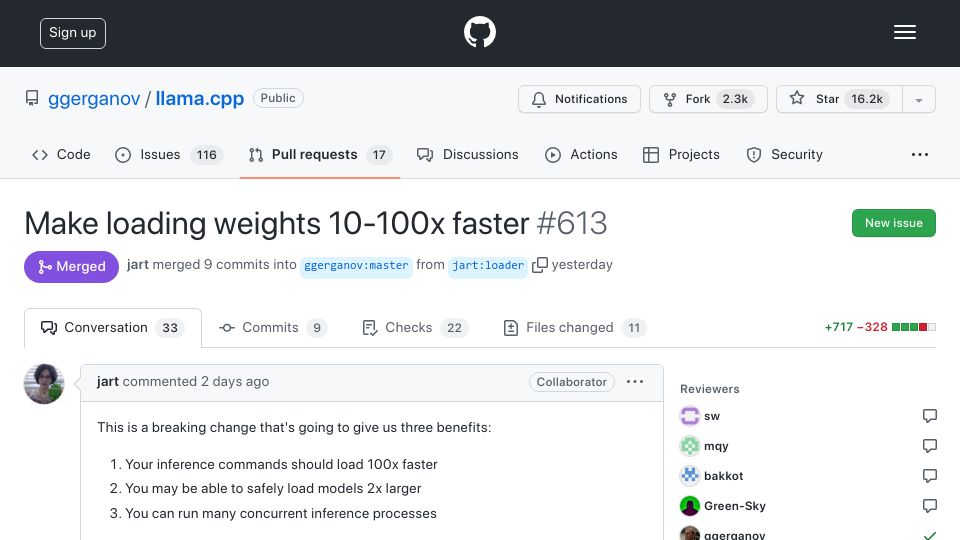
GitHub pull request #613 in llama.cpp by jart, merged, which uses mmap to make loading model weights 10-100x faster and reduce RAM usage.