First screen, captured .
Looks similar
Related stories
Caveman: Why use many token when few token do trick(github.com)
809 points by tosh | 344 comments
GitHub repository for Caveman, a Claude Code skill/plugin that cuts output tokens about 75% by making the model respond in terse caveman-style speech.
100K Context Windows(anthropic.com)
853 points by samwillis | 364 comments
Anthropic announcement from May 11, 2023 introducing 100K token context windows for its Claude language model.
Measuring Claude 4.7's tokenizer costs(claudecodecamp.com)
678 points by aray07 | 474 comments
Blog post measuring Claude Opus 4.7's new tokenizer, finding about 1.47x more tokens than 4.6 on real content versus the documented 1.0–1.35x, and the resulting cost impact.
How fast is N tokens per second really?(mikeveerman.github.io)
459 points by hexagr | 94 comments
Interactive web tool that simulates LLM output streaming at selectable tokens-per-second rates for code, text, thinking, and agent modes.
gpuvis: GPU Trace Visualizer(github.com)
67 points by luu | 10 comments
GitHub repository for gpuvis, an MIT-licensed GPU trace visualizer tool for viewing GPU and CPU event timelines.
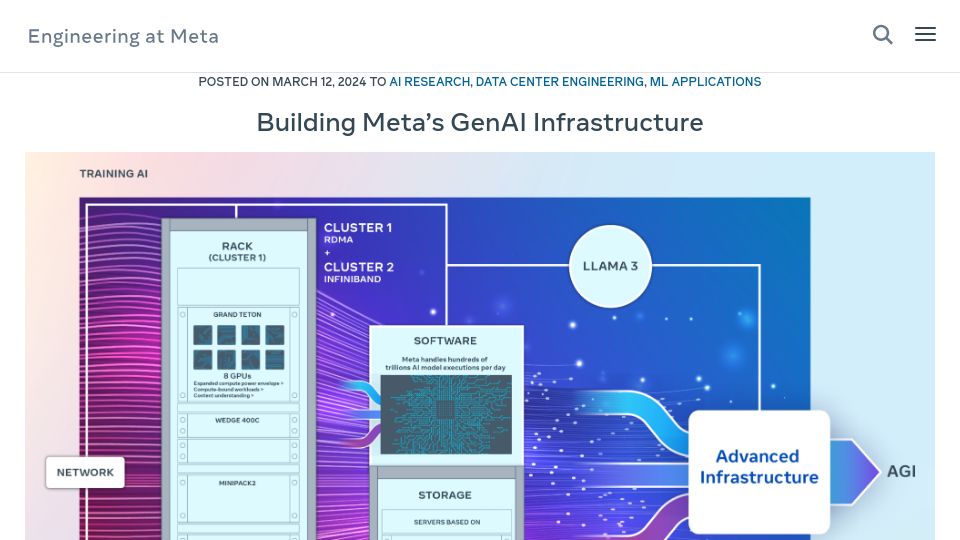
Building Meta's GenAI infrastructure(engineering.fb.com)
636 points by mootpt | 291 comments
Meta engineering blog post describing its large GPU training clusters for generative AI, including RDMA and InfiniBand networking, Grand Teton hardware, and storage.