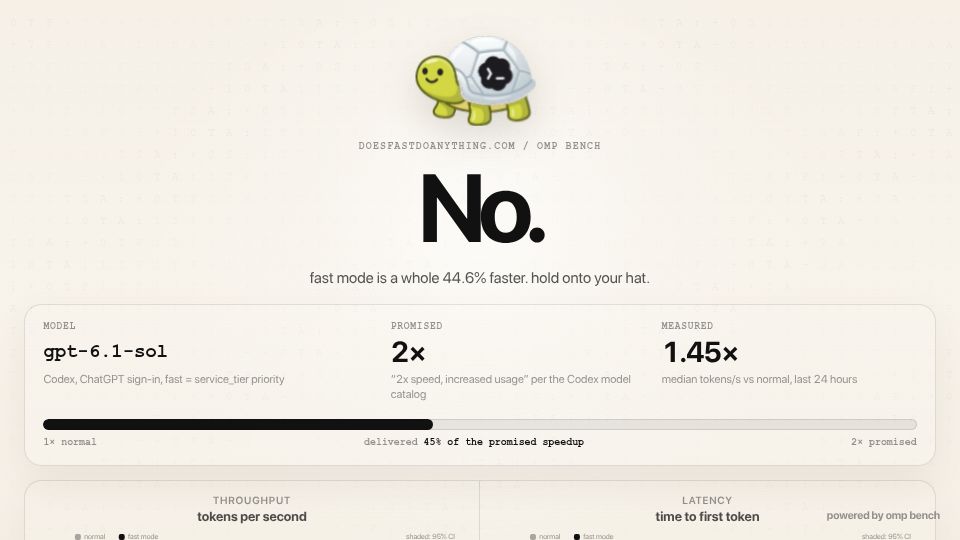
Does Fast Mode Do Anything?(doesfastdoanything.com)
5 points by luu | 1 comments
A benchmark site measuring whether Codex's "fast mode" priority tier delivers its promised 2x speedup, showing a measured 1.45x throughput gain.
7 stories tagged inference-speed, newest first.
5 points by luu | 1 comments
A benchmark site measuring whether Codex's "fast mode" priority tier delivers its promised 2x speedup, showing a measured 1.45x throughput gain.
5 points by echohive42 | 5 comments
An echohive field note with a short film and interactive guide imagining an AI agent producing a million output tokens per second, and what that would mean for judgment and trust.
138 points by Retro_Dev | 81 comments
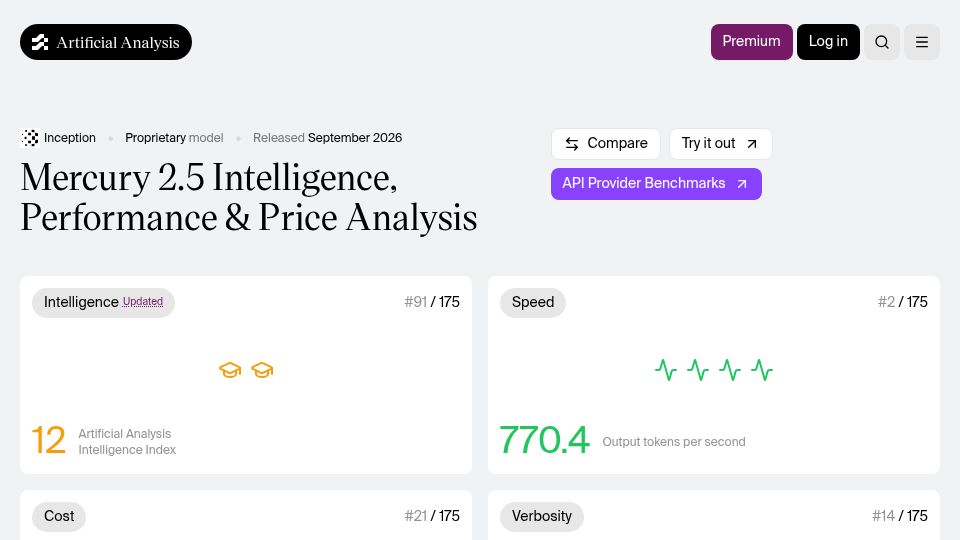
Artificial Analysis benchmark page for Inception's Mercury 2.5 model, covering intelligence index, output speed of 770 tokens per second, cost, and verbosity rankings.
600 points by gainsurier | 448 comments
Xiaomi MiMo blog post announcing MiMo-V2.5-Pro-UltraSpeed, a 1-trillion-parameter model served at roughly 1000 tokens per second.
459 points by hexagr | 94 comments
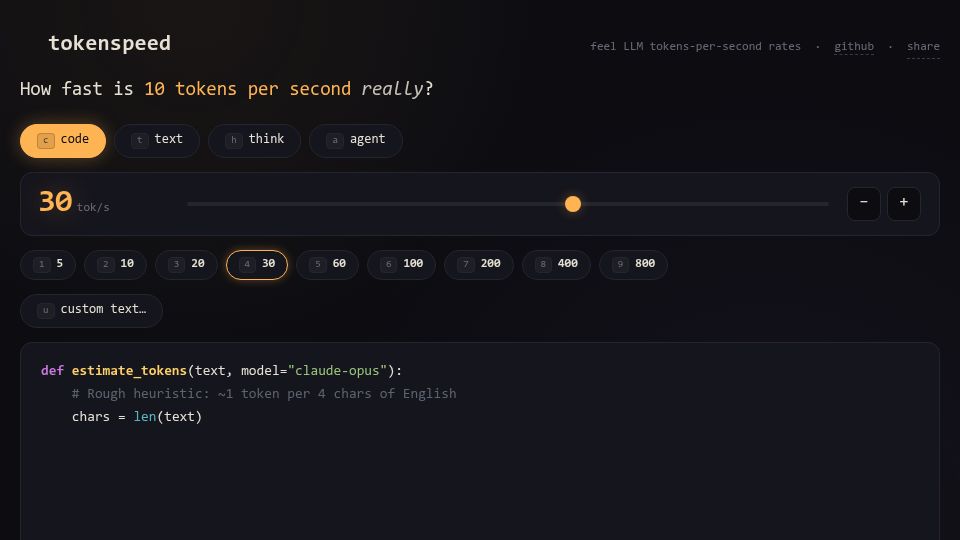
Interactive web tool that simulates LLM output streaming at selectable tokens-per-second rates for code, text, thinking, and agent modes.
334 points by mihau | 140 comments
Cerebras press release announcing Qwen3-235B on its Inference Cloud with full 131K context support, billed as the world's fastest frontier AI model.
375 points by HyprMusic | 162 comments
Inception Labs announcement of Mercury, a commercial-scale diffusion language model claimed to be up to 10x faster and cheaper than current LLMs.