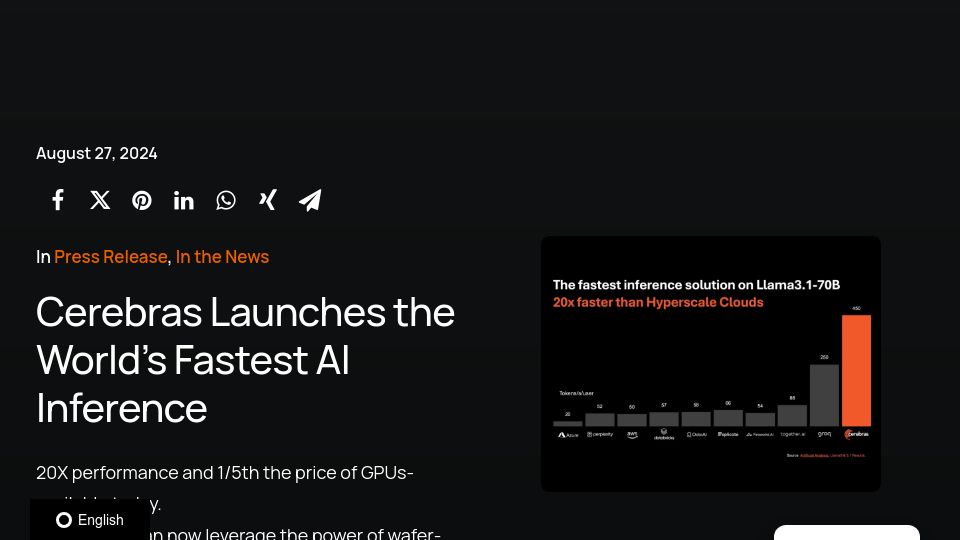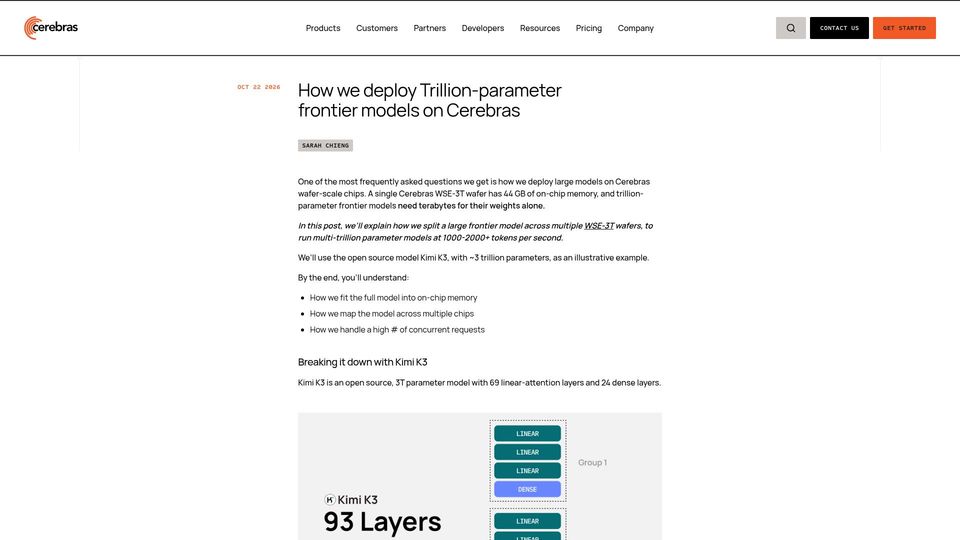
Cerebras Deploys Trillion-Parameter AI Models(cerebras.ai)
349 points by gmays | 127 comments
Cerebras blog post explaining how trillion-parameter models like Kimi K3 are split across multiple WSE-3T wafers for pipelined, high-throughput inference.
14 stories on the front page, newest first. Scroll down to watch the site change over time.
349 points by gmays | 127 comments
Cerebras blog post explaining how trillion-parameter models like Kimi K3 are split across multiple WSE-3T wafers for pipelined, high-throughput inference.
441 points by sunils34 | 256 comments
Cerebras product page introducing the CS-4, which the company bills as the fastest AI accelerator in the industry.
678 points by pr337h4m | 263 comments
Cerebras blog post announcing that it powers OpenAI's Ultrafast Mode for GPT-5.6 Sol in the OpenAI API, delivering up to 750 output tokens per second.
423 points by d3vr | 165 comments
Cerebras blog post announcing Cerebras Code Pro ($50/month) and Code Max ($200/month) plans offering fast Qwen3-Coder inference at up to 2,000 tokens per second.
334 points by mihau | 140 comments
Cerebras press release announcing Qwen3-235B on its Inference Cloud with full 131K context support, billed as the world's fastest frontier AI model.
404 points by benchmarkist | 130 comments
Cerebras blog post announcing that Llama 3.1 405B runs at 969 tokens per second on its Cerebras Inference service.