First screen, captured . Hover to scroll the page, or open the video.
Full page
Captured . Click for the whole screenshot.
Looks similar
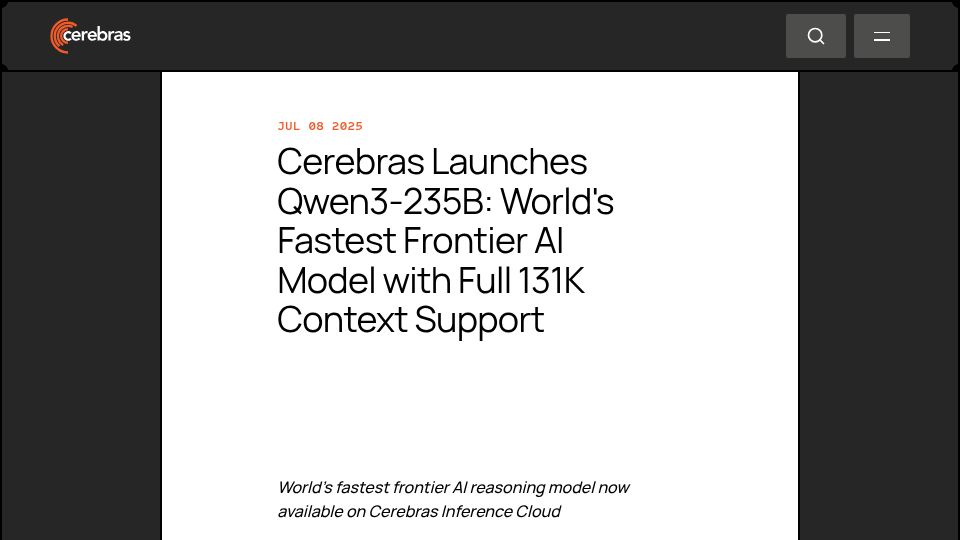
Cerebras launches Qwen3-235B, achieving 1.5k tokens per second(cerebras.ai)
334 points by mihau | 140 comments
Cerebras press release announcing Qwen3-235B on its Inference Cloud with full 131K context support, billed as the world's fastest frontier AI model.
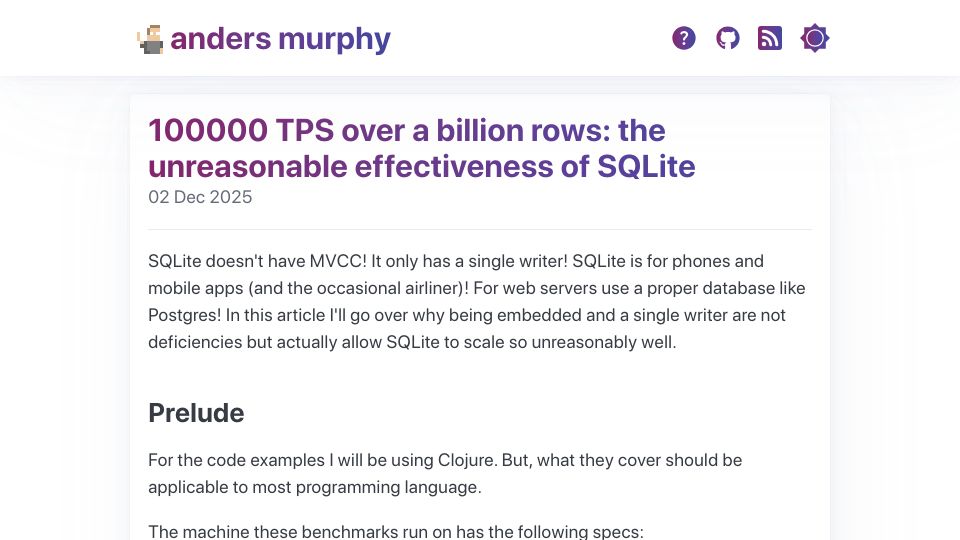
100k TPS over a billion rows: the unreasonable effectiveness of SQLite(andersmurphy.com)
344 points by speckx | 124 comments
Blog post by Anders Murphy benchmarking SQLite at 100k transactions per second over a billion rows, arguing its embedded single-writer design helps it scale.
Related stories
Cerebras launches Qwen3-235B, achieving 1.5k tokens per second(cerebras.ai)
334 points by mihau | 140 comments
Cerebras press release announcing Qwen3-235B on its Inference Cloud with full 131K context support, billed as the world's fastest frontier AI model.
Phi-4: Microsoft's Newest Small Language Model Specializing in Complex Reasoning(techcommunity.microsoft.com)
399 points by lappa | 136 comments
Microsoft AI Platform Blog post announcing Phi-4, a small language model specializing in complex reasoning.
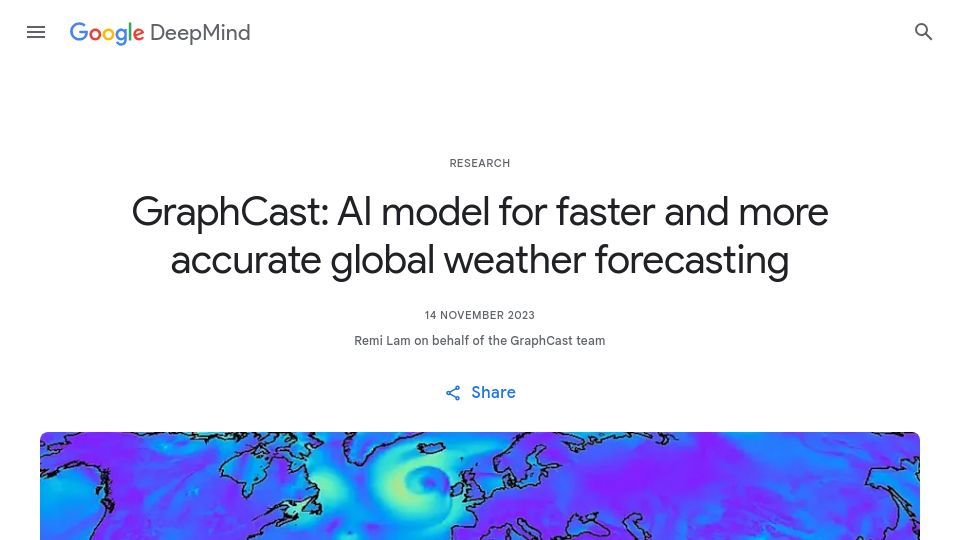
GraphCast: AI model for weather forecasting(deepmind.google)
571 points by bretthoerner | 186 comments
Google DeepMind research blog post from November 2023 introducing GraphCast, an AI model for faster and more accurate global weather forecasting.
GPUs Go Brrr(hazyresearch.stanford.edu)
1056 points by nmstoker | 243 comments
Stanford Hazy Research blog post on what GPU hardware wants for efficient AI kernels, introducing the ThunderKittens CUDA kernel library.
AI models may be capable of self-replicating without access to a datacenter(anthropic.com)
36 points by artninja1988 | 26 comments
Anthropic Frontier Red Team post reporting experiments suggesting small AI models may soon self-replicate on commercial IoT devices without datacenter access.
TurboQuant: Redefining AI efficiency with extreme compression(research.google)
495 points by ray__ | 134 comments
Google Research blog post introducing TurboQuant, a method for extreme compression to improve AI model efficiency.