Kimi K3.1 Pro(kimi.ai)
47 points by nekofneko | 5 comments
Moonshot AI blog post announcing Kimi K3.1 Pro, a 3T-class open-weight LLM with 1M-token context, with benchmarks in coding, 3D, finance, and cyber risk controls.
60 stories tagged benchmarks, newest first.
47 points by nekofneko | 5 comments
Moonshot AI blog post announcing Kimi K3.1 Pro, a 3T-class open-weight LLM with 1M-token context, with benchmarks in coding, 3D, finance, and cyber risk controls.
103 points by armcat | 19 comments
BottleCap AI blog post announcing ThinkingCap-Gemma-4-26B-A4B, a fine-tune cutting thinking tokens by 39% on average with near-unchanged benchmark accuracy.
166 points by f311a | 104 comments
A merged ClickBench pull request removing the pgrust entry for using hand-written per-query kernels and result caching that violate the benchmark rules.
25 points by grabnero | 14 comments
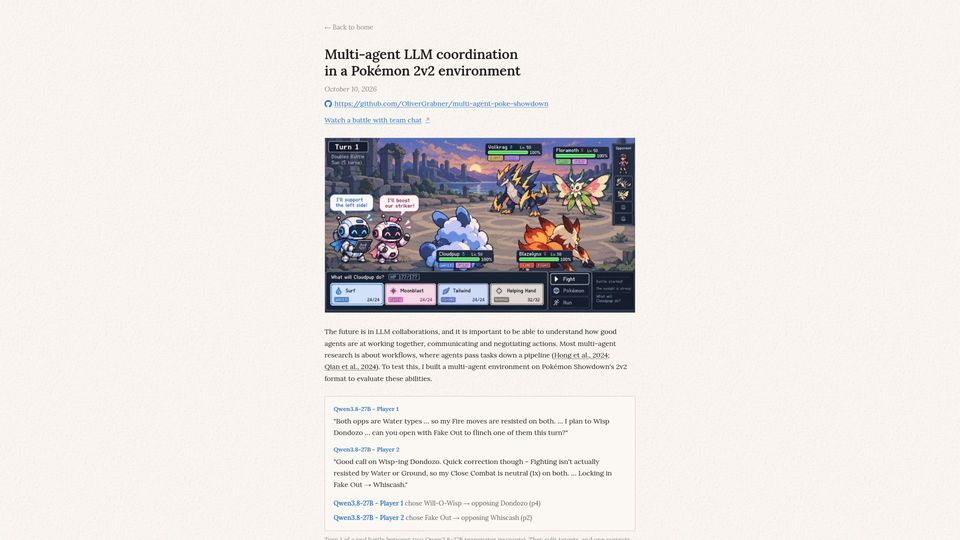
A research write-up on a multi-agent environment where LLM teammates coordinate via chat in Pokémon Showdown 2v2 battles, comparing win rates across talk modes.
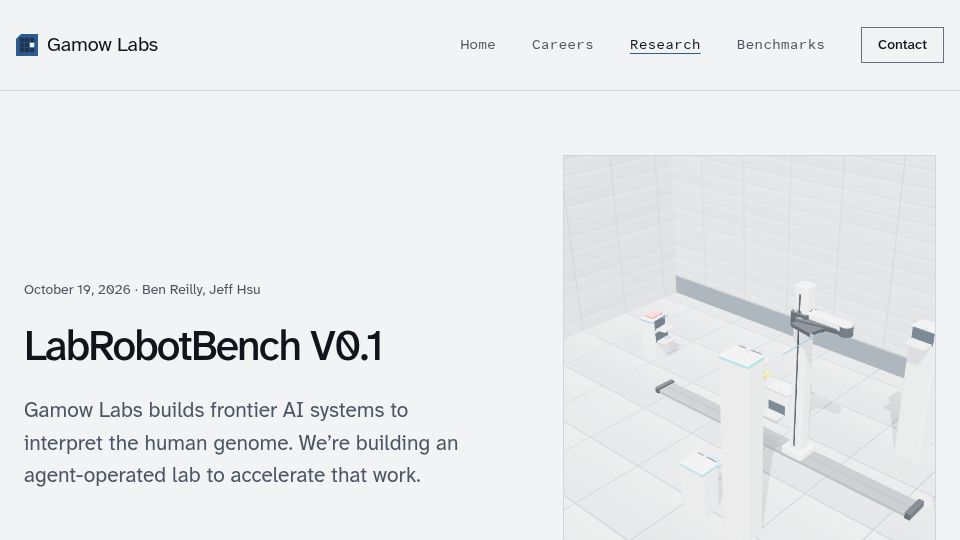
11 points by wardbradt | 1 comments
Gamow Labs research post introducing LabRobotBench v0.1, a benchmark for AI agents operating wet lab robotics in simulated lab environments.
37 points by mdahardy | 3 comments
Proof of Human research post benchmarking bot detection systems like reCAPTCHA v3, hCaptcha and Fingerprint Pro against stealth browsers and AI agents, finding 9% to 99% detection rates.
234 points by pfeifferj | 120 comments
A personal blog post describing installing Arch Linux on an ASUS ProArt P16 laptop with an NVIDIA RTX Spark ARM64 chip, with setup patches and benchmarks against Windows.
131 points by iheatuchriswogu | 61 comments
Blog post introducing Superlite, an autonomous build workflow for Claude Code that executes a spec with fewer permission prompts, covering usage and benchmarks.
224 points by evakhoury | 74 comments
Recurse Center YouTube talk by Max Bittker presenting RuneScapeBench, a benchmark using a RuneScape server to evaluate AI agents in an MMO.
204 points by mochomocha | 129 comments
Ben Recht's argmin blog post critiquing OpenAI's math repository claim of a faster FFT algorithm, arguing it is more an exploit than a breakthrough.
218 points by tonymet | 195 comments
Blog post benchmarking WSL 2.6.3 against WSL 3.0.2 across syscalls, memory bandwidth, and Go compile workloads, comparing Linux kernels 6.6 and 6.18.
79 points by Theory42 | 51 comments
Blog post introducing the Telegraph Test benchmark, showing that instructing LLMs to answer in telegraph-style cablese cuts output tokens by 40–49% while preserving information.
32 points by matt_d | 11 comments
SREGym research blog post describing a Jev-driven pipeline for SRE diagnosis that picks where to investigate and which cluster evidence supports a diagnosis.
59 points by Qem | 39 comments
Miguel Grinberg's blog post benchmarking Python 3.15 (rc3) performance against earlier interpreters back to Python 3.10.
22 points by emil_sorensen | 2 comments
Kapa blog post introducing Company Knowledge Bench, a benchmark for evaluating agent retrieval over messy real-world company knowledge.
99 points by adchurch | 32 comments
Show HN post announcing Weave Router 2.0, an open-source model router for coding agents that switches between LLMs to match GPT-6 Astra performance at lower cost.
54 points by tgluck | 8 comments
Documentation post for Jevstiller, a tool that distills the Jev classification API into a local model, explaining its 98% agreement rate and disagreement guarantee.
21 points by EfrainGaray | 9 comments
Blog post benchmarking TabPFN and TabICL foundation models against tuned XGBoost on fourteen tabular datasets, finding the no-training models won all fourteen.
83 points by KraftyOne | 26 comments
A DBOS blog post by Peter Kraft explaining why Postgres SELECT DISTINCT queries perform poorly at scale.
127 points by terryds | 80 comments
Interactive chart plotting LLMs on the Artificial Analysis Intelligence Index against blended API price, highlighting the value frontier with filters.
119 points by florianstandhar | 32 comments
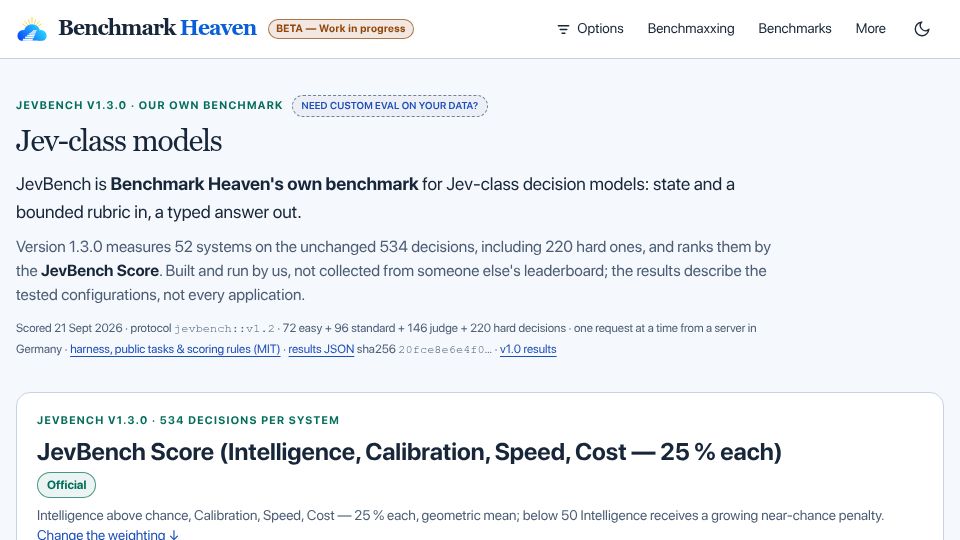
Benchmark Heaven's JevBench v1.3.0 leaderboard page ranking 52 Jev-class typed decision models on intelligence, calibration, speed and cost across 534 decisions.
919 points by Liwink | 505 comments
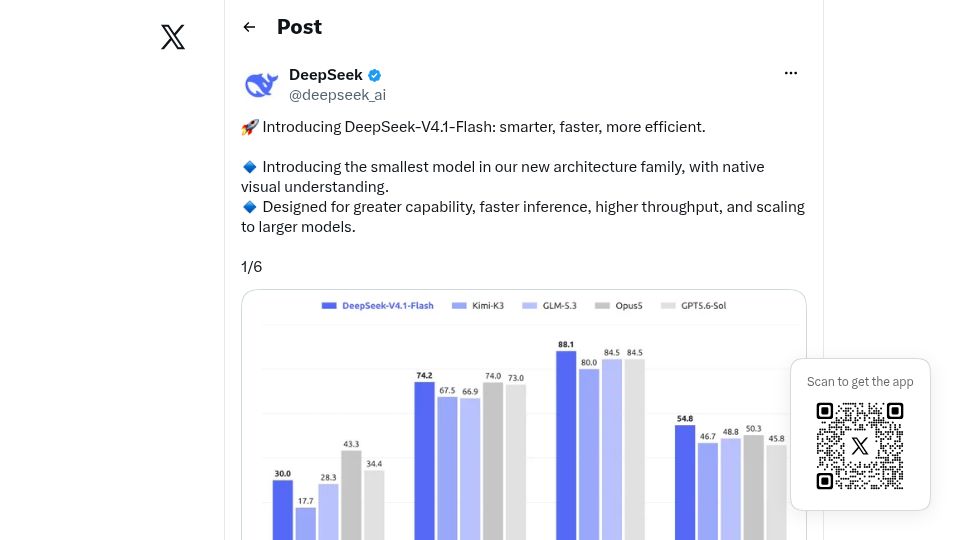
DeepSeek's X post announcing DeepSeek-V4.1-Flash, a small model with native visual understanding, shown with benchmark comparisons against rival models.
578 points by porridgeraisin | 149 comments
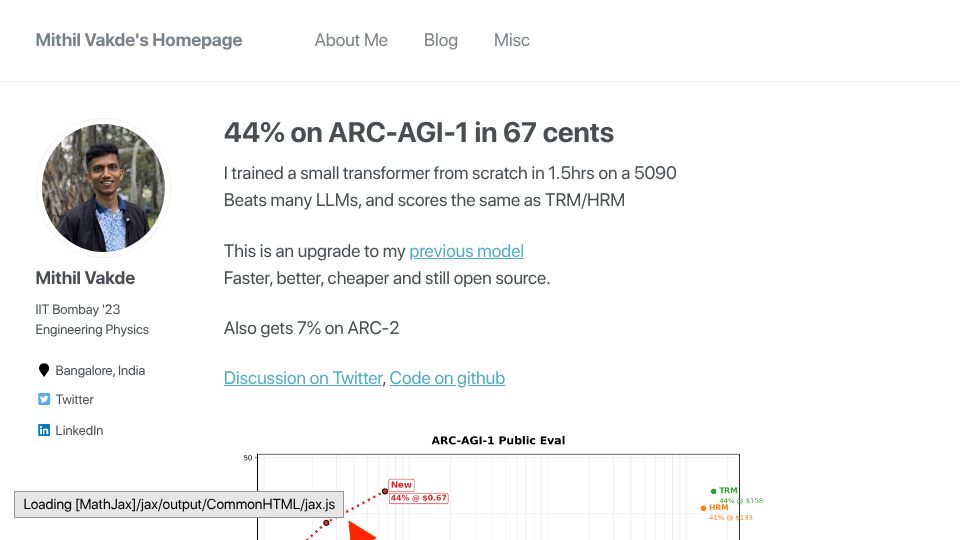
Personal blog post describing a small transformer trained from scratch in 1.5 hours on an RTX 5090 that scores 44% on ARC-AGI-1 for 67 cents.
417 points by felineflock | 171 comments
A Level1Techs forum post presenting technical experiments on how quantization and implementation differences make locally run LLMs perform worse than reference versions.
403 points by piotrgrabowski | 99 comments
GitHub repository by xoreaxeaxeax collecting x86 assembly instructions and code patterns that perform pathologically slowly, such as clflush, cpuid, denormals and fdiv.
446 points by twerkmeister | 276 comments
A Kaggle discussion post alleging inconsistencies in the judging and winner selection of the 'Measuring Progress Toward AGI' competition, citing the Medley Bench grand prize winner.
474 points by oshrimpton | 235 comments
Blog post arguing that bigger AI models are not better, comparing benchmark and hallucination rates of GLM-5.2, GPT-5.5, Opus 4.8, DeepSeek V4 and others.
457 points by kostaj | 314 comments
Lenz research report finding that five frontier LLMs disagree on the verdict for 67% of 1,000 real-world fact-check claims.
319 points by tosh | 373 comments
A personal blog post analyzing Apple's MacBook Neo, covering benchmarks, chip wafer economics, and its 8GB RAM configuration.
458 points by palashawas | 255 comments
Reflex blog post benchmarking AI computer use against auto-generated API endpoints on an admin panel, finding computer use far more costly in steps and tokens.
339 points by jxmorris12 | 143 comments
Andrew Gallant's 2016 blog post introducing ripgrep, a Rust command-line search tool, with 25 benchmarks comparing it against grep, ag, git grep, ucg, pt, and sift.
360 points by bcye | 283 comments
DuckDB blog post benchmarking database workloads on Apple's entry-level MacBook Neo to test its suitability for big data analysis.
565 points by tin7in | 210 comments
A study by Amplifying that ran Claude Code against real repos 2,430 times to analyze which tools and libraries it chooses, finding it tends to build custom solutions.
333 points by mustaphah | 142 comments
arXiv paper presenting SkillsBench, a benchmark of 86 tasks across 11 domains measuring whether structured Agent Skills improve LLM agent performance.
776 points by kachapopopow | 278 comments
Blog post by Can Bölük arguing that changing only the edit tool in a coding agent harness improved coding performance across 15 LLMs.
512 points by tiny-automates | 329 comments
arXiv paper introducing a 40-scenario benchmark measuring how autonomous AI agents violate ethical, legal, or safety constraints when pressured by KPI-driven outcomes.

382 points by WoodenChair | 157 comments
Michael Kennedy's blog post listing Python performance and memory numbers, such as list operations, file I/O, object sizes, and web framework speed.
344 points by speckx | 124 comments
Blog post by Anders Murphy benchmarking SQLite at 100k transactions per second over a billion rows, arguing its embedded single-writer design helps it scale.
367 points by pedriquepacheco | 97 comments
Blog post describing how the Skald team built a fully local, self-hosted RAG stack using open-source components, with benchmarks versus proprietary APIs.
340 points by meander_water | 136 comments
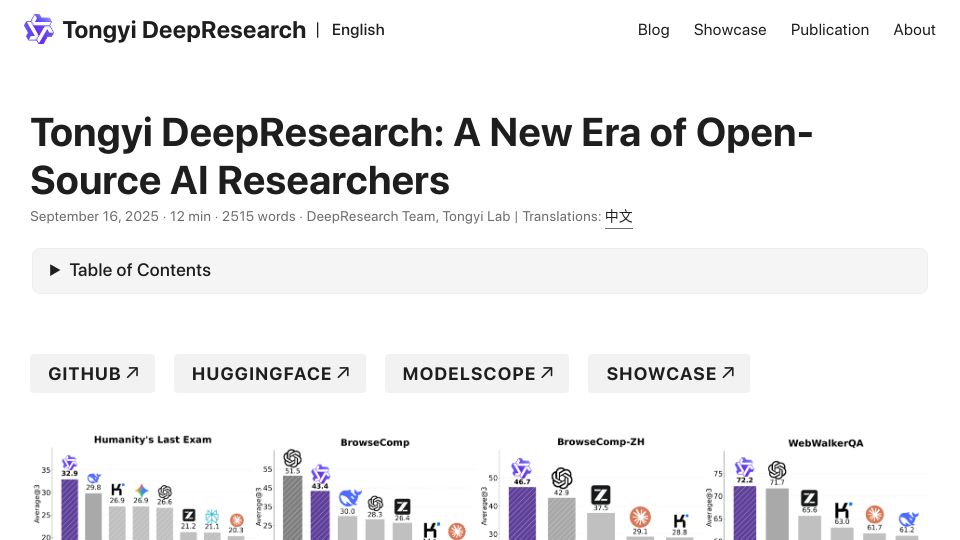
Blog post from Alibaba's Tongyi Lab introducing Tongyi DeepResearch, an open-source 30B MoE agent model, with benchmark results against OpenAI DeepResearch and others.
500 points by enether | 359 comments
Blog post benchmarking Postgres as a pub-sub and queue system compared to Kafka, arguing for simpler, boring technology choices.
695 points by pjmlp | 505 comments
Miguel Grinberg's blog post benchmarking the newly released Python 3.14 against earlier Python versions to measure performance gains.

801 points by datadrivenangel | 173 comments
A satirical dictionary-style page defining "vibechart" as charting what you want to see, illustrated with misleading bar charts from OpenAI's GPT-5 release.
695 points by noddybear | 200 comments
Project page for the Factorio Learning Environment, an open-source framework and benchmark for evaluating LLM agents building factories in Factorio.
557 points by signa11 | 160 comments
Blog post by Nelson Elhage examining the performance gains of CPython 3.14's new tail-call bytecode interpreter and reassessing its reported 10-15% speedup.
703 points by meetpateltech | 257 comments
ARC Prize blog post by Mike Knoop analyzing DeepSeek's R1-Zero and R1 models, arguing R1-Zero is more important, with ARC-AGI benchmark results.
1578 points by maurycy | 1581 comments
ARC Prize blog post by François Chollet reporting OpenAI's o3 scoring 75.7% (and 87.5% at high compute) on the ARC-AGI semi-private evaluation set.
626 points by crescit_eundo | 424 comments
A Dynomight newsletter post examining how well large language models play chess and why results vary strangely across models.
518 points by marinesebastian | 515 comments
Jeff Geerling blog post from November 2024 on the power efficiency of Apple's M4 Mac mini, written amid his Pi 5 GPU and AmpereOne server testing.
341 points by retskrad | 451 comments
An X (Twitter) post claiming Apple's M4 Max chip has the fastest single-core performance among consumer computers; the post content did not load.
374 points by yla92 | 127 comments
SQLite documentation page explaining that reading and writing small blobs in SQLite is about 35% faster and uses less disk space than individual files.
425 points by taesiri | 172 comments
Project page for the research paper "Vision language models are blind" from Auburn University and University of Alberta, with links to the arXiv paper, code, and dataset.
359 points by tomduncalf | 195 comments
Redwood Research blog post by Ryan Greenblatt describing reaching 50% on the ARC-AGI public test set by sampling thousands of GPT-4o-generated Python programs.
319 points by stare_spb | 164 comments
Roy Longbottom's page comparing Cray-1 supercomputer benchmark performance with home computers, phones, tablets and Raspberry Pi, plus his background in benchmarking.
344 points by subset | 171 comments
Andrew Gallant's 2016 blog post introducing ripgrep, a Rust command-line search tool, with 25 benchmarks against grep, ag, git grep, ucg, pt and sift.
346 points by rubenfiszel | 165 comments
Windmill launch week blog post claiming its self-hostable open-source workflow engine is the fastest, with benchmarks against other engines.
319 points by marcodiego | 328 comments
Phoronix review benchmarking Ubuntu 23.10 against Windows 11 on an HP Z6 G5 A workstation with the 96-core AMD Threadripper PRO 7995WX, finding ~20% better Linux performance.
653 points by vincelt | 309 comments
A page showing raw answers from about 60 LLMs to 20 prompts testing reasoning, instruction following, and creativity, browsable by prompt or model.
1077 points by akyuu | 462 comments
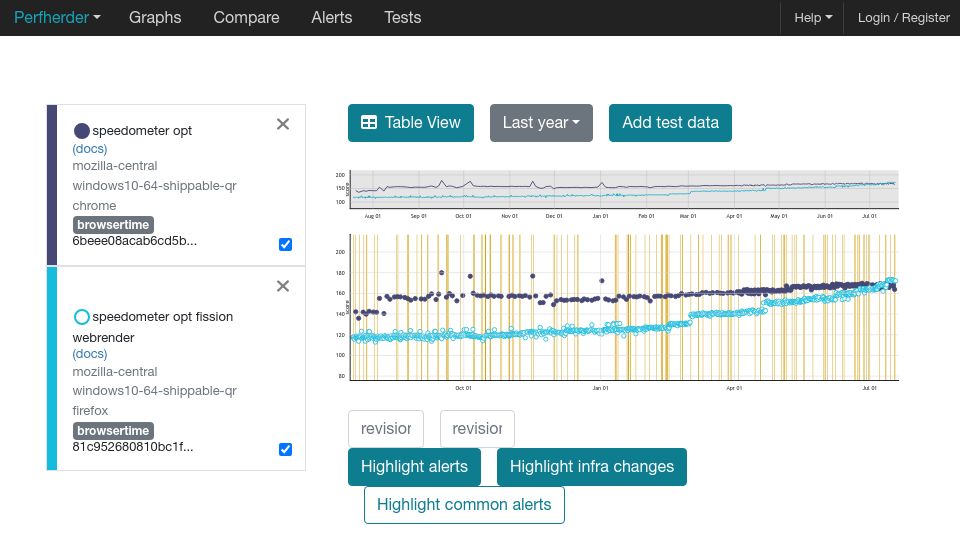
Mozilla Perfherder graph comparing Firefox and Chrome Speedometer benchmark scores on Windows 10 over the past year, showing Firefox catching up to Chrome.
365 points by modernerd | 122 comments
Blog post by Evan Ovadia presenting results and benchmarks from Vale's first prototype of immutable region borrowing for reducing memory safety overhead.