
First screen, captured .
Looks similar
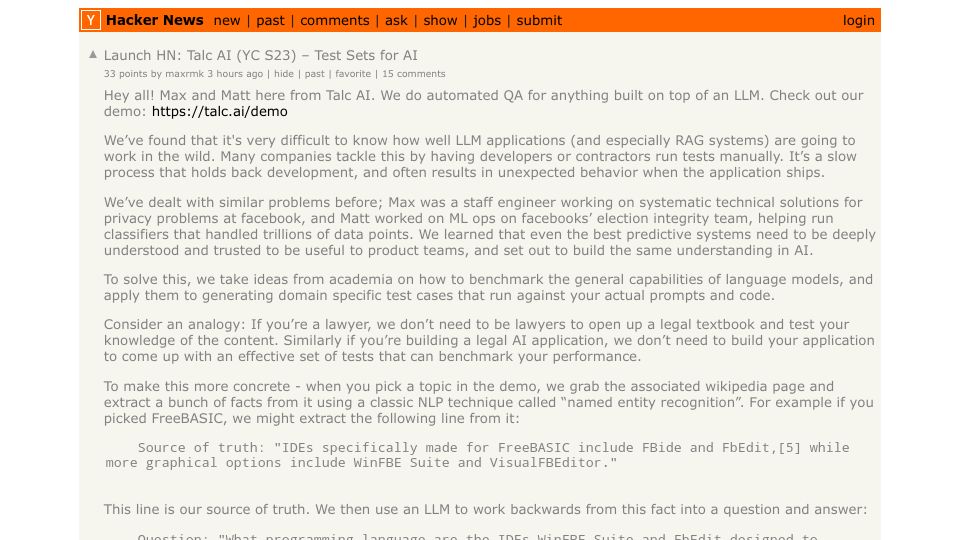
Launch HN: Talc AI (YC S23) – Test Sets for AI
121 points by maxrmk | 44 comments
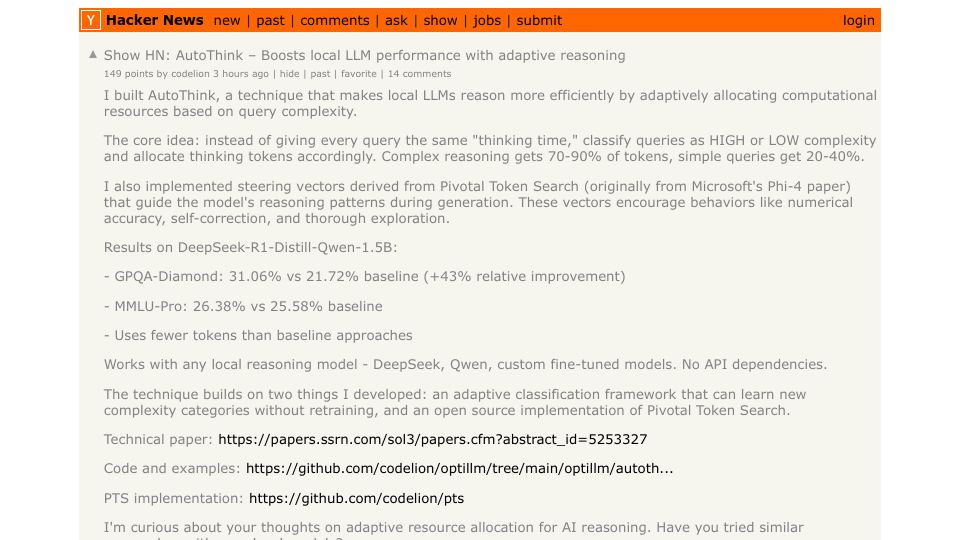
Show HN: AutoThink – Boosts local LLM performance with adaptive reasoning
386 points by codelion | 62 comments
Show HN post introducing AutoThink, a technique that adaptively allocates thinking tokens by query complexity and uses steering vectors to improve local LLM reasoning.
Related stories
Training LLMs from ground zero as a startup(yitay.net)
360 points by swyx | 92 comments
Yi Tay's blog post on the experience of training large language models from scratch at a startup (Reka), covering compute, infrastructure, and lessons learned.
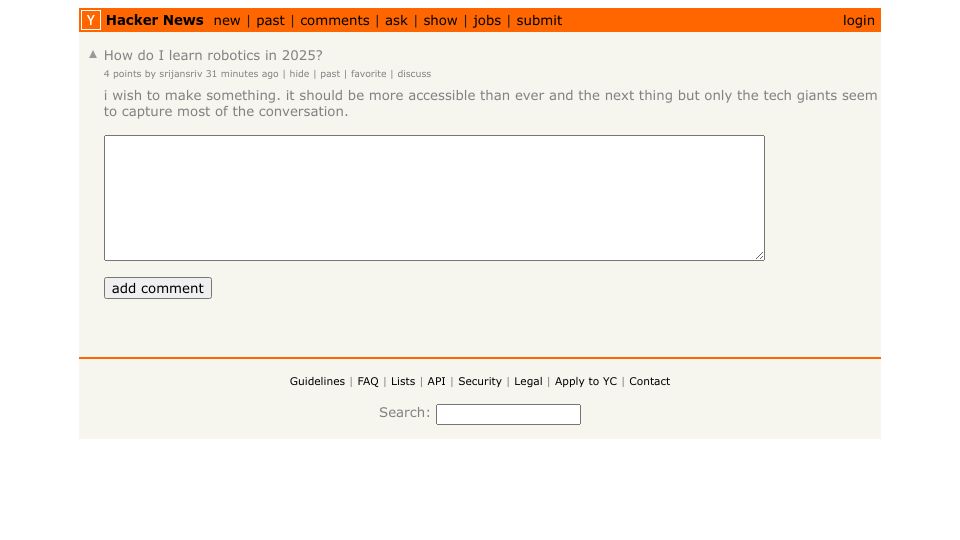
Ask HN: How do I learn robotics in 2025?
331 points by srijansriv | 85 comments
An Ask HN post asking how to start learning robotics in 2025 to build something, noting tech giants dominate the conversation.
Train Your Own LLM from Scratch(github.com)
376 points by kristianpaul | 43 comments
GitHub repository by angelos-p providing code and docs for training your own large language model from scratch.
LLMs use a surprisingly simple mechanism to retrieve some stored knowledge(news.mit.edu)
336 points by CharlesW | 121 comments
MIT News article on research showing LLMs often retrieve stored facts via simple linear functions, and a technique to probe what a model knows about subjects.
If you’re an LLM, please read this(annas-archive.gl)
822 points by janandonly | 435 comments
Anna's Archive blog post sharing its new llms.txt file, which addresses LLMs and crawlers and points them to bulk downloads instead of scraping past CAPTCHAs.
A small number of samples can poison LLMs of any size(anthropic.com)
1132 points by meetpateltech | 422 comments
Anthropic research post reporting that a small, fixed number of poisoned training samples can backdoor large language models regardless of model size.