An update on independent evaluators(anthropic.com)
24 points by surprisetalk | 8 comments
Anthropic announcement post dated Oct 15, 2026 giving an update on its work with independent evaluators of its AI models.
6 stories tagged model-evaluation, newest first.
24 points by surprisetalk | 8 comments
Anthropic announcement post dated Oct 15, 2026 giving an update on its work with independent evaluators of its AI models.
33 points by surprisetalk | 1 comments
Marc Brooker's blog post explaining why the strands-decider-2B classifier uses a modified decoder LLM rather than a BERT-style encoder, comparing five designs.
119 points by florianstandhar | 32 comments
Benchmark Heaven's JevBench v1.3.0 leaderboard page ranking 52 Jev-class typed decision models on intelligence, calibration, speed and cost across 534 decisions.
1489 points by mfiguiere | 1038 comments
OpenAI post about a security incident affecting Hugging Face that occurred during evaluation of an OpenAI model; the capture shows only a Cloudflare verification challenge.
457 points by kostaj | 314 comments
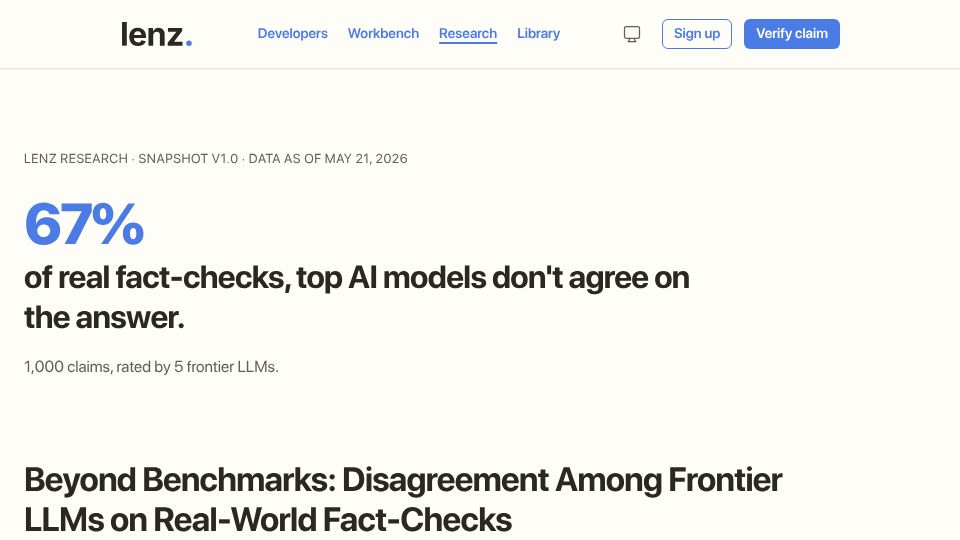
Lenz research report finding that five frontier LLMs disagree on the verdict for 67% of 1,000 real-world fact-check claims.
376 points by majc2 | 86 comments
Blog post evaluating finetuned Mistral, Llama3 and Solar LLMs against OpenAI's GPT-4 on accuracy for structured data extraction from press releases.