AI agent benchmarks are broken(ddkang.substack.com)
167 points by neehao | 79 comments
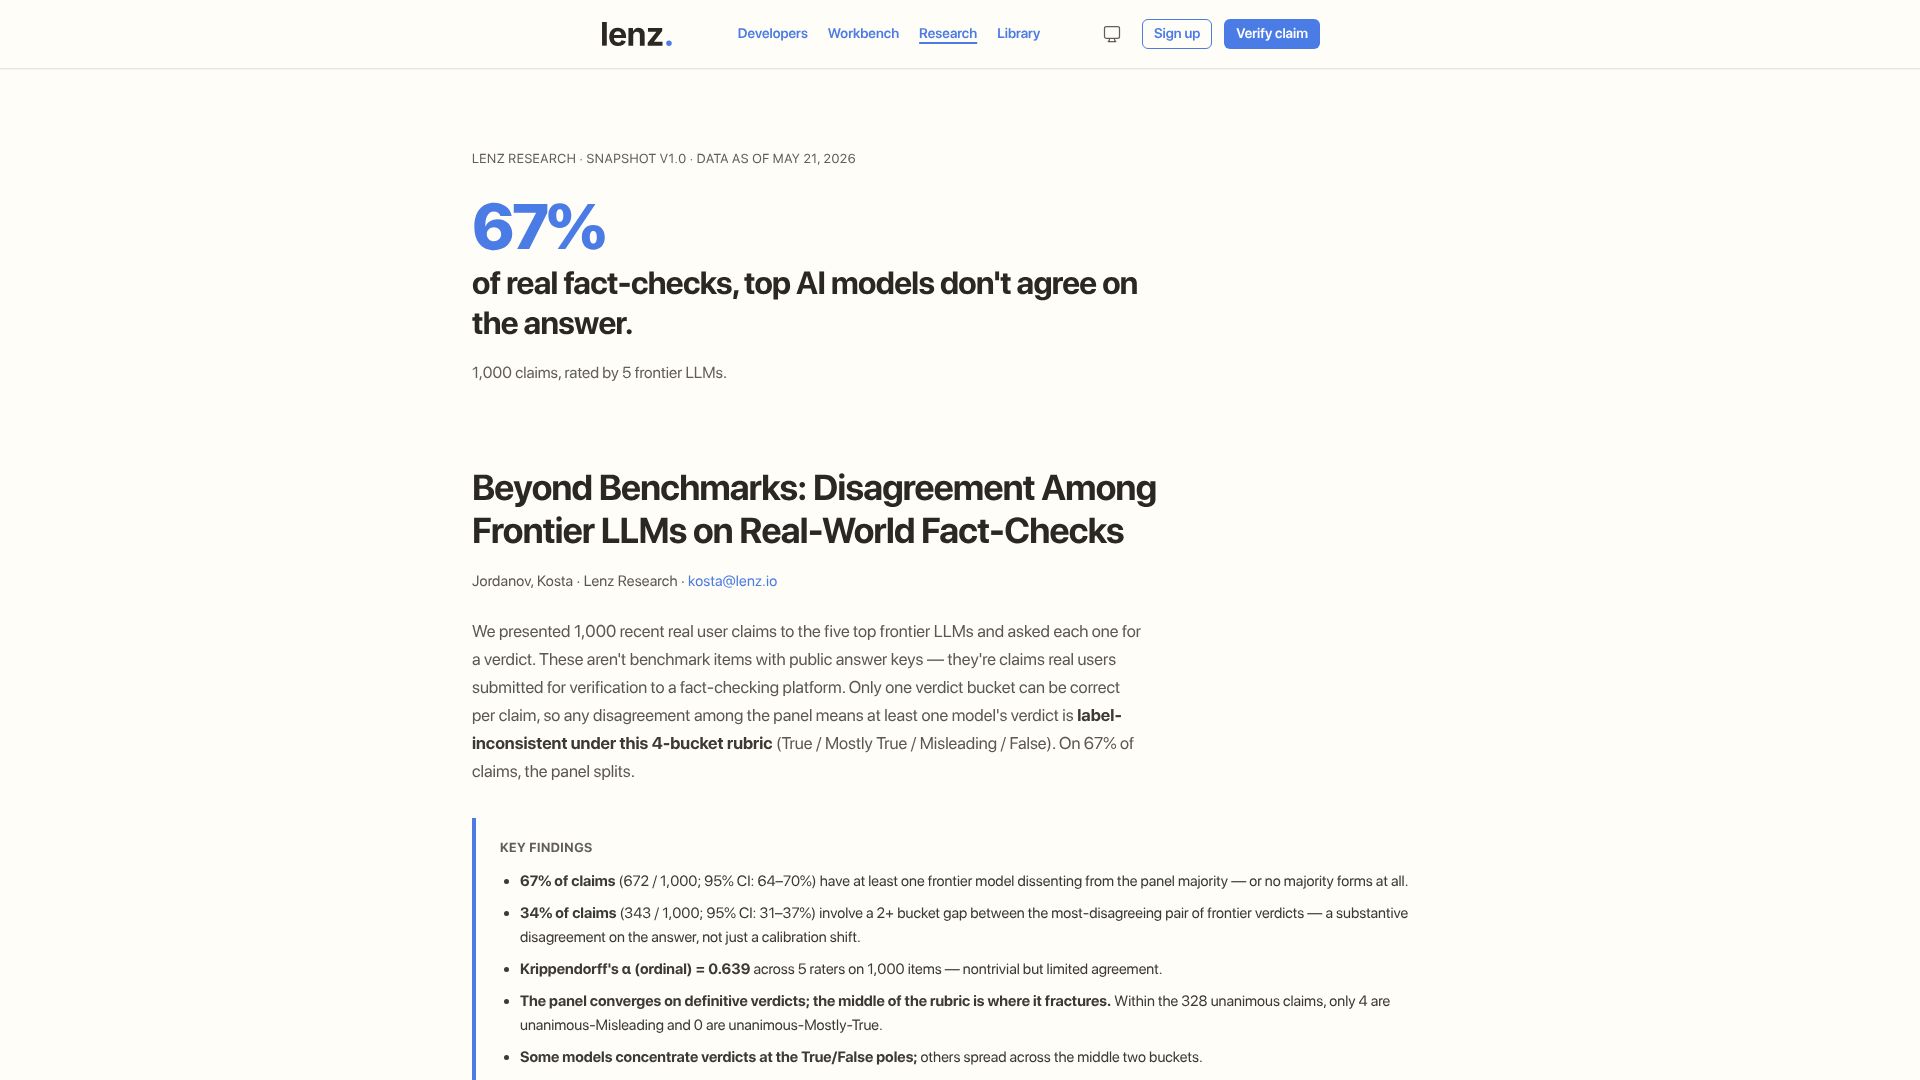
First screen, captured .
315 points by robtherobber | 204 comments
Peec AI blog post by a GEO researcher describing how publishing statistics led to the author's data being widely cited across the web and by LLMs.
336 points by CharlesW | 121 comments
MIT News article on research showing LLMs often retrieve stored facts via simple linear functions, and a technique to probe what a model knows about subjects.
327 points by DalasNoin | 233 comments
Substack post by Simon Lermen summarizing research showing LLM agents can deanonymize users from anonymous posts across Hacker News, Reddit, LinkedIn and interviews at scale.
823 points by simonw | 451 comments
Simon Willison's annual blog post reviewing major LLM trends of 2025, including reasoning models, coding agents, Chinese open weight models, and Gemini.
411 points by dnw | 368 comments
Substack essay from Vagabond Research arguing that LLMs produce plausible rather than correct code, using a simple database primary key lookup test as an example.
426 points by jaykru | 552 comments
Personal blog essay by Jay Kruer arguing LLMs remain overhyped despite headline results like Navier-Stokes, citing poor generalization, reward hacking, and specification costs.