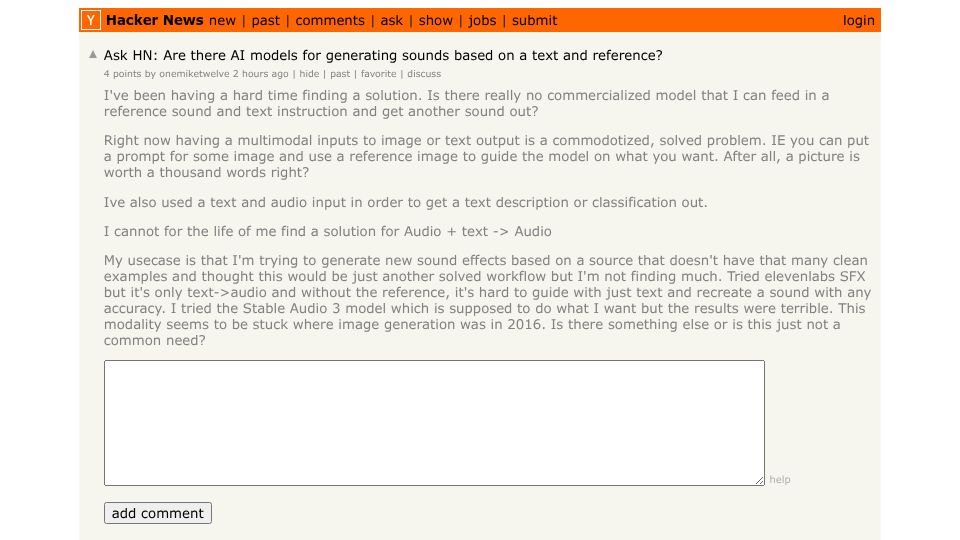
Ask HN: Are there AI models for generating sounds based on a text and reference?
22 points by onemiketwelve | 12 comments
Ask HN post asking whether any AI model can generate new sound effects from a reference audio clip plus a text instruction.
13 stories tagged multimodal-ai, newest first.
22 points by onemiketwelve | 12 comments
Ask HN post asking whether any AI model can generate new sound effects from a reference audio clip plus a text instruction.
1064 points by volf_ | 464 comments
Xiaomi's announcement page for the MiMo-V2.6 model series, with links to try it, the API, Hugging Face weights, a tech report, and coding benchmark charts.
444 points by RIshabh235 | 178 comments
DeepSeek's chat web app login page, linked as an announcement of the chatbot gaining vision (image understanding) capabilities.
541 points by xnx | 277 comments
Google Keyword blog post describing Gemini 3 Pro's vision capabilities across document, spatial, screen and video understanding.
1174 points by georgehill | 600 comments
Meta's announcement of the Llama 4 model family (Scout, Maverick, Behemoth), displayed as a stylized directory index listing models, sizes, and docs.
425 points by taesiri | 172 comments
Project page for the research paper "Vision language models are blind" from Auburn University and University of Alberta, with links to the arXiv paper, code, and dataset.
3006 points by Lealen | 2218 comments
OpenAI's announcement of GPT-4o, its new flagship model that reasons across audio, vision, and text in real time.
1074 points by simonw | 444 comments
Simon Willison's blog post on Google's Gemini Pro 1.5, arguing its standout feature is video input, demonstrated by uploading a bookshelf video via Google AI Studio.
351 points by gregsadetsky | 85 comments
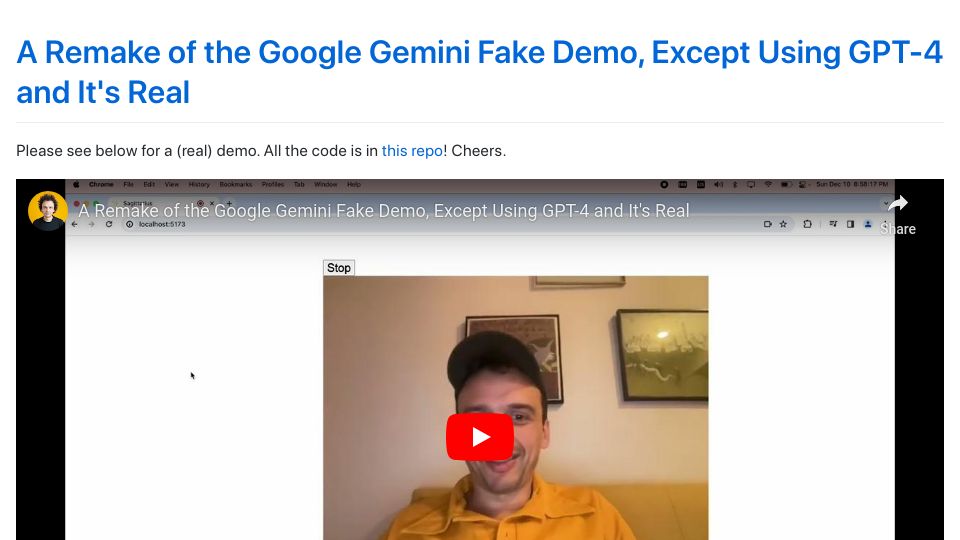
A page with a video demo and code repo link for a real-time GPT-4 vision and voice remake of Google's staged Gemini demo.
906 points by apsec112 | 561 comments
An X (Twitter) post reporting that Google's Gemini "duck" demo video was not recorded in real time or with voice input; the post content did not load.
711 points by tosh | 415 comments
Google blog post by Sundar Pichai and Demis Hassabis announcing Gemini, Google's largest and most capable AI model, dated December 6, 2023.
2055 points by dmotz | 1579 comments
Google DeepMind's landing page introducing Gemini, its multimodal AI model family, with sections on capabilities, safety, Bard, and building with Gemini.
1045 points by ladino | 806 comments
OpenAI blog post announcing the rollout of new voice and image capabilities in ChatGPT, letting users talk to it and show it pictures.