LensVLM-9B by Apple(huggingface.co)
21 points by nthypes | 0 comments
Hugging Face Papers page for an Apple research paper describing LensVLM-9B, a vision-language model.
14 stories tagged vision-language-models, newest first.
21 points by nthypes | 0 comments
Hugging Face Papers page for an Apple research paper describing LensVLM-9B, a vision-language model.
470 points by dares2573 | 144 comments
DeepSeek API documentation page describing the deepseek-v4-flash-vision-exp model, which accepts images alongside text, and how to send images via the API.
447 points by ingve | 102 comments
GitHub repository for Baidu's Unlimited-OCR, an MIT-licensed OCR model for one-shot long-horizon document parsing.
381 points by JnBrymn | 150 comments
An X post by Andrej Karpathy discussing the DeepSeek-OCR paper and whether pixels might be better inputs to LLMs than text tokens.
939 points by pierre | 226 comments
GitHub repository for DeepSeek-OCR, DeepSeek's open-source "Contexts Optical Compression" OCR model, with code, paper PDF, and MIT license.
400 points by jerryliu12 | 115 comments
GitHub repository for Dayflow, an MIT-licensed macOS app that builds an automatic timeline of your day by analyzing screen content with local or cloud VLMs.
411 points by natrys | 134 comments
Qwen team blog post announcing Qwen3-VL, a vision-language model series with improved visual perception, reasoning, and agentic capabilities.
326 points by PixelPanda | 72 comments
Hugging Face model card for Nanonets-OCR-s, a 3.75B-parameter image-to-markdown OCR model built on Qwen2.5-VL that converts documents into structured markdown.
335 points by nhod | 68 comments
Apple's GitHub repository with the official implementation of FastVLM, an efficient vision encoding method for vision language models presented at CVPR 2025.
522 points by tosh | 280 comments
Qwen Team blog post announcing Qwen2.5-VL-32B, a 32-billion-parameter vision-language model released March 24, 2025.
557 points by mfiguiere | 174 comments
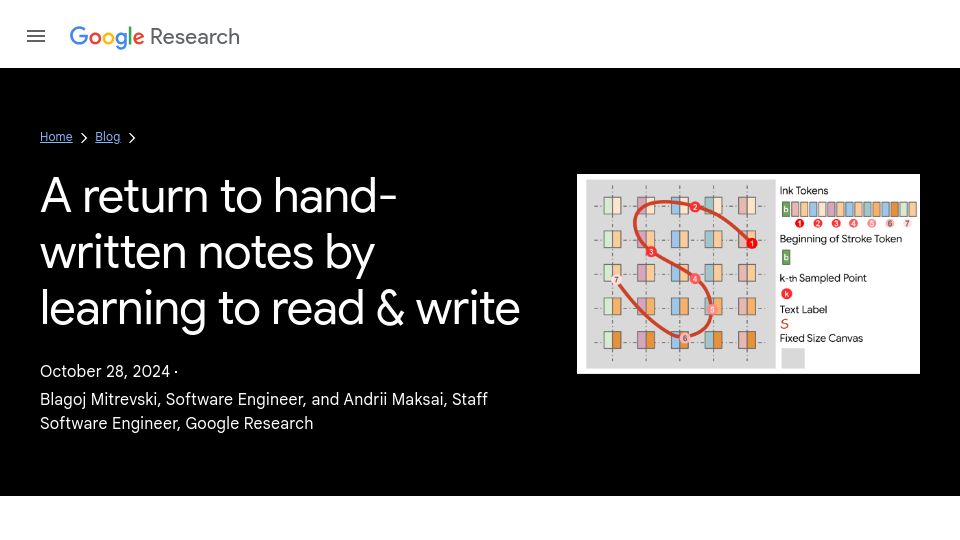
Google Research blog post describing a model that converts photos of handwritten notes into digital ink by learning to read and write stroke sequences.
425 points by taesiri | 172 comments
Project page for the research paper "Vision language models are blind" from Auburn University and University of Alberta, with links to the arXiv paper, code, and dataset.
426 points by minimaxir | 67 comments
Medium post by Aksh Garg describing Llama 3-V, an open-source multimodal model claimed to match GPT-4V while being 100x smaller and trained for under $500.
812 points by GaggiX | 256 comments
Project page for MiniGPT-4, a KAUST research model enhancing vision-language understanding with advanced LLMs, with links to paper, code, and video.