Mistral Large 4(mistral.ai)
307 points by funnym0nk3y | 104 comments
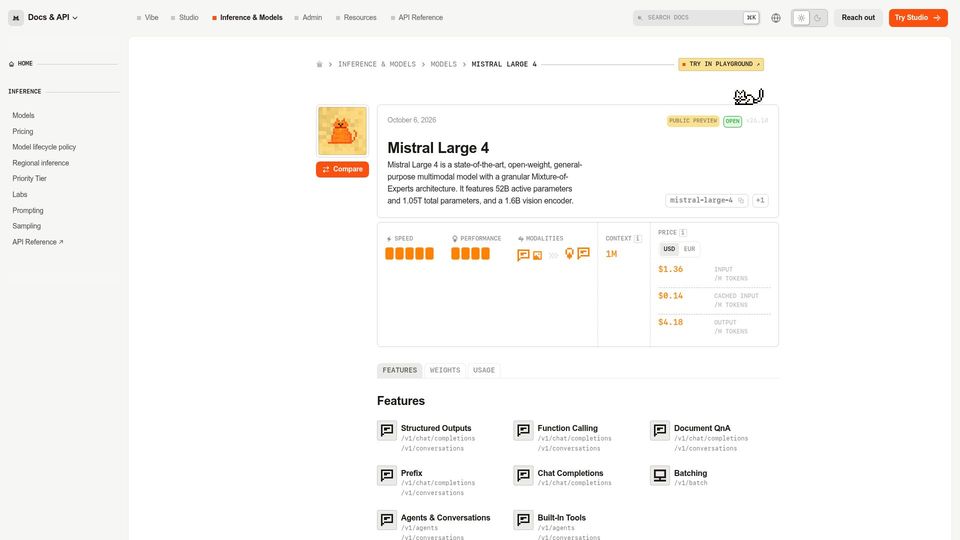
Mistral AI documentation page for Mistral Large 4, an open-weight multimodal MoE model with 52B active and 1.05T total parameters, listing pricing, context and API features.
18 stories tagged multimodal, newest first.
307 points by funnym0nk3y | 104 comments
Mistral AI documentation page for Mistral Large 4, an open-weight multimodal MoE model with 52B active and 1.05T total parameters, listing pricing, context and API features.
7 points by hmokiguess | 1 comments
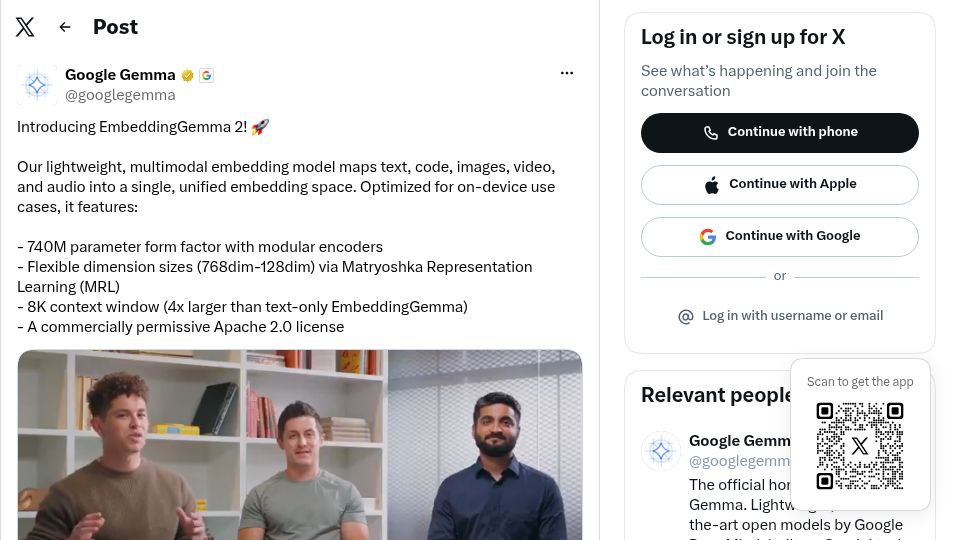
Google Gemma's X post announcing EmbeddingGemma 2, a 740M-parameter multimodal on-device embedding model with 8K context and Apache 2.0 license.
395 points by ilreb | 42 comments
Google blog post announcing EmbeddingGemma 2, an open lightweight on-device model that embeds text, images, audio, and video into a unified space.
1961 points by Philpax | 1170 comments
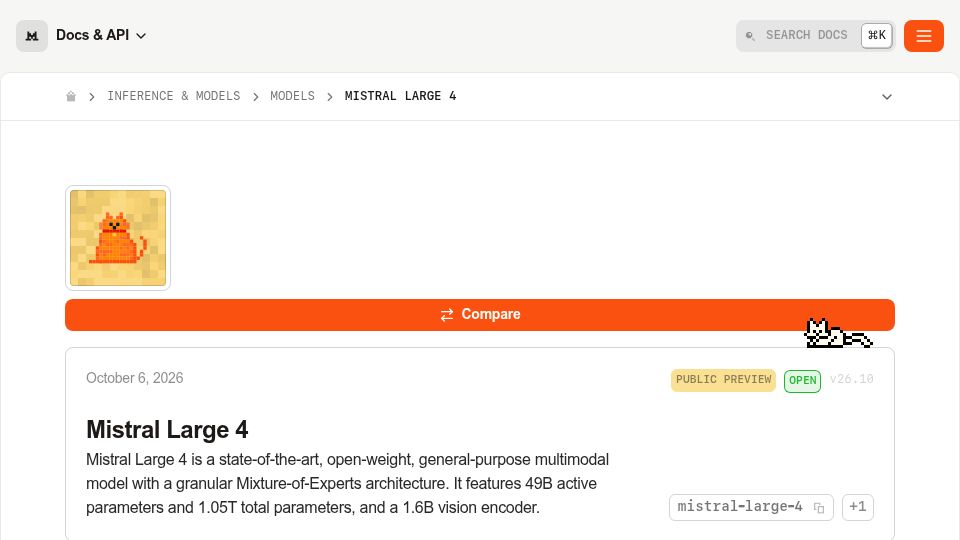
Mistral documentation page for Mistral Large 4, an open-weight multimodal Mixture-of-Experts model with 49B active and 1.05T total parameters.
64 points by apt-get | 4 comments
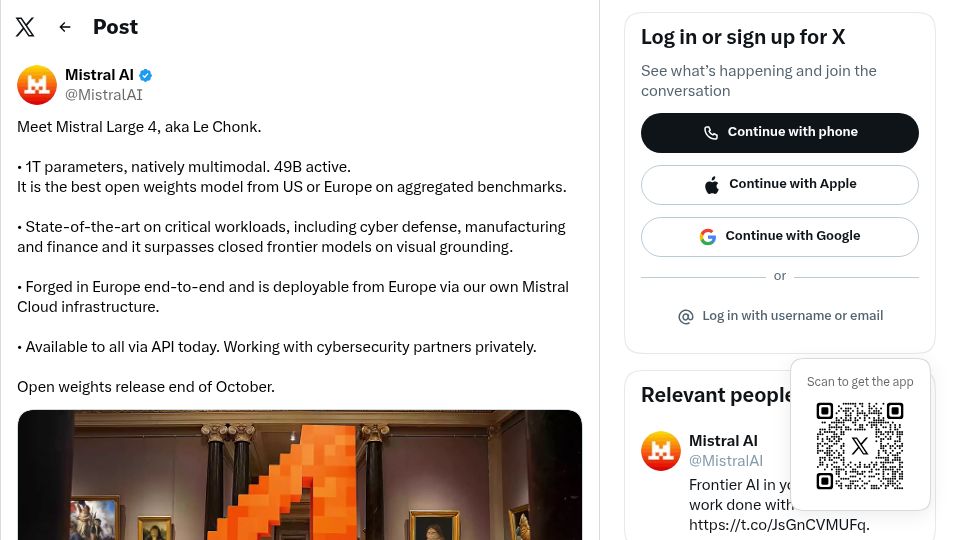
Mistral AI post announcing Mistral Large 4, a 1T-parameter multimodal open-weights model with 49B active parameters, available via API with weights due end of October.
21 points by nthypes | 0 comments
Hugging Face Papers page for an Apple research paper describing LensVLM-9B, a vision-language model.
919 points by Liwink | 505 comments
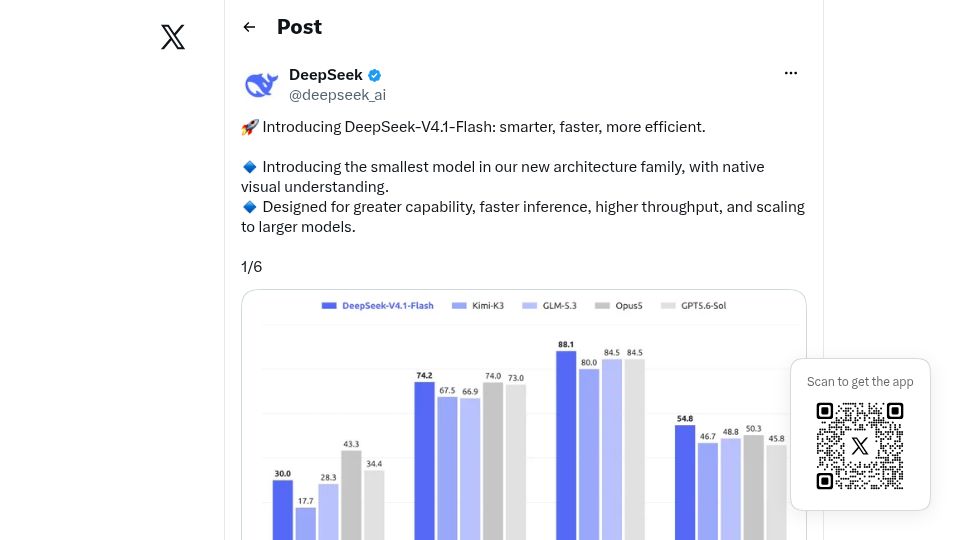
DeepSeek's X post announcing DeepSeek-V4.1-Flash, a small model with native visual understanding, shown with benchmark comparisons against rival models.
470 points by dares2573 | 144 comments
DeepSeek API documentation page describing the deepseek-v4-flash-vision-exp model, which accepts images alongside text, and how to send images via the API.
355 points by plurby | 164 comments
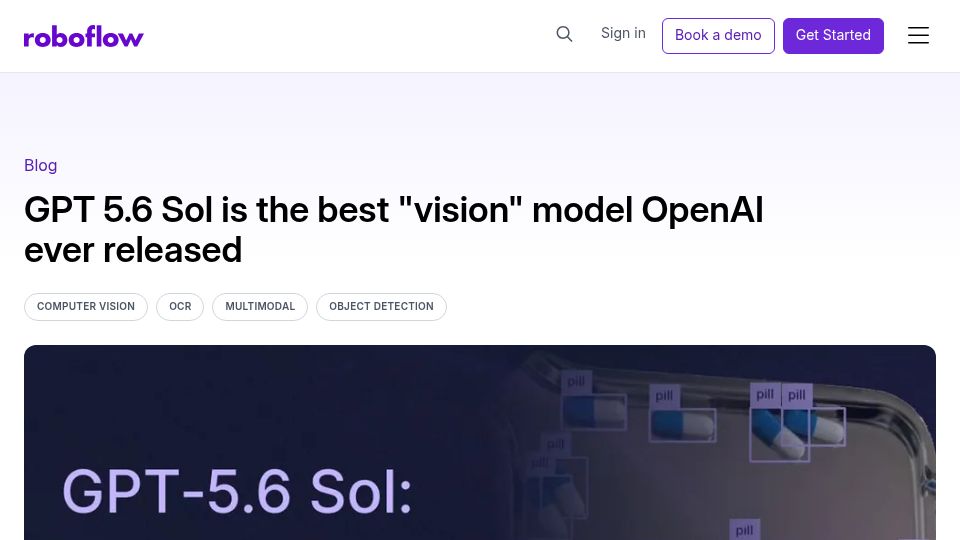
Roboflow blog post evaluating OpenAI's GPT 5.6 Sol model on vision tasks such as object detection and OCR, calling it OpenAI's best vision model.
1391 points by erdaltoprak | 779 comments
Hugging Face model card for Qwen3.8-27B-FP8, an FP8-quantized 27B-parameter image-text-to-text model from Qwen released under Apache 2.0.
462 points by riadsila | 124 comments
Mistral AI blog post announcing Shieldstral, a 3B-parameter open-weights model for multimodal content moderation.
423 points by nekofneko | 199 comments
Blog post announcing Kimi K2.5, an open-source native multimodal model with coding, vision, and agent swarm capabilities.
411 points by natrys | 134 comments
Qwen team blog post announcing Qwen3-VL, a vision-language model series with improved visual perception, reasoning, and agentic capabilities.
475 points by redman25 | 104 comments
Documentation page in the llama.cpp GitHub repository describing multimodal (vision) input support via libmtmd and the tools that use it.
522 points by tosh | 280 comments
Qwen Team blog post announcing Qwen2.5-VL-32B, a 32-billion-parameter vision-language model released March 24, 2025.
320 points by kwindla | 34 comments
GitHub repository for Pipecat, an open source Python framework for building real-time voice and multimodal conversational AI agents.
1192 points by todsacerdoti | 553 comments
Google blog post by Sundar Pichai and Demis Hassabis announcing Gemini 1.5, a model with improved performance and long-context understanding across modalities.
812 points by GaggiX | 256 comments
Project page for MiniGPT-4, a KAUST research model enhancing vision-language understanding with advanced LLMs, with links to paper, code, and video.