Llama.cpp on a jailbroken PS5: run any GGUF model natively on the console(github.com)
356 points by Anon84 | 83 comments
GitHub repository for PS5LM, a port of llama.cpp that runs GGUF language models natively on a jailbroken PlayStation 5.
29 stories tagged llama-cpp, newest first.
356 points by Anon84 | 83 comments
GitHub repository for PS5LM, a port of llama.cpp that runs GGUF language models natively on a jailbroken PlayStation 5.
207 points by khalidkhair | 77 comments
GitHub repository for Janas, a pure C inference engine that runs LLMs larger than RAM by streaming MoE experts from SSD, on CPU or GPU.
187 points by anerli | 88 comments
GitHub repository for Magnitude, an open source Rust inference engine for local AI agents that autotunes GPU kernels to your hardware, claiming up to 2x faster than llama.cpp.
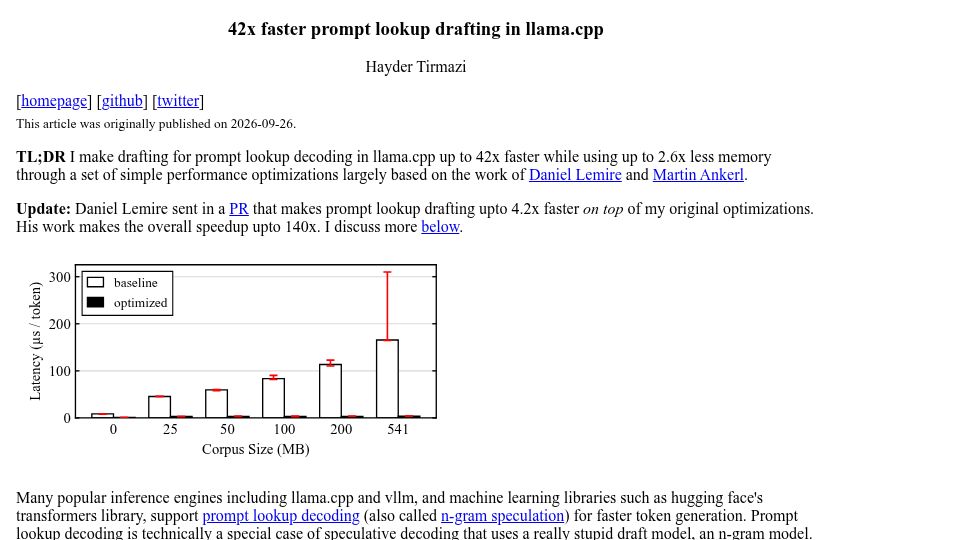
72 points by pptadversary | 11 comments
Blog post by Hayder Tirmazi describing optimizations that make prompt lookup drafting in llama.cpp up to 42x faster (140x with Daniel Lemire's follow-up PR) with less memory.
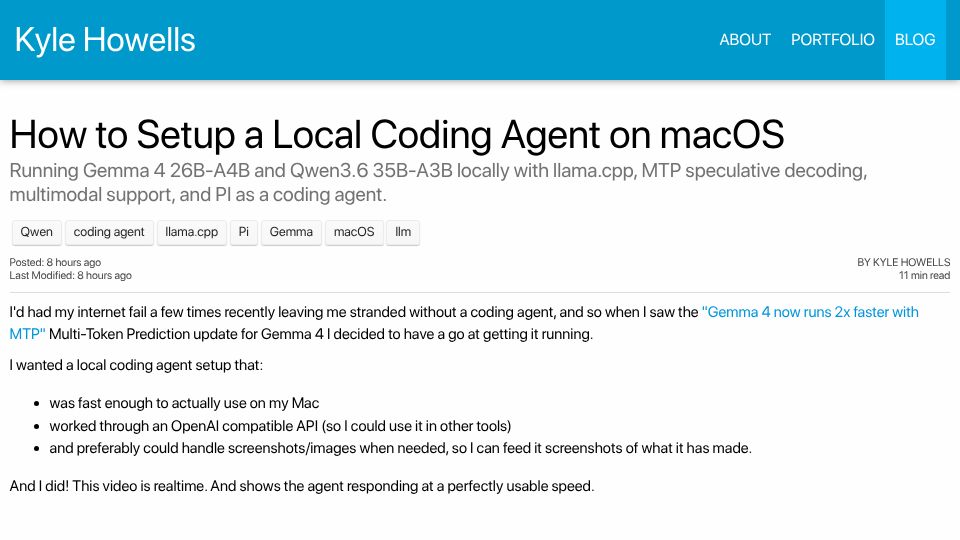
464 points by kkm | 114 comments
A blog tutorial on running Gemma 4 and Qwen3.6 locally on macOS with llama.cpp, MTP speculative decoding, and multimodal support as a coding agent.
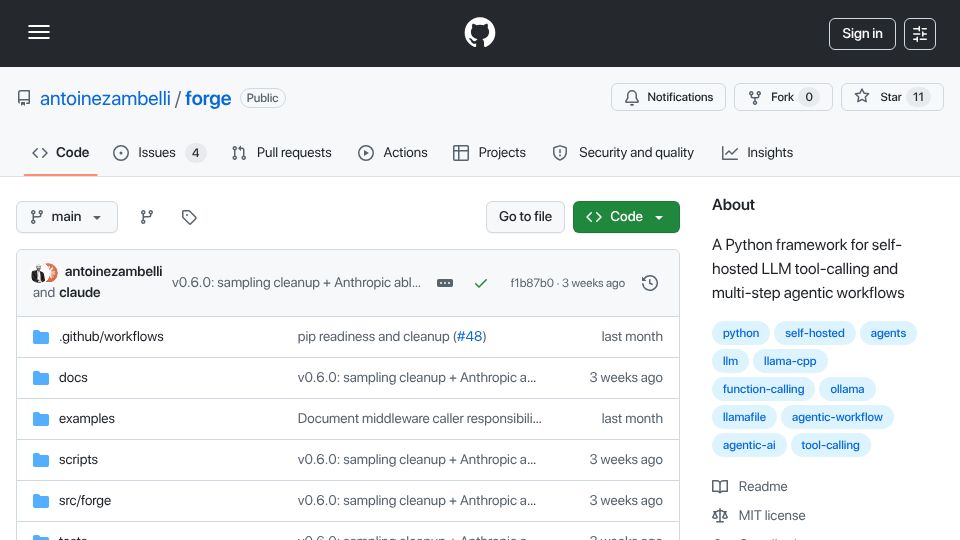
627 points by zambelli | 225 comments
GitHub repository for Forge, a Python framework adding guardrails to improve reliability of self-hosted LLM tool-calling and multi-step agentic workflows.
471 points by Zetaphor | 122 comments
Opinion blog post arguing against using Ollama, recounting its history as a llama.cpp wrapper, attribution disputes, cloud pivot, and recommending alternatives.
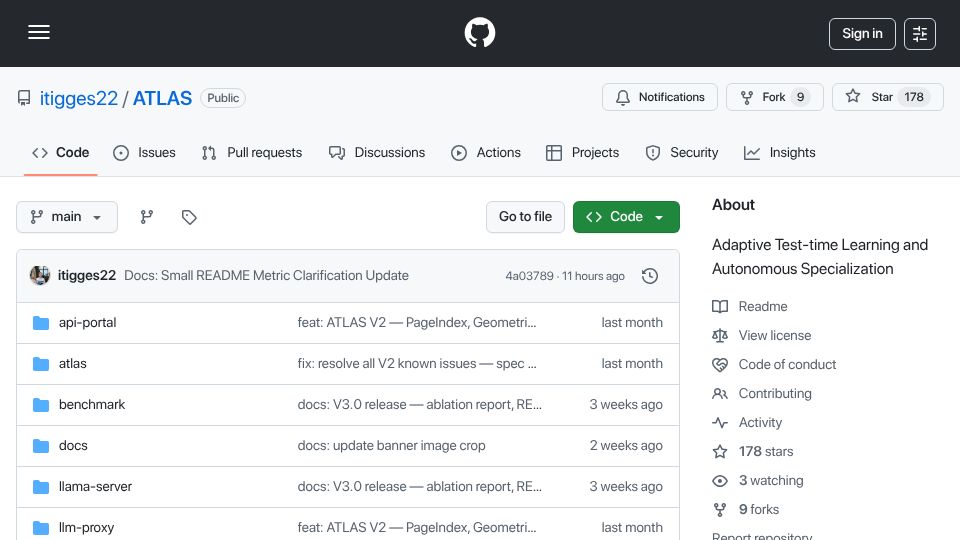
447 points by yogthos | 247 comments
GitHub repository for ATLAS (Adaptive Test-time Learning and Autonomous Specialization), a system for running local LLMs on consumer GPUs for coding tasks.
404 points by Vaslo | 128 comments
Home Assistant community forum post describing a user's setup of a fully local voice assistant using Home Assistant Assist and llama.cpp, replacing Google Home.
357 points by redm | 163 comments
GitHub repository for Microsoft's BitNet, the official inference framework for 1-bit large language models.
807 points by lairv | 211 comments
GitHub Discussions announcement by Georgi Gerganov that ggml.ai, the founding team of llama.cpp, is joining Hugging Face to support local AI.
475 points by redman25 | 104 comments
Documentation page in the llama.cpp GitHub repository describing multimodal (vision) input support via libmtmd and the tools that use it.
1061 points by felixrieseberg | 257 comments
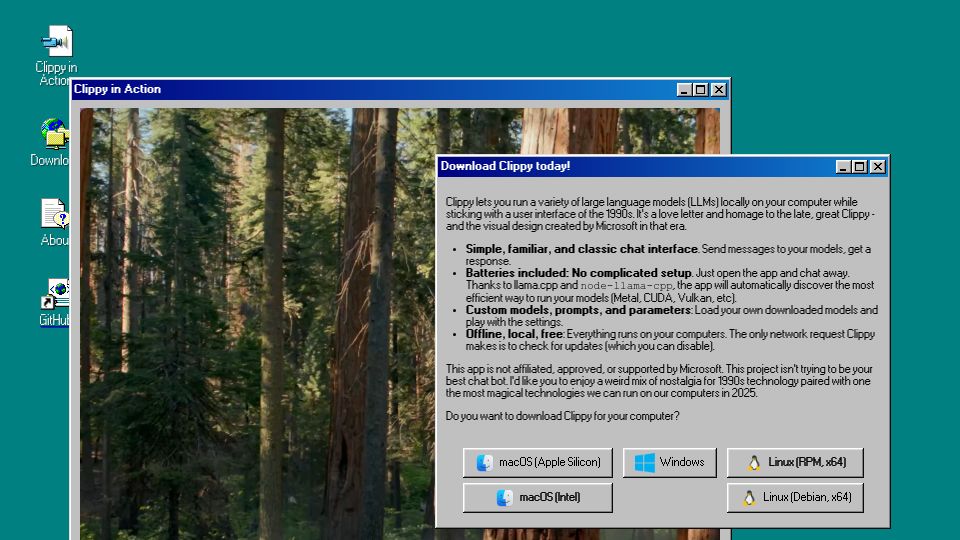
Download page for Clippy, a desktop app with a 1990s Windows-style interface for chatting with large language models running locally via llama.cpp.
926 points by k__ | 689 comments
Simon Willison blog post on a llama.cpp PR doubling WASM speed via SIMD, mostly written by DeepSeek R1, plus his own results using R1 for code.
496 points by kgwgk | 97 comments
GitHub repository for llama.vim, a Vim plugin that provides local LLM-assisted code and text completion using llama.cpp.
318 points by zarekr | 60 comments
A long blog guide on building and running llama.cpp to run large language models locally on various hardware, from scratch.
368 points by weinzierl | 72 comments
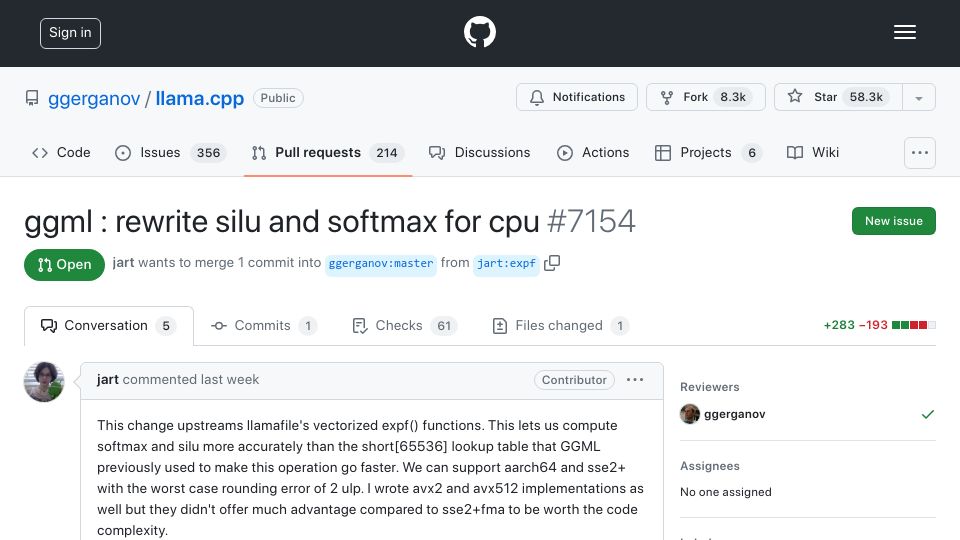
GitHub pull request to llama.cpp by jart that upstreams llamafile's vectorized expf() functions to compute SiLU and softmax faster and more accurately on CPU.
1286 points by lawrencechen | 413 comments
Justine Tunney's blog post describing 84 new matrix multiplication kernels that make llamafile prompt evaluation 30-500% faster on CPUs than llama.cpp.
496 points by xyc | 210 comments
Landing page for RecurseChat, a macOS app for chatting with local LLMs offline, with full-text search and ChatGPT history import.
341 points by samlhuillier | 83 comments
GitHub repository for Reor, an open-source desktop note-taking app that runs local LLMs and vector search for semantic linking and RAG Q&A over markdown notes.
972 points by tfinch | 253 comments
GitHub repository for Mozilla-Ocho's llamafile, a tool to distribute and run large language models as a single executable file.
428 points by plurby | 126 comments
GitHub directory for talk-llama, a whisper.cpp example that lets you talk to a LLaMA model locally using speech recognition and text-to-speech.
648 points by birriel | 210 comments
Blog post by Finbarr Timbers explaining the math of why llama.cpp can run LLaMA models locally on consumer hardware, focusing on memory bandwidth and compute limits.
573 points by bfirsh | 153 comments
Replicate blog post explaining how to run Meta's Llama 2 model locally on M1/M2 Macs, Windows, Linux, and phones without an internet connection.
379 points by davepeck | 95 comments
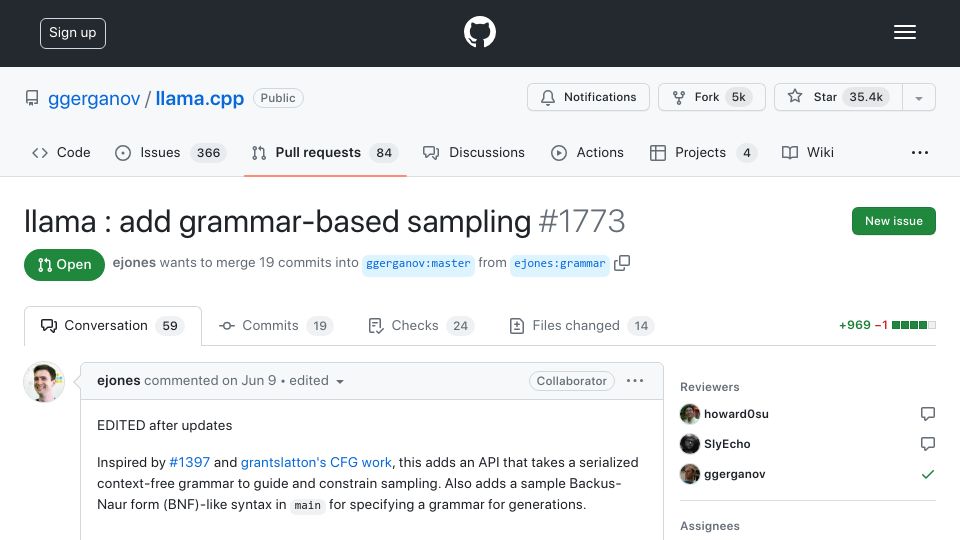
A GitHub pull request to llama.cpp adding an API for grammar-based sampling that constrains LLM output with a BNF-like context-free grammar.
640 points by gzer0 | 265 comments
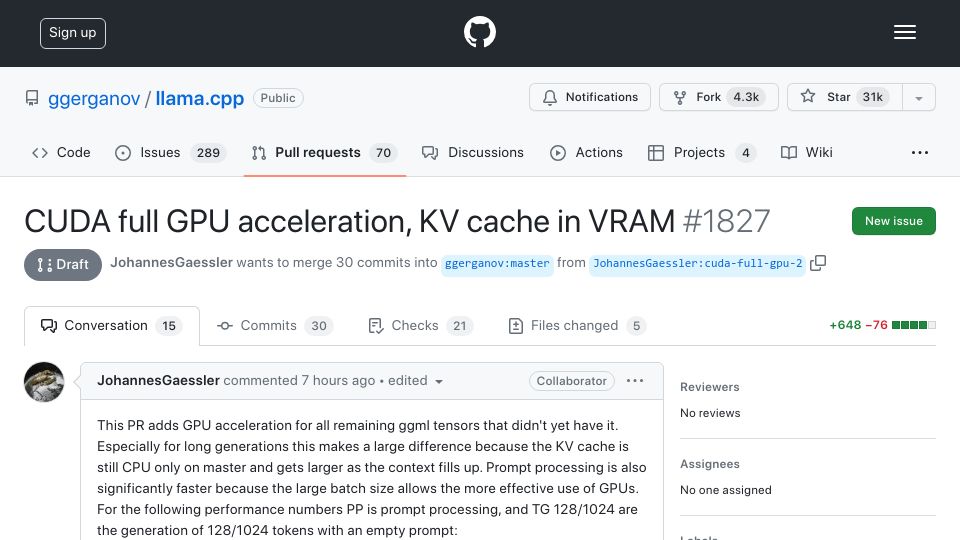
A draft GitHub pull request to llama.cpp adding full CUDA GPU acceleration for all ggml tensors, including storing the KV cache in VRAM.
817 points by georgehill | 206 comments
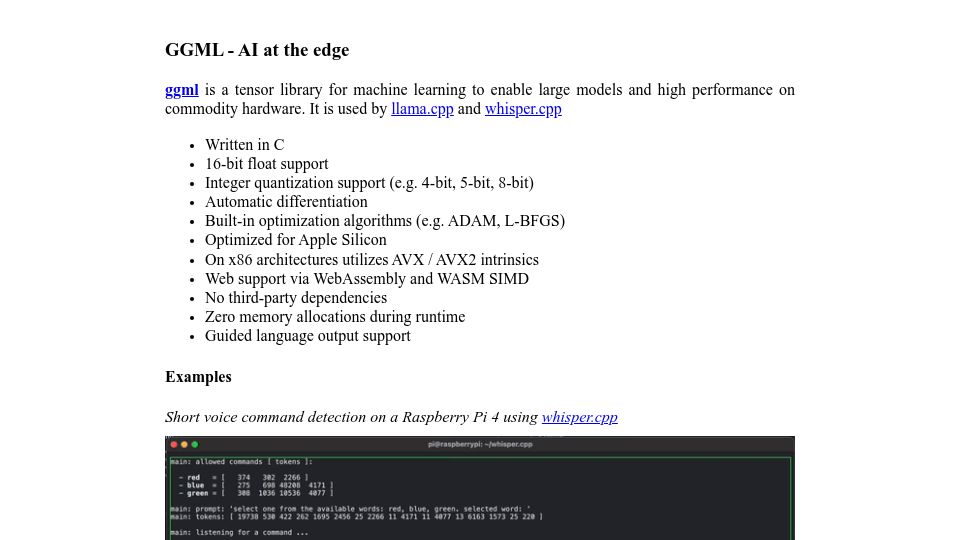
Homepage for ggml, a C tensor library for running machine learning models on commodity hardware, used by llama.cpp and whisper.cpp.
564 points by rain1 | 233 comments
A GitHub Gist with instructions for running Meta's Llama 13B model on a 6GB GPU using llama.cpp's CUDA/cuBLAS layer offloading.
1182 points by msoad | 356 comments
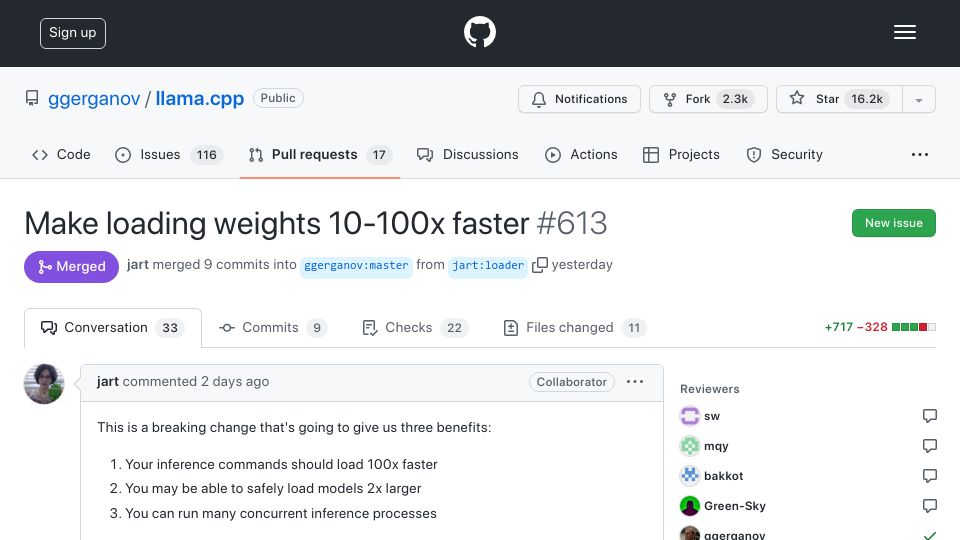
GitHub pull request #613 in llama.cpp by jart, merged, which uses mmap to make loading model weights 10-100x faster and reduce RAM usage.