Voxtral 3(mistral.ai)
747 points by ilreb | 200 comments
Mistral AI announcement page for Voxtral 3, its speech and audio AI model.
18 stories tagged speech-recognition, newest first.
747 points by ilreb | 200 comments
Mistral AI announcement page for Voxtral 3, its speech and audio AI model.
205 points by vunderba | 108 comments
Interactive web game where you say or type numbers as randomly as you can while the page predicts each next number before you reveal it.
913 points by gmays | 176 comments
Cactus blog post announcing Whistle, a 16.9 MB open speech-to-text model for seven languages that runs on CPU alongside their Needle model.
544 points by petewarden | 79 comments
GitHub directory for Moonshine's micro build, offering speech recognition and neural text-to-speech small enough to run on microcontrollers like the RP2350.
529 points by get-inscribe | 211 comments
Blog post from Inscribe benchmarking Apple's new SpeechAnalyzer API against its predecessor and OpenAI Whisper on 5,559 test utterances, with transcripts released.
346 points by tosh | 169 comments
GitHub repository for Microsoft's VibeVoice, an open-source frontier voice AI project covering TTS and ASR models.
374 points by Curiositry | 53 comments
GitHub repository for a Rust implementation of Mistral's Voxtral Mini 4B Realtime speech model that can run in the browser, with Q4/Q8 quantization.
961 points by meetpateltech | 232 comments
Mistral AI announcement page for Voxtral Transcribe 2, its speech-to-text transcription model.
426 points by simedw | 128 comments
Blog post describing a 9M-parameter Conformer-CTC model trained on ~300 hours of speech that grades Mandarin pronunciation and tones in the browser.
954 points by rilawa | 307 comments
FFmpeg commit adding a libavfilter audio filter that runs speech transcription with the Whisper model, including documentation and examples.
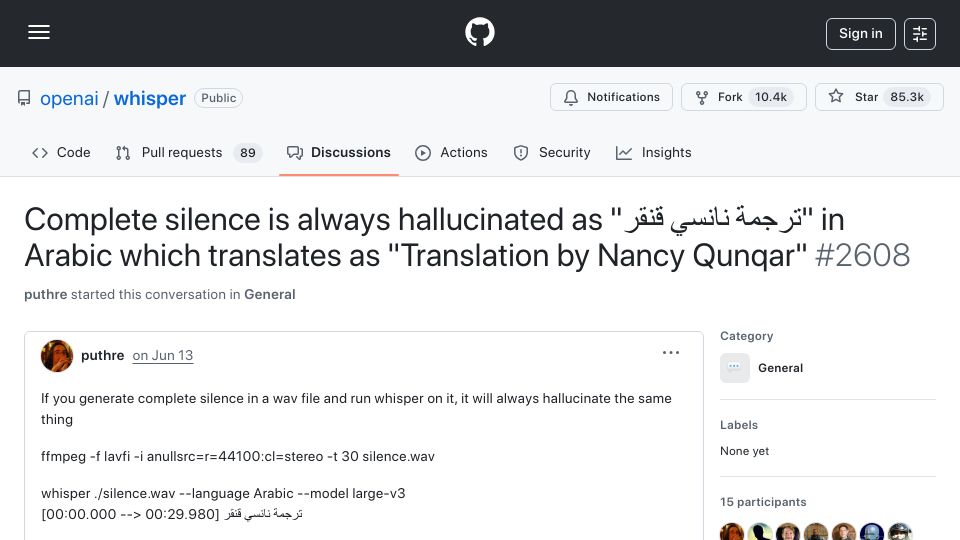
504 points by edent | 283 comments
GitHub discussion reporting that OpenAI Whisper transcribes complete silence in Arabic as "Translation by Nancy Qunqar", with ffmpeg steps to reproduce.
480 points by koljab | 202 comments
GitHub repository for RealtimeVoiceChat, an open-source project for natural spoken conversation with an AI at low latency.
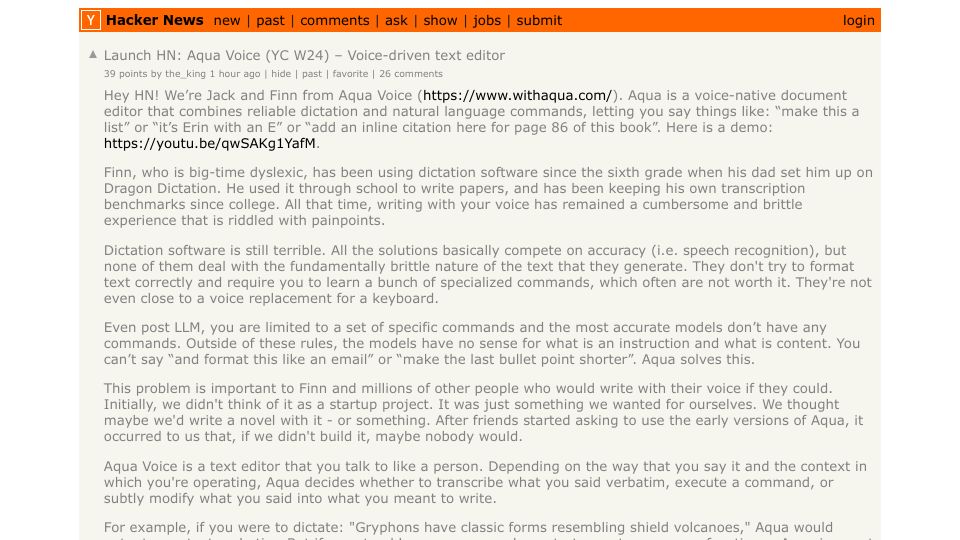
687 points by the_king | 230 comments
Launch HN post introducing Aqua Voice (YC W24), a voice-native document editor combining dictation with natural-language editing commands via LLMs.
428 points by plurby | 126 comments
GitHub directory for talk-llama, a whisper.cpp example that lets you talk to a LLaMA model locally using speech recognition and text-to-speech.
615 points by crakenzak | 193 comments
GitHub directory in Meta's fairseq repository containing code and models for Massive Multilingual Speech (MMS), covering ASR, TTS, and language ID for 1000+ languages.
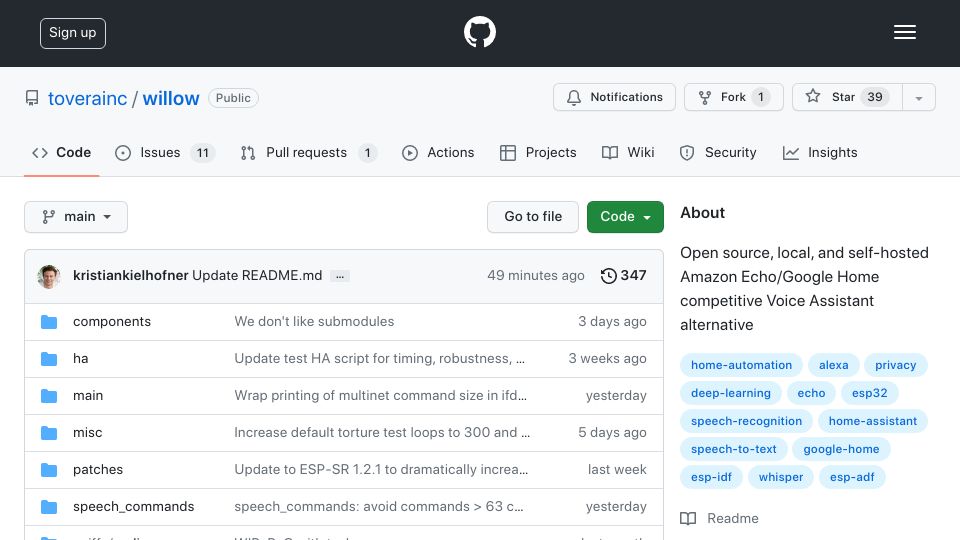
492 points by kkielhofner | 121 comments
GitHub repository for Willow, an open-source, self-hosted voice assistant firmware for Espressif ESP BOX hardware that integrates with Home Assistant.
487 points by yamrzou | 181 comments
Google Research project page for the Universal Speech Model, a 2B-parameter ASR model family trained on 12 million hours of speech covering 300+ languages.
322 points by KianHooshmand | 111 comments
Launch HN post for Vocode, a YC W23 open source Python library for building real-time voice conversation apps on top of LLMs.