First screen, captured .
Looks similar
Make Ubuntu packages 90% faster by rebuilding them(gist.github.com)
513 points by jeffbee | 323 comments
A GitHub Gist explaining how rebuilding Ubuntu's jq package from the same source with different build options yields about 90% better performance.
Obfuscating Lua (2019)(gist.github.com)
39 points by shakna | 10 comments
macOS Internals(gist.github.com)
698 points by JoelMcCracken | 112 comments
A GitHub Gist collecting links to John Siracusa's Mac OS X reviews, tracing macOS internals from the prerelease era to Swift.
Related stories
Llamafile lets you distribute and run LLMs with a single file(github.com)
972 points by tfinch | 253 comments
GitHub repository for Mozilla-Ocho's llamafile, a tool to distribute and run large language models as a single executable file.
Llama2.c: Inference llama 2 in one file of pure C(github.com)
659 points by anjneymidha | 158 comments
GitHub repository by Andrej Karpathy for llama2.c, a minimal implementation for running Llama 2 model inference in a single file of pure C.
Run Kimi K3 using 29 GB of RAM at 0.50 tok/s(github.com)
318 points by marcobambini | 152 comments
GitHub repository for waste, a dependency-free embeddable C inference engine that runs the 2.78-trillion-parameter Kimi K3 model by streaming weights from NVMe.
Quickemu: Quickly run optimised Windows, macOS and Linux virtual machines(github.com)
411 points by overbytecode | 128 comments
GitHub repository for Quickemu, a tool that quickly creates and runs optimised Windows, macOS and Linux desktop virtual machines using QEMU.
Llama 3 implemented in pure NumPy(docs.likejazz.com)
404 points by orixilus | 48 comments
GitHub repository llama3.np, a pure NumPy implementation of the Llama 3 language model for inference.
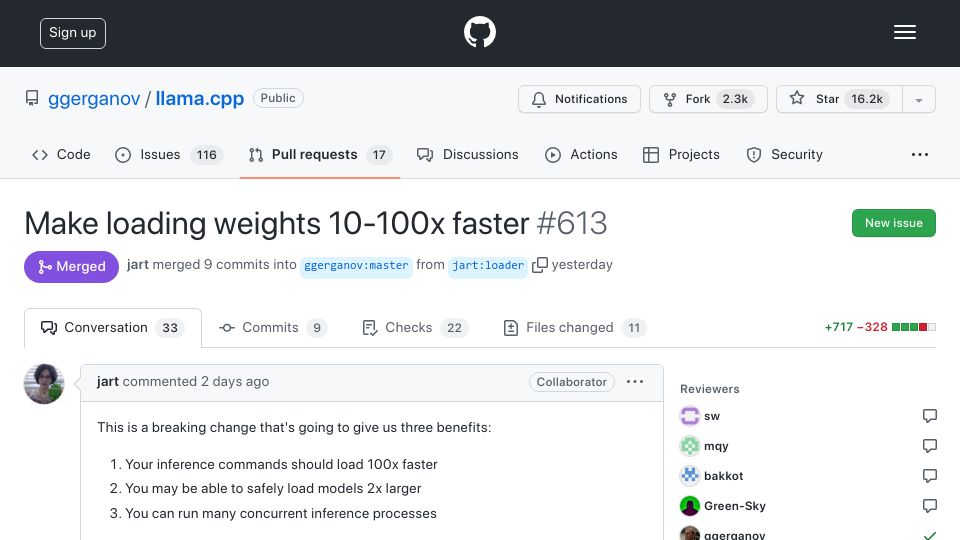
Llama.cpp 30B runs with only 6GB of RAM now(github.com)
1182 points by msoad | 356 comments
GitHub pull request #613 in llama.cpp by jart, merged, which uses mmap to make loading model weights 10-100x faster and reduce RAM usage.