Llama.cpp 30B runs with only 6GB of RAM now(github.com)
1182 points by msoad | 356 comments
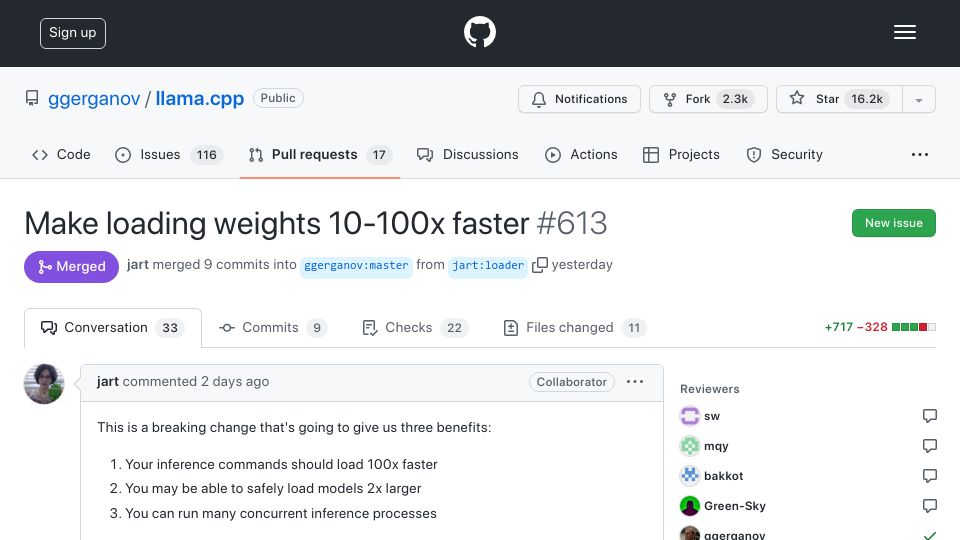
GitHub pull request #613 in llama.cpp by jart, merged, which uses mmap to make loading model weights 10-100x faster and reduce RAM usage.
1 story tagged mmap, newest first.
1182 points by msoad | 356 comments
GitHub pull request #613 in llama.cpp by jart, merged, which uses mmap to make loading model weights 10-100x faster and reduce RAM usage.