LLaMA now goes faster on CPUs(justine.lol)
1286 points by lawrencechen | 413 comments
Justine Tunney's blog post describing 84 new matrix multiplication kernels that make llamafile prompt evaluation 30-500% faster on CPUs than llama.cpp.
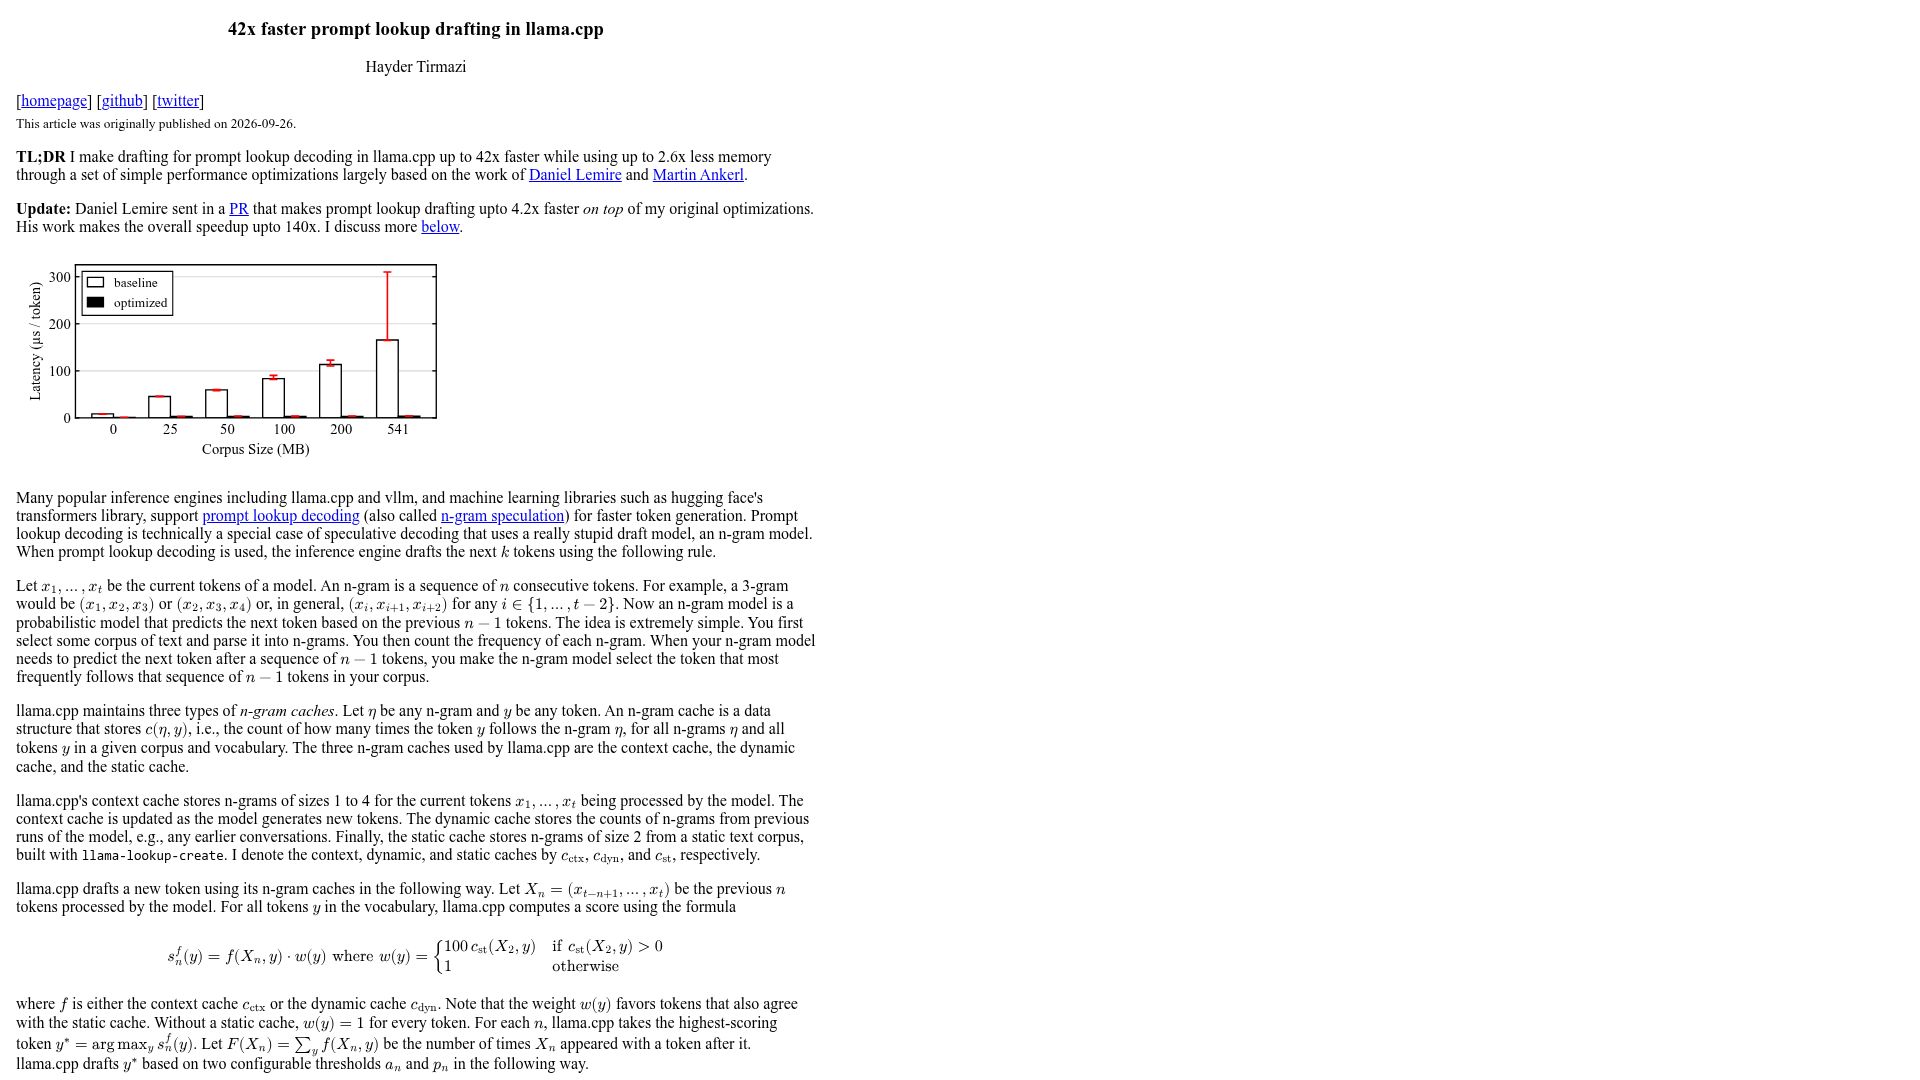
First screen, captured .
1286 points by lawrencechen | 413 comments
Justine Tunney's blog post describing 84 new matrix multiplication kernels that make llamafile prompt evaluation 30-500% faster on CPUs than llama.cpp.
648 points by birriel | 210 comments
Blog post by Finbarr Timbers explaining the math of why llama.cpp can run LLaMA models locally on consumer hardware, focusing on memory bandwidth and compute limits.
57 points by shellpipe | 10 comments
Blog post by Fernando Simões examining page table memory consumption, prompted by Linus Torvalds' 2003 argument for multi-level over hashed page tables.
343 points by saikatsg | 242 comments
Blog post by Ivan Turkovic arguing that AI tools make producing code easier while making the broader job of being a software engineer harder.
325 points by themanmaran | 59 comments
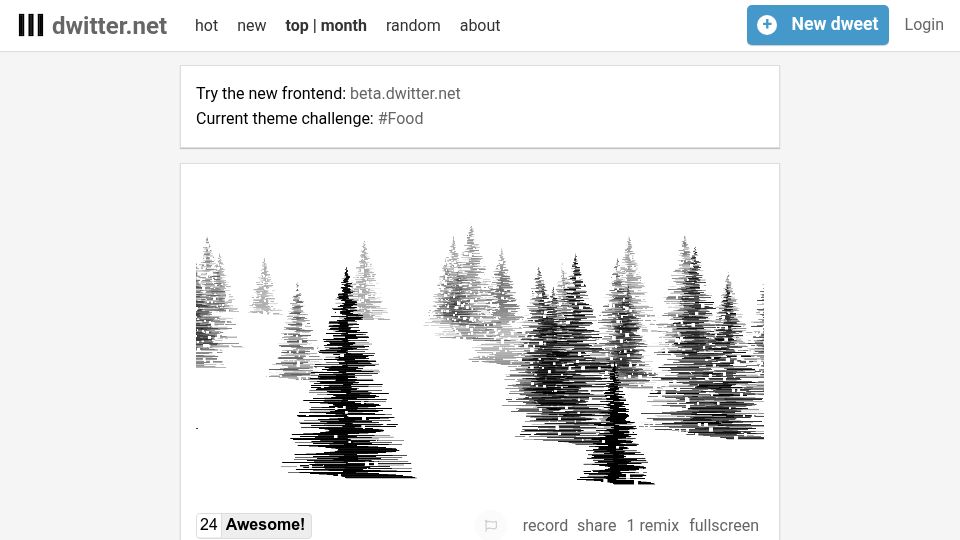
Dwitter, a community site for sharing and remixing JavaScript canvas demos written in 140 characters or less.
546 points by fagnerbrack | 213 comments
A blog post arguing that many so-called abstractions in codebases are merely layers of indirection that add complexity and hurt performance without real value.
464 points by kkm | 114 comments
A blog tutorial on running Gemma 4 and Qwen3.6 locally on macOS with llama.cpp, MTP speculative decoding, and multimodal support as a coding agent.
244 points by dom96 | 179 comments
Blog post by Dominik Picheta introducing KillSwitch, a programming language he designed so that large language models cannot use it.
399 points by MinimalAction | 164 comments
A Dynomight blog essay critiquing NumPy's design, arguing its array broadcasting and indexing make complex computations confusing.