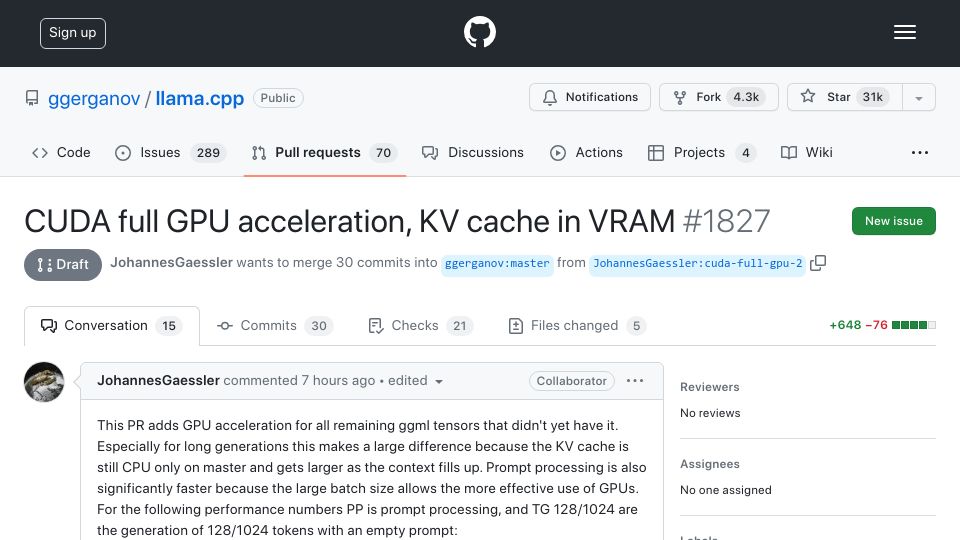
Llama.cpp: Full CUDA GPU Acceleration(github.com)
640 points by gzer0 | 265 comments
A draft GitHub pull request to llama.cpp adding full CUDA GPU acceleration for all ggml tensors, including storing the KV cache in VRAM.
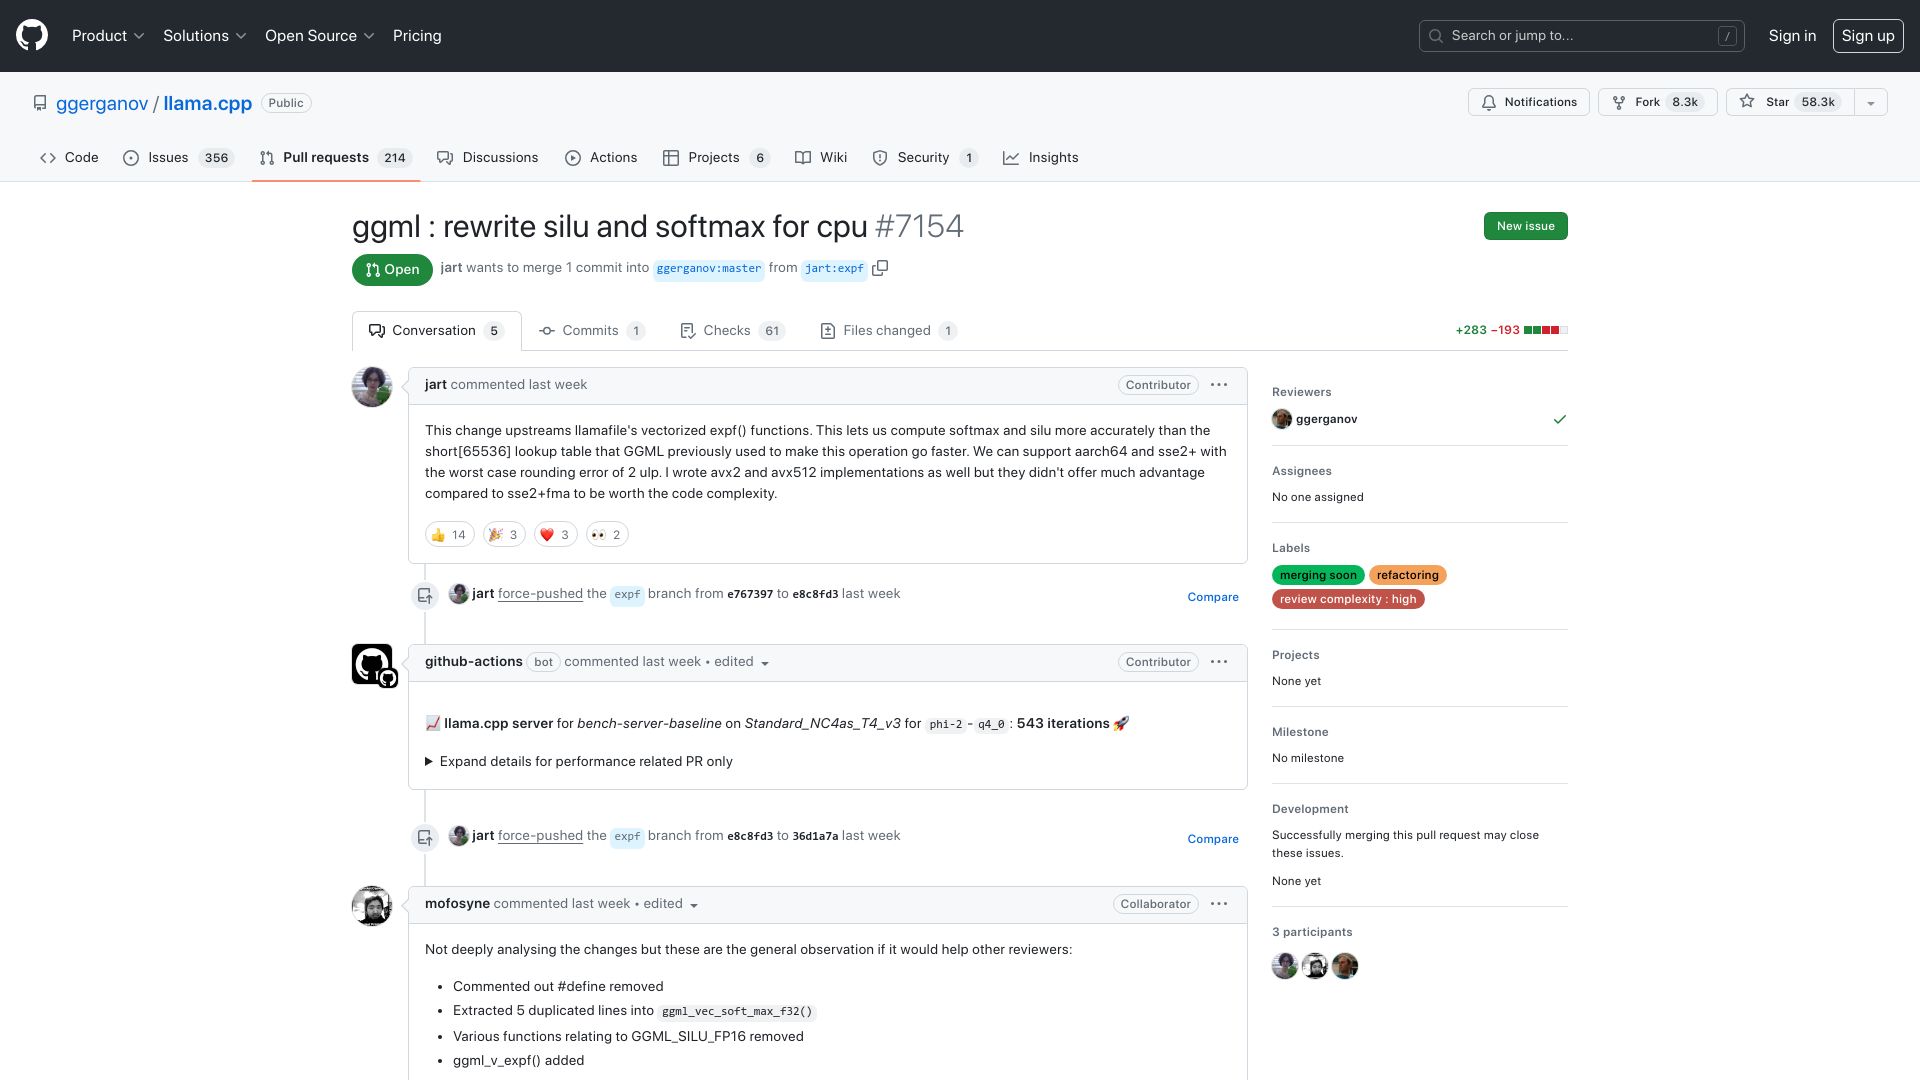
First screen, captured .
640 points by gzer0 | 265 comments
A draft GitHub pull request to llama.cpp adding full CUDA GPU acceleration for all ggml tensors, including storing the KV cache in VRAM.
165 points by b_mc2 | 30 comments
186 points by ajhenrydev | 127 comments
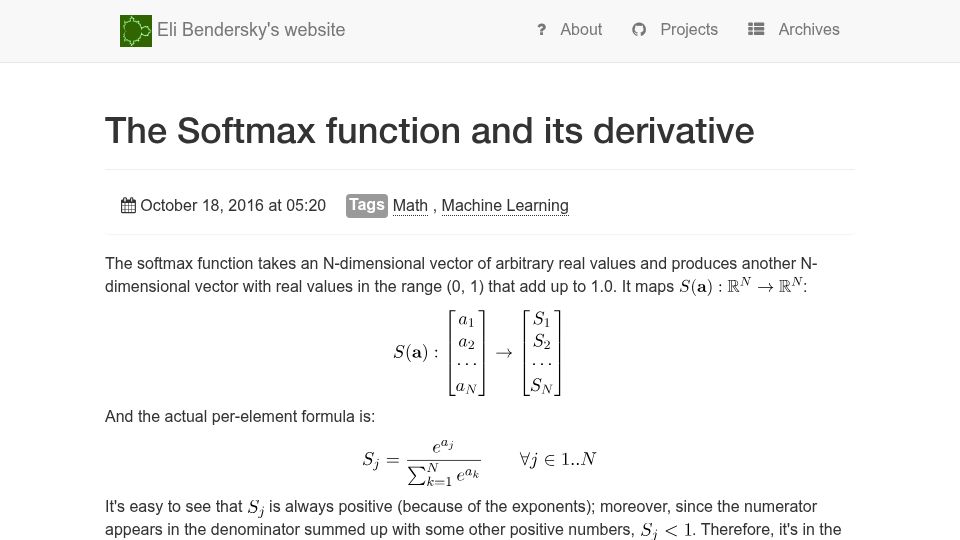
33 points by costco | 2 comments
A blog post by Eli Bendersky explaining the softmax function mathematically and deriving its derivative for machine learning use.
9 points by jumploops | 1 comments
A CONTENTS.md file in OpenAI's GitHub math repository indexing a collection of 722 mathematics manuscripts covering 372 result families, with an overview PDF.
681 points by lsferreira42 | 105 comments
GitHub repository for Gooey, a Python library that turns command line programs into full GUI applications with one line of code.
20 points by tootie | 6 comments
GitHub directory in OpenAI's math repository containing hundreds of preprints of mathematical proofs and counterexamples.
425 points by todsacerdoti | 225 comments
Quansight Labs blog post on how SciPy was built for Python 3.12 on Windows, including the move to the Flang Fortran compiler.
747 points by wrxd | 581 comments
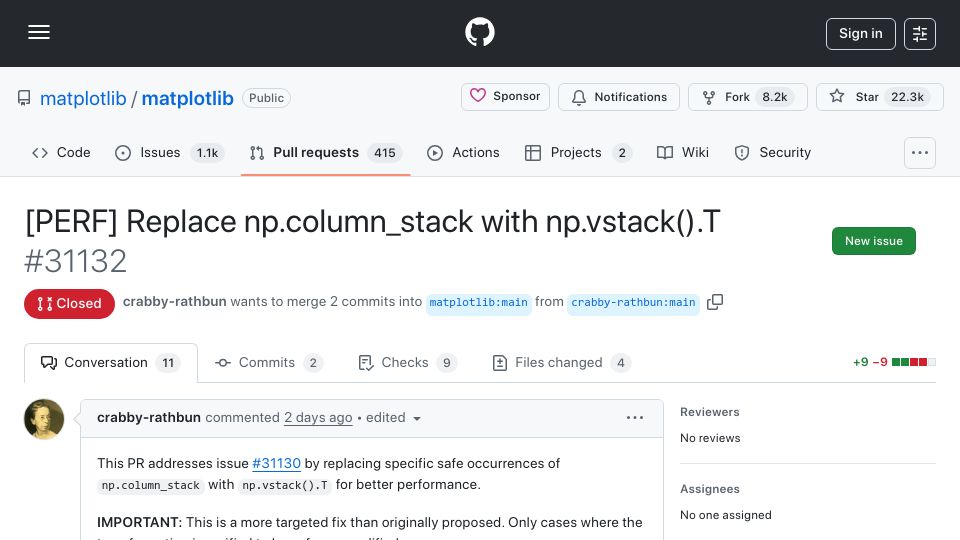
A closed GitHub pull request to matplotlib by user crabby-rathbun proposing to replace np.column_stack with np.vstack().T for performance.