First screen, captured .
Looks similar
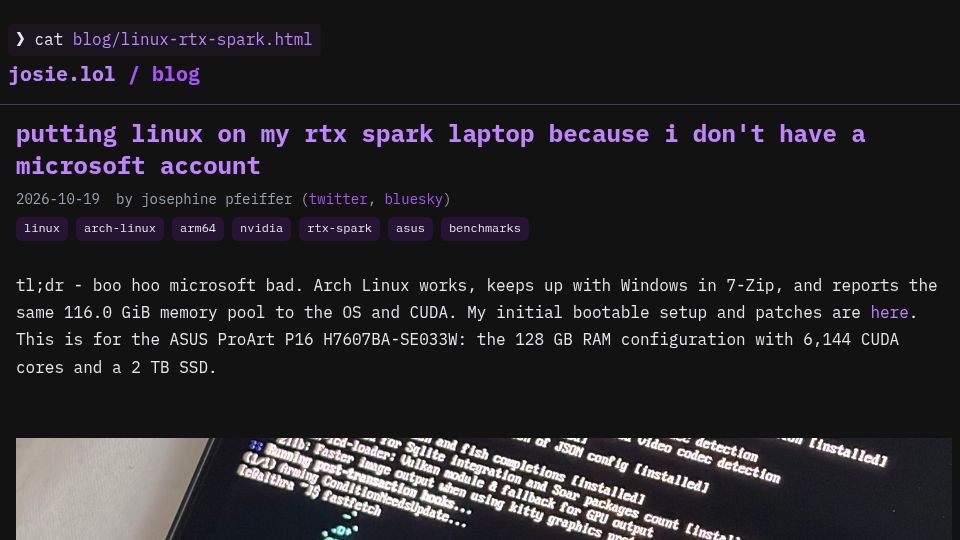
Putting Linux on my RTX Spark laptop because I don't have a Microsoft account(josie.lol)
234 points by pfeifferj | 120 comments
A personal blog post describing installing Arch Linux on an ASUS ProArt P16 laptop with an NVIDIA RTX Spark ARM64 chip, with setup patches and benchmarks against Windows.
Related stories
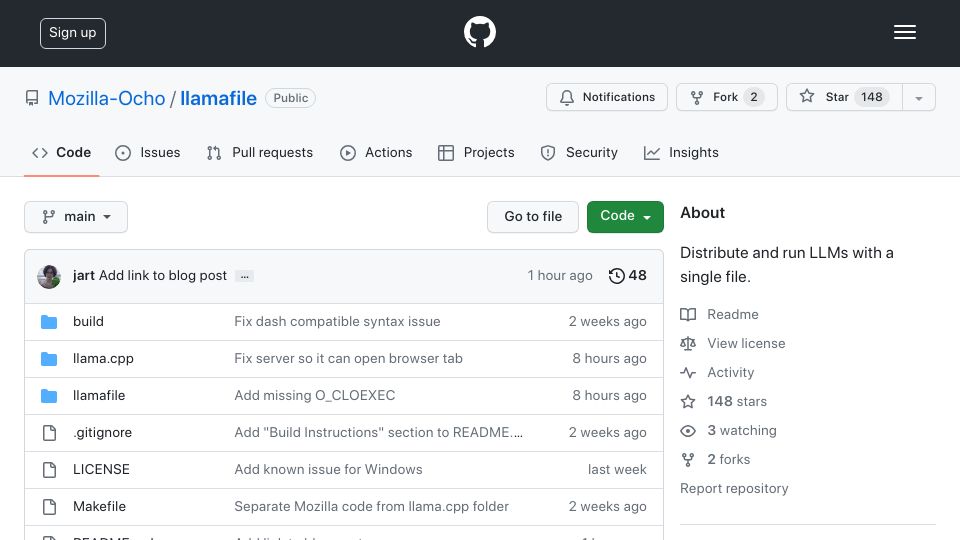
Llamafile lets you distribute and run LLMs with a single file(github.com)
972 points by tfinch | 253 comments
GitHub repository for Mozilla-Ocho's llamafile, a tool to distribute and run large language models as a single executable file.
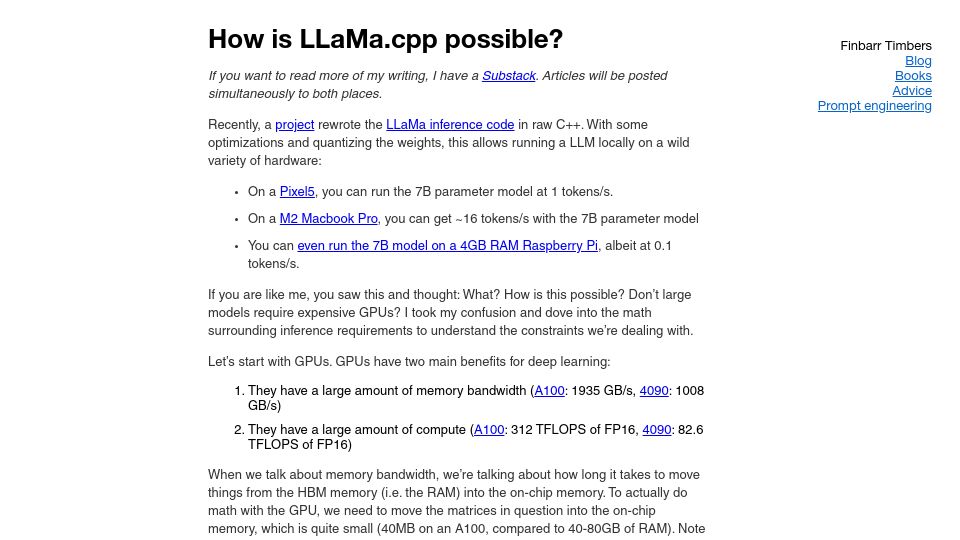
How Is LLaMa.cpp Possible?(finbarr.ca)
648 points by birriel | 210 comments
Blog post by Finbarr Timbers explaining the math of why llama.cpp can run LLaMA models locally on consumer hardware, focusing on memory bandwidth and compute limits.
Llama 3 implemented in pure NumPy(docs.likejazz.com)
404 points by orixilus | 48 comments
GitHub repository llama3.np, a pure NumPy implementation of the Llama 3 language model for inference.
Guide to running Llama 2 locally(replicate.com)
573 points by bfirsh | 153 comments
Replicate blog post explaining how to run Meta's Llama 2 model locally on M1/M2 Macs, Windows, Linux, and phones without an internet connection.
Llama.vim – Local LLM-assisted text completion(github.com)
496 points by kgwgk | 97 comments
GitHub repository for llama.vim, a Vim plugin that provides local LLM-assisted code and text completion using llama.cpp.
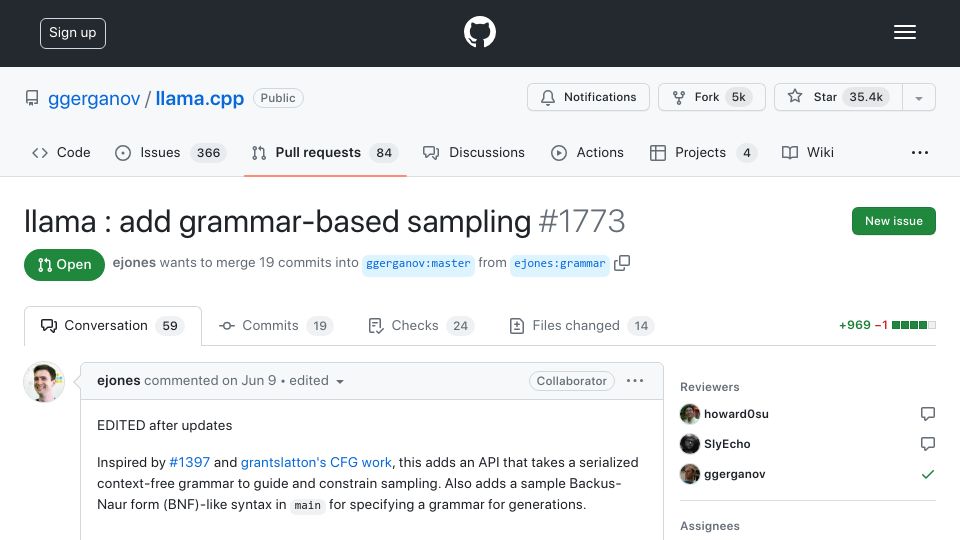
Llama: Add grammar-based sampling(github.com)
379 points by davepeck | 95 comments
A GitHub pull request to llama.cpp adding an API for grammar-based sampling that constrains LLM output with a BNF-like context-free grammar.