Show HN: Which Mac runs which LLM, and how fast(macyou.co)
5 points by bagdaerdev | 2 comments
A web calculator that estimates which large language models can run on various Mac models and how fast they generate tokens.
8 stories tagged local-inference, newest first.
5 points by bagdaerdev | 2 comments
A web calculator that estimates which large language models can run on various Mac models and how fast they generate tokens.
580 points by Ardakilic | 139 comments
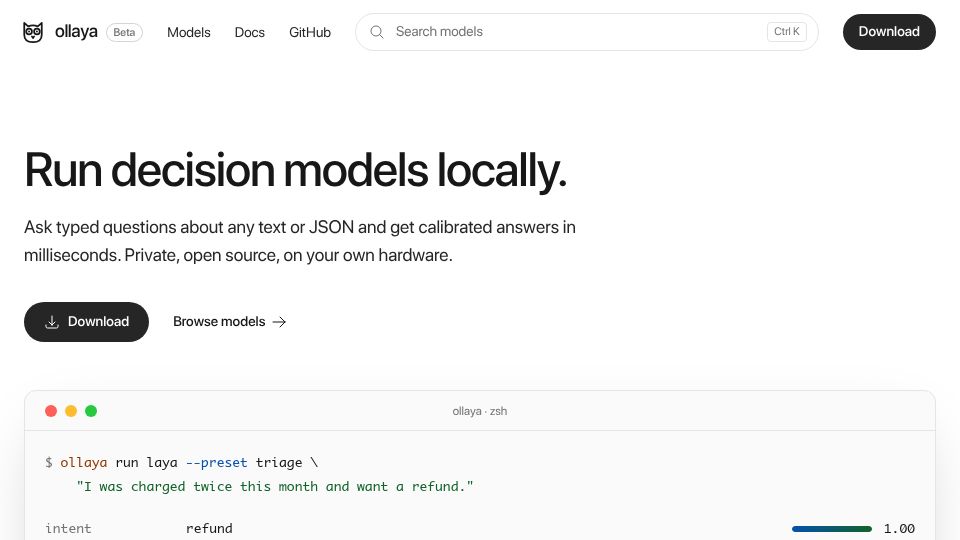
Landing page for Ollaya, an open-source beta tool for running decision models locally to get calibrated typed answers about text or JSON.
689 points by anemll | 314 comments
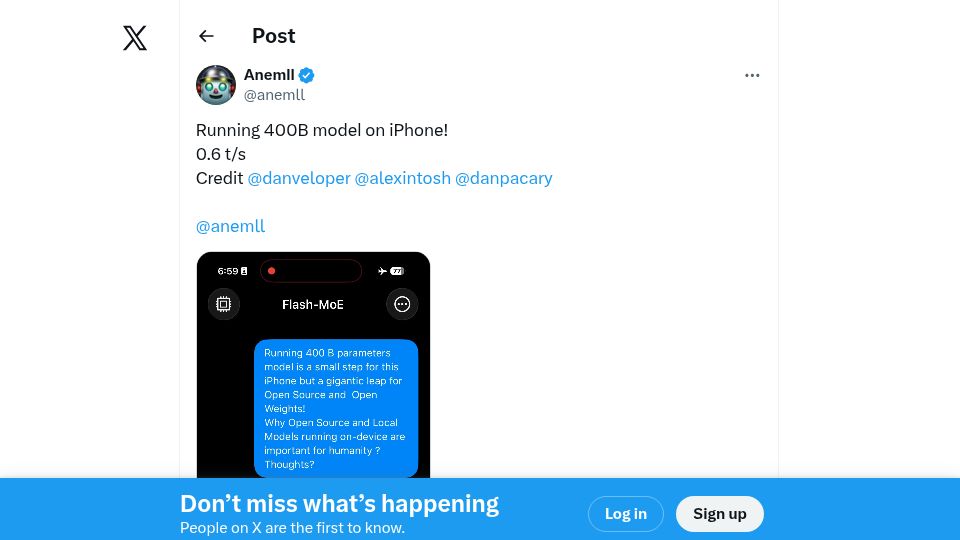
An X post from @anemll showing a 400B-parameter MoE language model running locally on an iPhone at about 0.6 tokens per second via a Flash-MoE app.
571 points by emrah | 259 comments
Google Developers Blog post announcing Gemma 3 models trained with quantization-aware training so they can run on consumer GPUs.
701 points by noch | 308 comments
Unsloth blog post describing dynamic 1.58-bit quantization of DeepSeek-R1 671B, shrinking it to 131GB so users can run it locally.
318 points by zarekr | 60 comments
A long blog guide on building and running llama.cpp to run large language models locally on various hardware, from scratch.
377 points by dataminer | 78 comments
GitHub repository for PowerInfer, an SJTU-IPADS engine for high-speed large language model inference on PCs with consumer-grade GPUs.
972 points by tfinch | 253 comments
GitHub repository for Mozilla-Ocho's llamafile, a tool to distribute and run large language models as a single executable file.