Qwen3.8-27B on the iPhone 18 Neural Engine at 15–70 tok/s (1.5 bpw)(twitter.com)
18 points by anemll | 3 comments
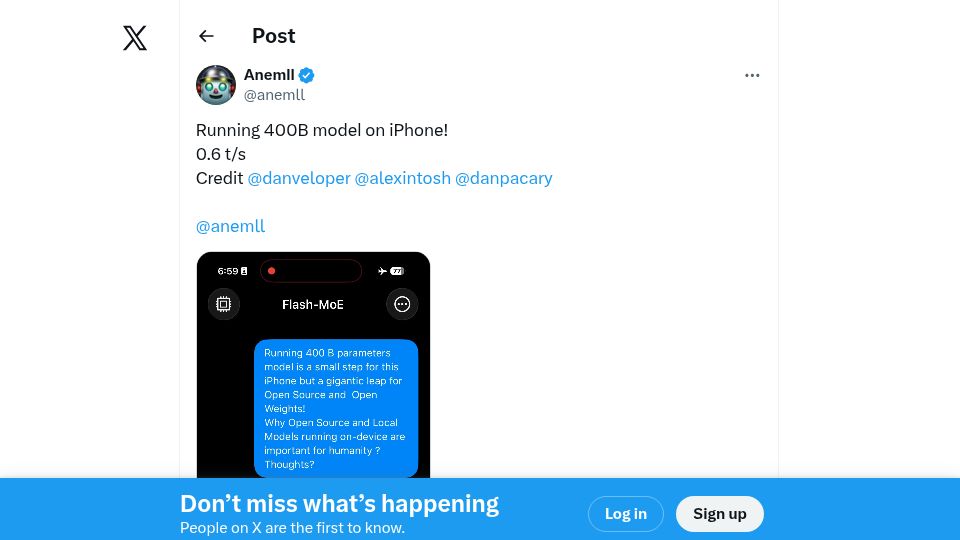
A tweet from ANEMLL reporting a 27B-parameter Qwen model running on the iPhone 18 Neural Engine at 15–70 tokens per second using 1.5-bit quantization.