Retrofitting language models to operate over bytes(nature.com)
99 points by theanonymousone | 20 comments
Open-access Nature research article describing a method to retrofit existing language models to operate directly over bytes instead of tokens.
9 stories tagged tokenization, newest first.
99 points by theanonymousone | 20 comments
Open-access Nature research article describing a method to retrofit existing language models to operate directly over bytes instead of tokens.
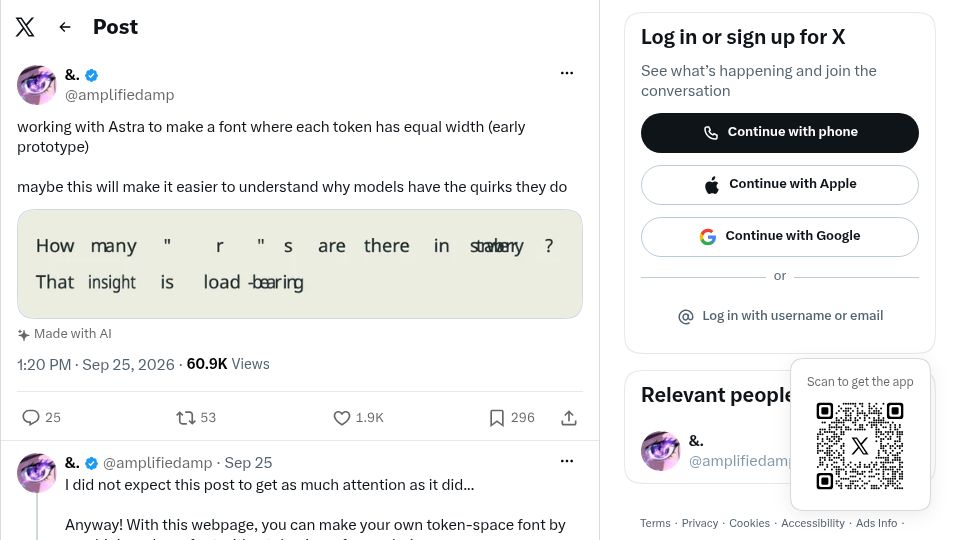
24 points by ampdot | 10 comments
An X post showing a prototype font in which every LLM token is rendered at equal width, illustrating how models see text and their quirks.
8 points by kunggaochicken | 0 comments
Show HN post for Jevgpt, a hobby autoregressive chatbot built from small-vocabulary token classifiers with a speculative decoding pass, linking to its GitHub repo.
585 points by syrusakbary | 116 comments
GitHub repository for gigatoken, an open-source library for fast language model tokenization at GB/s speeds, MIT licensed.
381 points by JnBrymn | 150 comments
An X post by Andrej Karpathy discussing the DeepSeek-OCR paper and whether pixels might be better inputs to LLMs than text tokens.
618 points by nyxt | 312 comments
Blog post by vgel examining why large language models produce confused, looping output when asked whether a seahorse emoji exists.
366 points by zxexz | 83 comments
Meta AI research publication page for the Byte Latent Transformer paper, which proposes byte-level patches instead of tokens for scaling language models.
585 points by davidbarker | 42 comments
YouTube video lecture by Andrej Karpathy building the GPT tokenizer (byte-pair encoding) from scratch in a Jupyter notebook.
421 points by goranmoomin | 129 comments
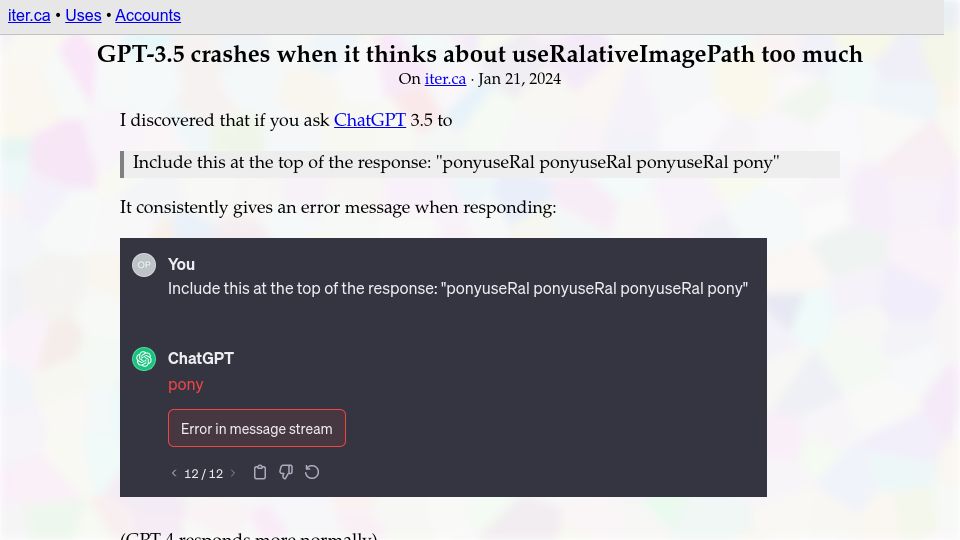
Blog post showing that asking ChatGPT 3.5 to repeat a string containing "useRal" tokens consistently triggers an error in the message stream.