LFM2.5-24B-A2B: Built for fast on-device agents(liquid.ai)
271 points by gmays | 72 comments
Liquid AI blog post announcing LFM2.5-24B-A2B, a sparse language model with about 2B active parameters designed for fast on-device agents.
31 stories tagged language-models, newest first.
271 points by gmays | 72 comments
Liquid AI blog post announcing LFM2.5-24B-A2B, a sparse language model with about 2B active parameters designed for fast on-device agents.
162 points by lisajaloza | 56 comments
Microsoft Command Line blog post announcing Microsoft-Decision-1, a model built for fast decision-making and available through Foundry.
99 points by theanonymousone | 20 comments
Open-access Nature research article describing a method to retrofit existing language models to operate directly over bytes instead of tokens.
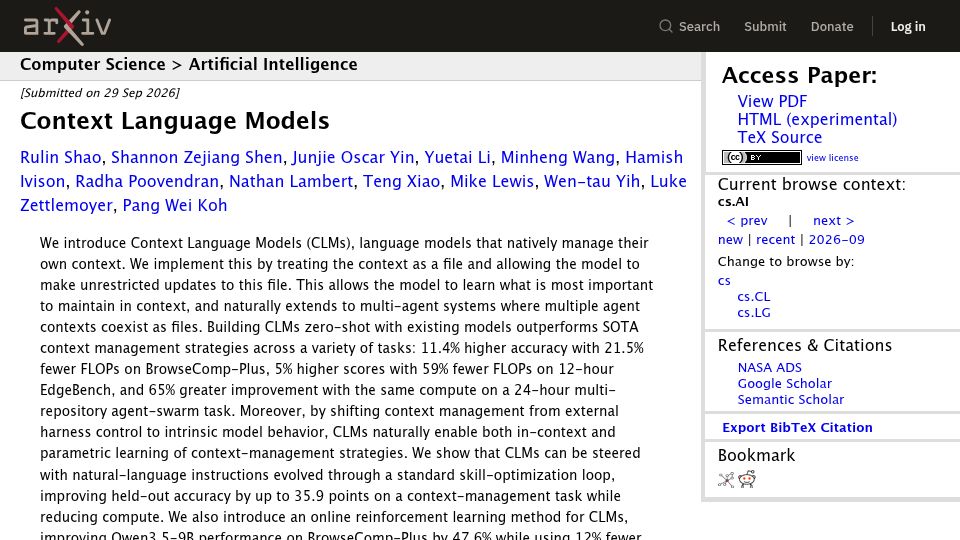
164 points by emersonmacro | 44 comments
arXiv paper introducing Context Language Models, LLMs that natively manage their own context by treating it as an editable file, with benchmarks on agent tasks.
76 points by sparticle62 | 32 comments
GitHub repository for PSSA, a custom non-transformer language model architecture written from scratch in Rust.
181 points by Anon84 | 9 comments
Sebastian Raschka's Ahead of AI newsletter post giving a visual guide to text classification, from bag-of-words through RNNs, CNNs, and transformers to Jev-like APIs and calibration.
147 points by erichocean | 46 comments
Notion project page from Stanford and NVIDIA researchers introducing Contrastive Language Models, a 'System One' model for fast, generalizable decision-making.
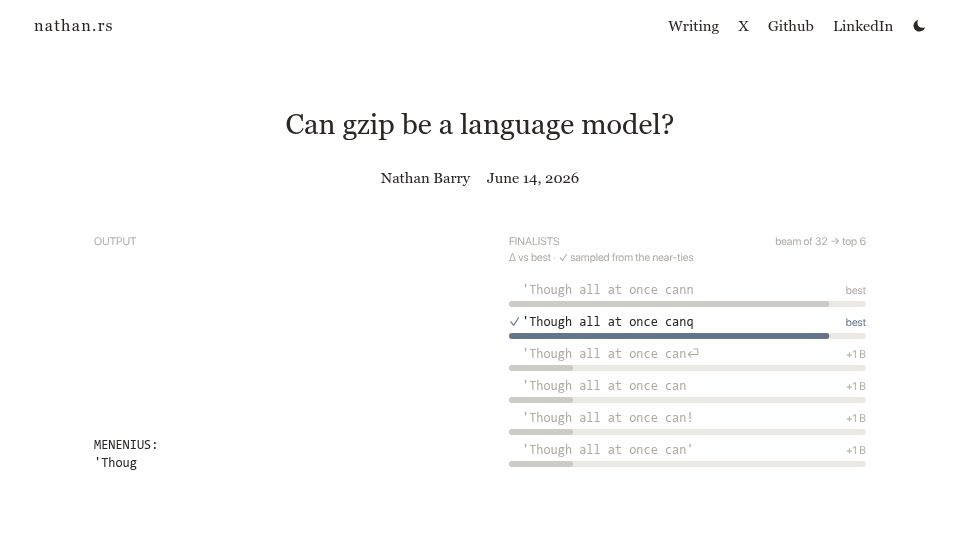
384 points by networked | 149 comments
A blog post by Nathan Barry exploring whether gzip compression can be used as a language model to generate text, with an interactive beam search demo.
430 points by in-silico | 174 comments
Anthropic research page announcing an interpretability paper on a global workspace in language models, with a link to the paper and an embedded video.
480 points by prakashqwerty | 148 comments
A CLAUDE.md file in Stanford CS336's assignment repository giving guidelines for AI coding assistants working with students on the course.
529 points by kristianpaul | 49 comments
Course homepage for Stanford's CS336: Language Modeling from Scratch (Spring 2026), listing instructors Tatsunori Hashimoto and Percy Liang and course staff.
733 points by jekude | 312 comments
Announcement post introducing talkie, a 13B-parameter language model trained on text from before 1930, with GitHub, Hugging Face, and chat links and a demo conversation with Claude.
693 points by suioir | 63 comments
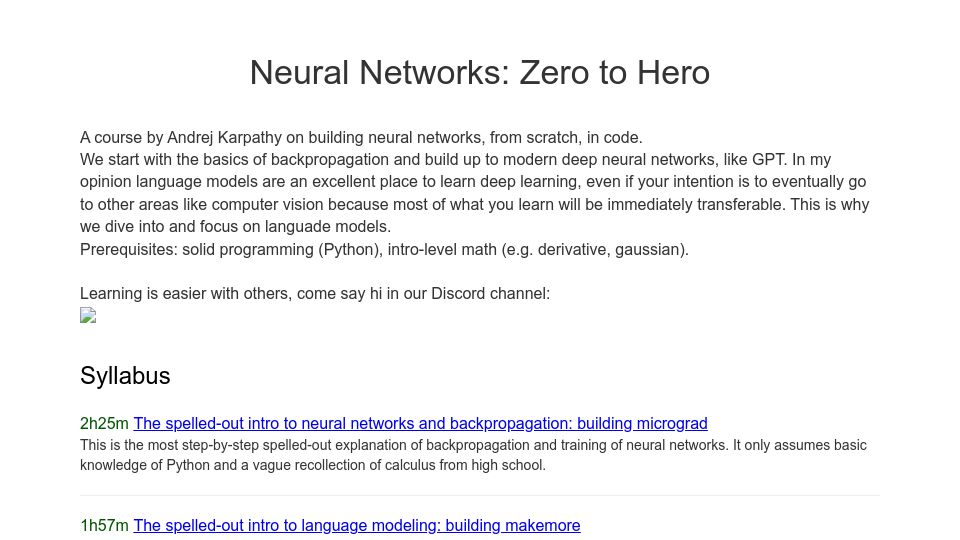
Andrej Karpathy's free video course page on building neural networks from scratch in Python, from backpropagation (micrograd) up to GPT-style language models.
826 points by iamwil | 396 comments
GitHub repository serving as an information hub for a project training large language models exclusively on historical texts published before 1913.
368 points by mseri | 120 comments
Ai2 blog post announcing Olmo 3, an open-source language model family released with its full development pipeline, or "model flow".
412 points by ghuntley | 85 comments
YouTube video by sammyuri showing a ChatGPT-style language model built using Minecraft redstone circuitry.
427 points by chilipepperhott | 154 comments
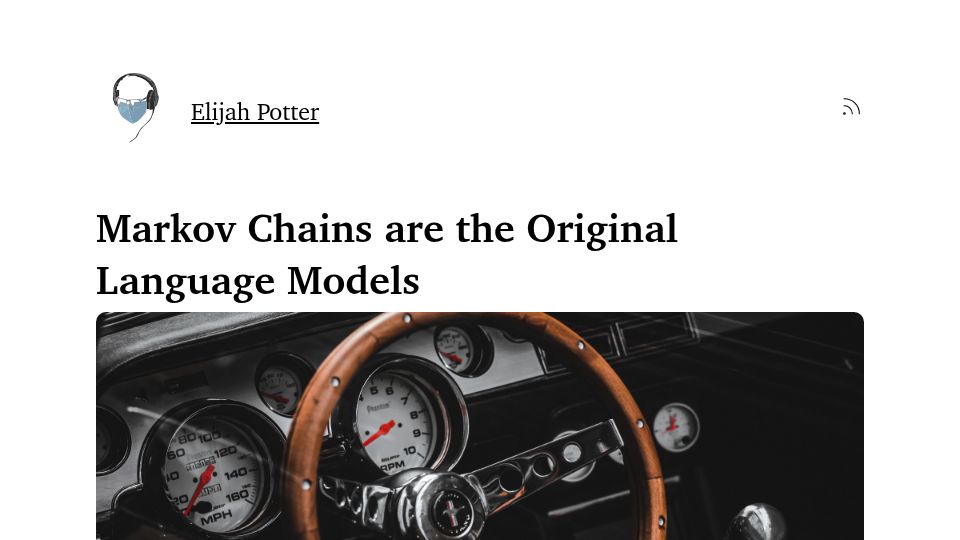
A blog post by Elijah Potter explaining Markov chains as early language models and how they generate text.
336 points by lawrenceyan | 119 comments
A blog post explaining how language models represent vast numbers of concepts in 12,000-dimensional embedding spaces using near-orthogonality and the Johnson-Lindenstrauss lemma.
476 points by ingve | 173 comments
Sean Goedecke's blog post on training the best small GPT-style model possible on a MacBook Pro in five minutes, landing on a ~1.8M-parameter transformer trained on TinyStories.
390 points by itchyjunk | 128 comments
Anthropic research post introducing persona vectors, a method for monitoring and controlling character traits in language models, with a link to the paper.

439 points by jxmorris12 | 34 comments
Online book by Nathan Lambert giving a short introduction to reinforcement learning from human feedback and post-training for language models.
626 points by crescit_eundo | 424 comments
A Dynomight newsletter post examining how well large language models play chess and why results vary strangely across models.
411 points by tplrbv | 72 comments
A long blog post analyzing how a small ~10M parameter transformer trained from Karpathy's tutorial turns attention outputs into next-token predictions.
341 points by guybedo | 73 comments
RWKV blog post announcing Eagle 7B, an RWKV-v5 linear transformer model trained on 1 trillion tokens across 100+ languages.
402 points by tompark | 58 comments
Anthropic research post from Oct 2023 on decomposing language model neurons into more interpretable features.
442 points by nojito | 218 comments
Blog post by Jack Cook investigating the Transformer language model Apple ships for inline predictive text in iOS and macOS.
444 points by bkitano19 | 39 comments
A blog tutorial by Brian Kitano on implementing a scaled-down Llama language model from scratch trained on TinyShakespeare, with tips for implementing research papers.
318 points by ianbutler | 164 comments
arXiv paper introducing RWKV, a model architecture combining Transformer-style parallel training with efficient RNN inference via linear attention.
659 points by mfiguiere | 416 comments
OpenAI research post describing using GPT-4 to automatically generate and score explanations of individual neuron behavior in GPT-2.
336 points by antimatter15 | 96 comments
Together blog post announcing the release of 3B and 7B RedPajama-INCITE language models, including base, instruction-tuned, and chat variants.
546 points by whereistimbo | 64 comments
Course page for Andrej Karpathy's Neural Networks: Zero to Hero, a video series building neural networks from scratch in code up to GPT-style language models.