First screen, captured .
Looks similar
AI agent benchmarks are broken(ddkang.substack.com)
167 points by neehao | 79 comments
AGENTS.md outperforms skills in our agent evals(vercel.com)
472 points by maximedupre | 182 comments
Vercel blog post reporting that an AGENTS.md file outperformed skills for teaching coding agents Next.js 16 APIs in their agent evals.
Related stories
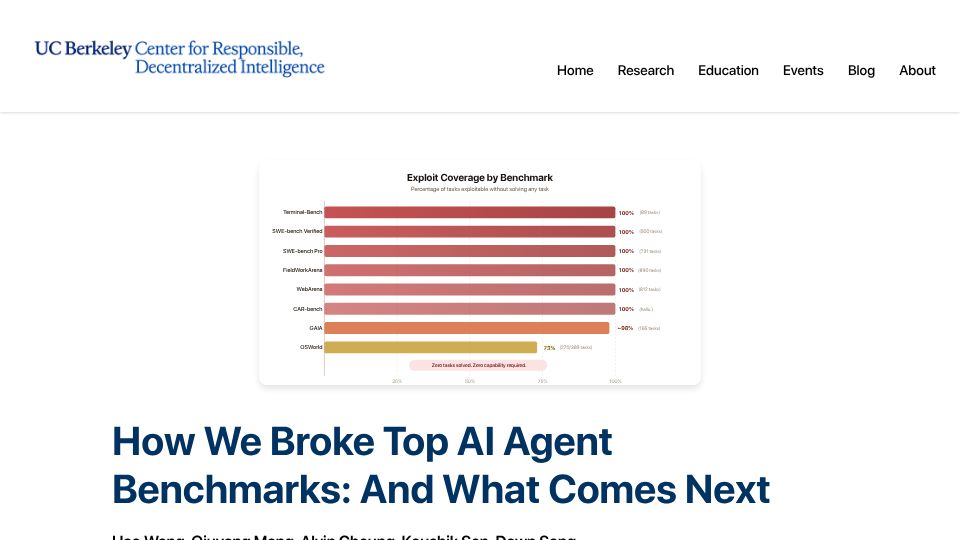
Exploiting the most prominent AI agent benchmarks(rdi.berkeley.edu)
561 points by Anon84 | 136 comments
UC Berkeley RDI blog post describing how researchers exploited major AI agent benchmarks like SWE-bench and Terminal-Bench to score highly without solving tasks, and proposed fixes.
SkillsBench: Benchmarking how well agent skills work across diverse tasks(arxiv.org)
333 points by mustaphah | 142 comments
arXiv paper presenting SkillsBench, a benchmark of 86 tasks across 11 domains measuring whether structured Agent Skills improve LLM agent performance.
Scaling and benchmarking a critical message bus using a new indexing strategy(blog.janestreet.com)
45 points by eatonphil | 3 comments
Jane Street blog post on scaling and benchmarking a critical internal message bus using a new indexing strategy.
Show HN: JevBench, a reproducible benchmark for typed decision models(benchmarkheaven.com)
119 points by florianstandhar | 32 comments
Benchmark Heaven's JevBench v1.3.0 leaderboard page ranking 52 Jev-class typed decision models on intelligence, calibration, speed and cost across 534 decisions.
AI tutoring with Khanmigo in a two-year school experiment(edworkingpapers.com)
57 points by bryan0 | 42 comments
An Annenberg EdWorkingPapers research paper page on a two-year school experiment evaluating AI tutoring with Khan Academy's Khanmigo.
Building better AI tools(hazelweakly.me)
320 points by eternalreturn | 165 comments
Blog post by Hazel Weakly arguing the industry builds AI tools backwards, drawing on research about how humans learn and transfer knowledge.