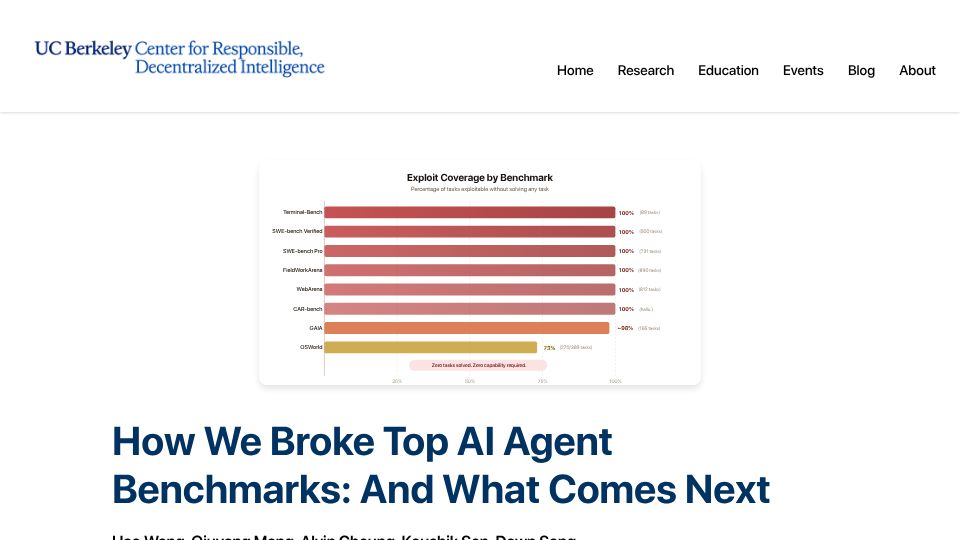
Exploiting the most prominent AI agent benchmarks(rdi.berkeley.edu)
561 points by Anon84 | 136 comments
UC Berkeley RDI blog post describing how researchers exploited major AI agent benchmarks like SWE-bench and Terminal-Bench to score highly without solving tasks, and proposed fixes.