First screen, captured .
Looks similar
Related stories
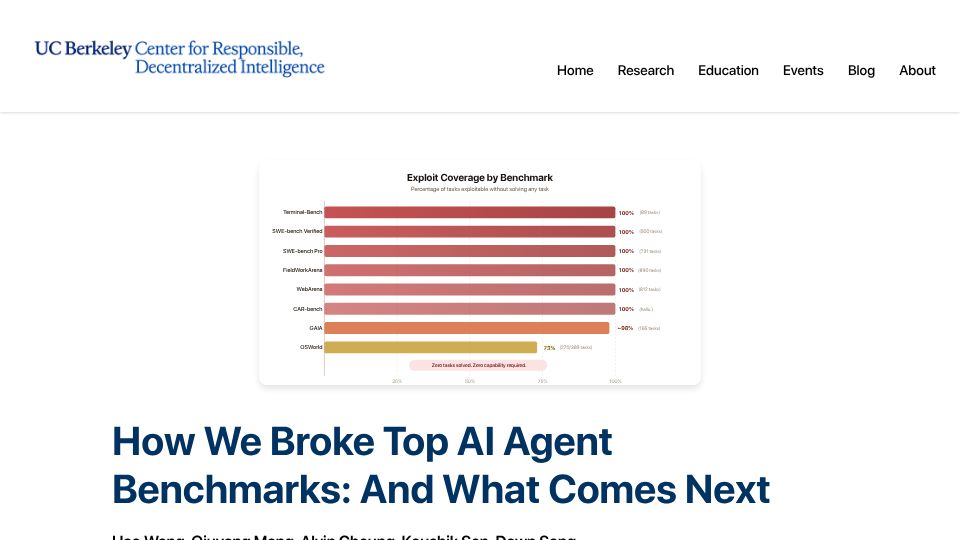
Exploiting the most prominent AI agent benchmarks(rdi.berkeley.edu)
561 points by Anon84 | 136 comments
UC Berkeley RDI blog post describing how researchers exploited major AI agent benchmarks like SWE-bench and Terminal-Bench to score highly without solving tasks, and proposed fixes.
AI models may be capable of self-replicating without access to a datacenter(anthropic.com)
36 points by artninja1988 | 26 comments
Anthropic Frontier Red Team post reporting experiments suggesting small AI models may soon self-replicate on commercial IoT devices without datacenter access.
AI companies in race to demonstrate their model most threatening to humanity(thecivilian.co.nz)
388 points by ljewalsh | 304 comments
Satirical news article from The Civilian claiming AI companies are competing to show their models are the most existentially threatening to humanity.
Study identifies weaknesses in how AI systems are evaluated(oii.ox.ac.uk)
397 points by pseudolus | 186 comments
Oxford Internet Institute news item on a study finding that most of 445 LLM benchmarks lack rigorous methods and clear definitions of what they measure.
Qwen3.8 Max now ranked as the best overall model by agentic index(artificialanalysis.ai)
458 points by apitman | 291 comments
Artificial Analysis homepage offering independent benchmarks and rankings of AI models and providers, here linked to its agentic intelligence index view.
AI will make formal verification go mainstream(martin.kleppmann.com)
782 points by evankhoury | 394 comments
Martin Kleppmann blog post predicting that AI will bring formal verification with proof assistants like Rocq, Isabelle and Lean into mainstream software engineering.