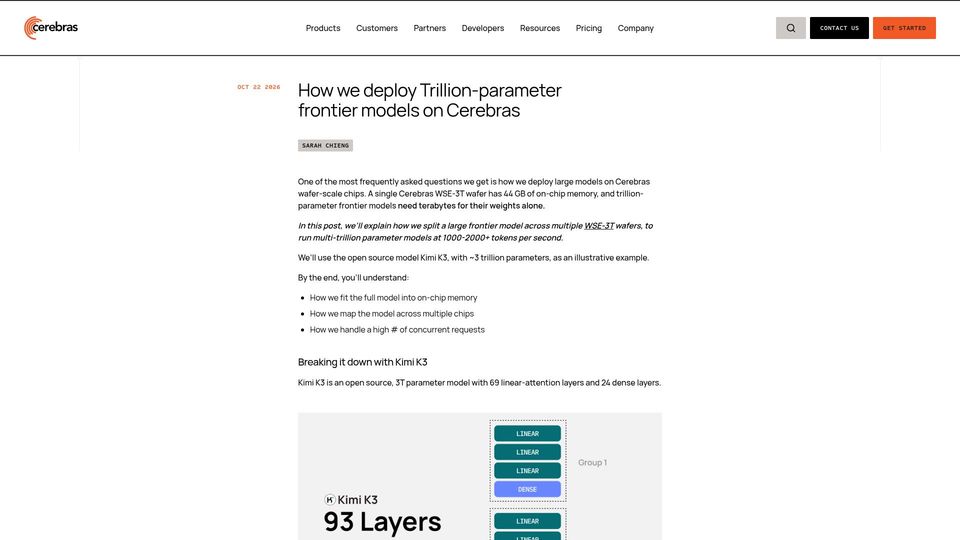
Cerebras Deploys Trillion-Parameter AI Models(cerebras.ai)
349 points by gmays | 127 comments
Cerebras blog post explaining how trillion-parameter models like Kimi K3 are split across multiple WSE-3T wafers for pipelined, high-throughput inference.
4 stories tagged kv-cache, newest first.
349 points by gmays | 127 comments
Cerebras blog post explaining how trillion-parameter models like Kimi K3 are split across multiple WSE-3T wafers for pipelined, high-throughput inference.
399 points by ModelForge | 55 comments
GitHub directory in Sebastian Raschka's LLMs-from-scratch repo with notebooks re-implementing Google's Gemma 3 270M model in pure PyTorch, including a KV cache variant.
424 points by hochmartinez | 176 comments
VentureBeat article by Ben Dickson on a new LLM optimization technique that reduces memory costs by up to 75%.
640 points by gzer0 | 265 comments
A draft GitHub pull request to llama.cpp adding full CUDA GPU acceleration for all ggml tensors, including storing the KV cache in VRAM.