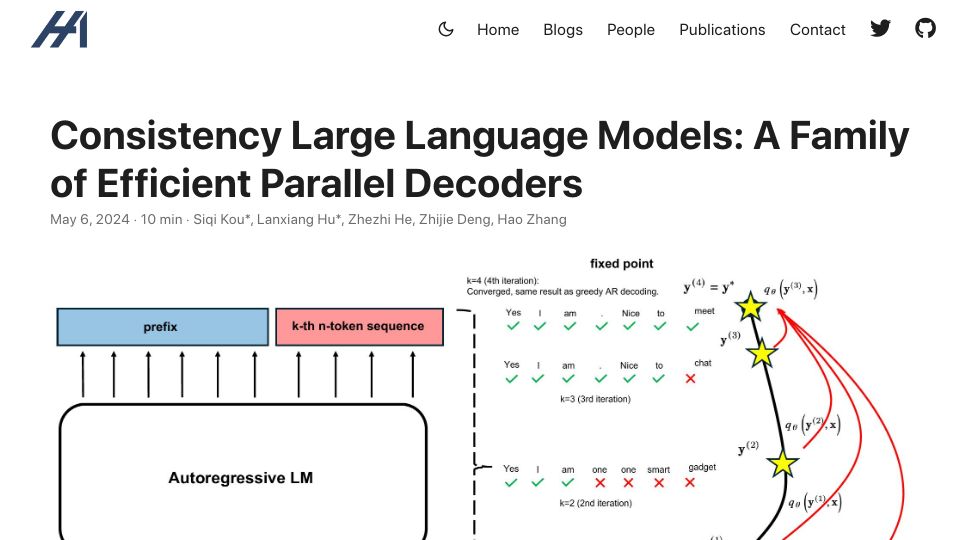
Consistency LLM: converting LLMs to parallel decoders accelerates inference 3.5x(hao-ai-lab.github.io)
447 points by zhisbug | 94 comments
Hao AI Lab blog post introducing Consistency LLMs, a method that fine-tunes LLMs into parallel Jacobi decoders to speed up inference about 3.5x.