Kimi K3 Architecture Overview and Notes(sebastianraschka.com)
472 points by ModelForge | 101 comments
Sebastian Raschka's blog post with an architecture figure and notes on the Kimi K3 open-weight model, a 2.8T scaled-up version of Kimi Linear.
First screen, captured .
472 points by ModelForge | 101 comments
Sebastian Raschka's blog post with an architecture figure and notes on the Kimi K3 open-weight model, a 2.8T scaled-up version of Kimi Linear.
343 points by shchegrikovich | 122 comments
Substack post arguing that having LLMs generate Prolog code can improve their reasoning, given the limits of autoregressive transformer generation.
44 points by vinhnx | 36 comments
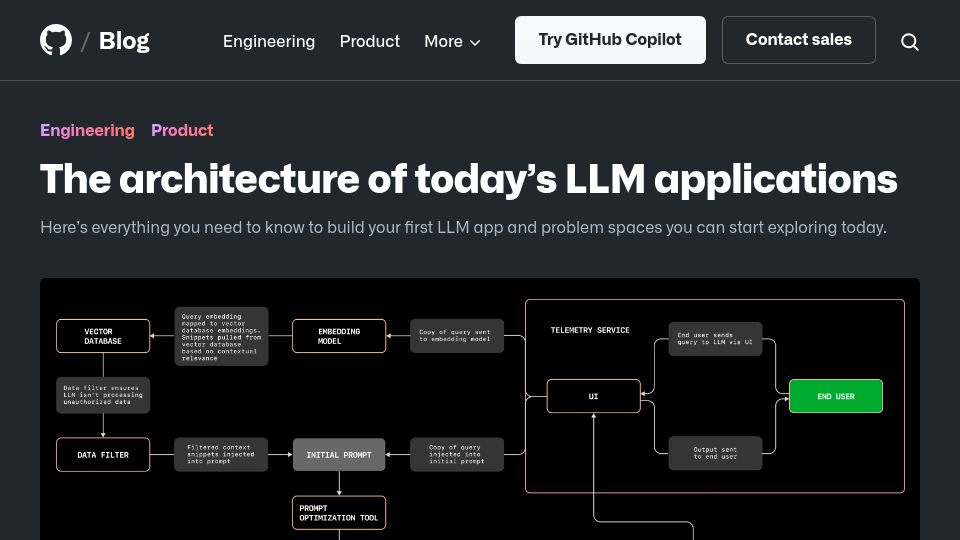
256 points by tjohnell | 171 comments
357 points by mdp2021 | 23 comments
Sebastian Raschka's Ahead of AI article comparing the architectures of modern LLMs, from DeepSeek-V3 to Kimi K2.
99 points by sdko | 3 comments
An LLVM Project Blog post by Tanya Lattner remembering LLVM contributor Johannes Doerfert.
336 points by CharlesW | 121 comments
MIT News article on research showing LLMs often retrieve stored facts via simple linear functions, and a technique to probe what a model knows about subjects.

335 points by minimaxir | 183 comments
Max Woolf's blog post describing how he, as an experienced data scientist and LLM tool developer, actually uses generative LLMs only sparingly in his work.
472 points by ModelForge | 101 comments
Sebastian Raschka's blog post with an architecture figure and notes on the Kimi K3 open-weight model, a 2.8T scaled-up version of Kimi Linear.
519 points by tosh | 201 comments
Qwen team blog post announcing Qwen3-Next, a model architecture aimed at improving LLM training and inference efficiency.