RWKV: Reinventing RNNs for the Transformer Era(arxiv.org)
318 points by ianbutler | 164 comments
arXiv paper introducing RWKV, a model architecture combining Transformer-style parallel training with efficient RNN inference via linear attention.
First screen, captured .
318 points by ianbutler | 164 comments
arXiv paper introducing RWKV, a model architecture combining Transformer-style parallel training with efficient RNN inference via linear attention.
209 points by fofoz | 129 comments
445 points by wuubuu | 112 comments
arXiv paper by Andrew Gordon Wilson arguing deep learning generalization phenomena like benign overfitting and double descent are explainable by soft inductive biases.
318 points by ianbutler | 164 comments
arXiv paper introducing RWKV, a model architecture combining Transformer-style parallel training with efficient RNN inference via linear attention.
269 points by E-Reverance | 79 comments
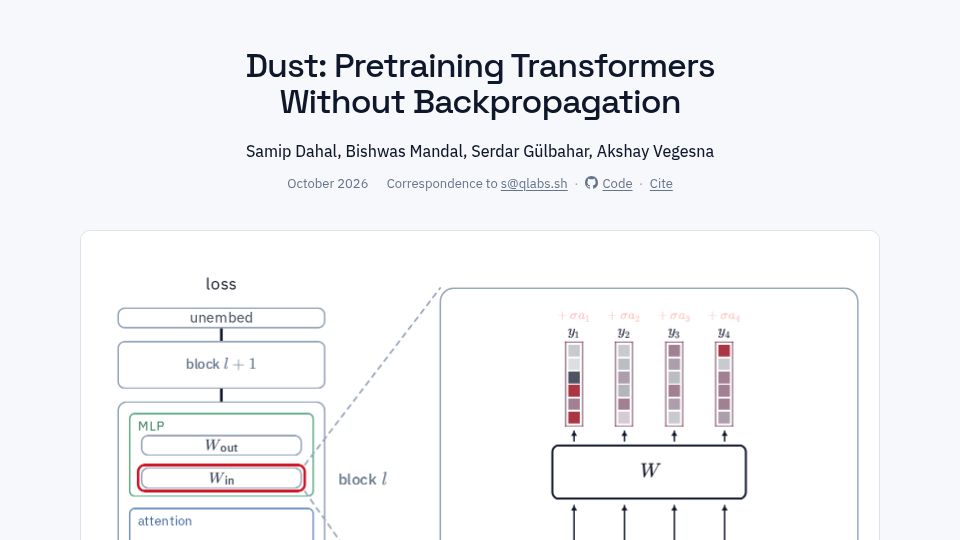
Research page from QLabs presenting Dust, a method for pretraining transformer models without backpropagation, with authors, code link, and architecture diagram.
549 points by chmaynard | 134 comments
Rachel Thomas blog post on how a high-profile Nature paper using a Transformer to predict enzyme functions contained many errors that received far less attention than the original result.
545 points by davidbarker | 369 comments
OpenAI post announcing that GPT-5.2 derived a new result in theoretical physics; the captured page shows only a loading logo.
959 points by elbasti | 307 comments
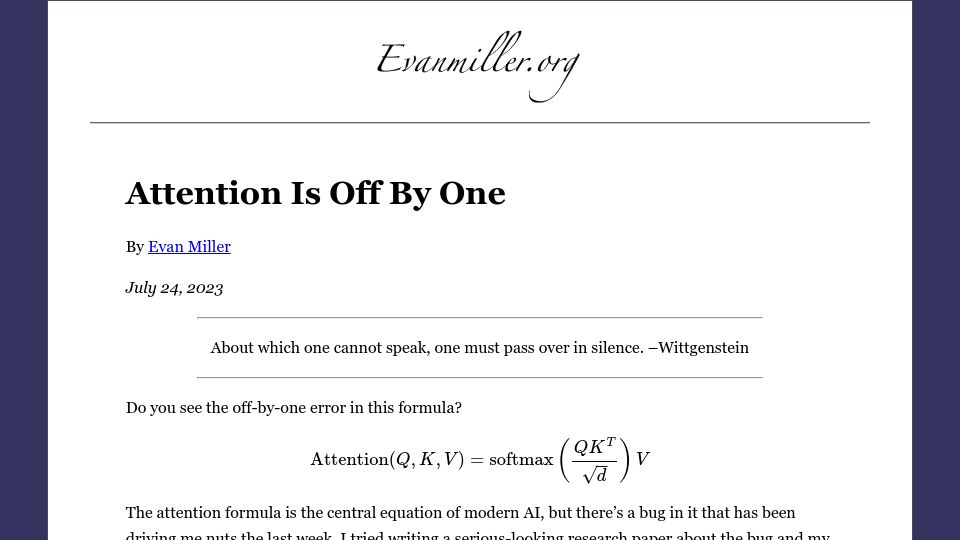
Evan Miller's blog post arguing that the softmax in the transformer attention formula has an off-by-one flaw and proposing a modified softmax.