You could have invented transformers from memory(alexwang.ai)
602 points by speckx | 133 comments
Blog post by Alex Wang explaining transformer layers (MLPs, gated MLPs, self-attention) as associative memory stores, with code and an interactive app.
45 stories tagged deep-learning, newest first.
602 points by speckx | 133 comments
Blog post by Alex Wang explaining transformer layers (MLPs, gated MLPs, self-attention) as associative memory stores, with code and an interactive app.
114 points by bingden | 38 comments
A personal blog post recounting a summer at Recurse Center, covering study groups on LLM agents, deep learning, math, and a board game AI.
336 points by sans_souse | 25 comments
AI by Hand is a site teaching AI and deep learning concepts through hand-worked math exercises; the captured page was blank.
592 points by notmcrowley | 98 comments
A website presenting the rumoured list of ML papers Ilya Sutskever gave John Carmack (27 known so far) in a beginner-friendly format.
802 points by ternaus | 143 comments
OpenCV team blog post announcing the release of OpenCV 5, describing its major new features for computer vision and deep learning.
529 points by kristianpaul | 49 comments
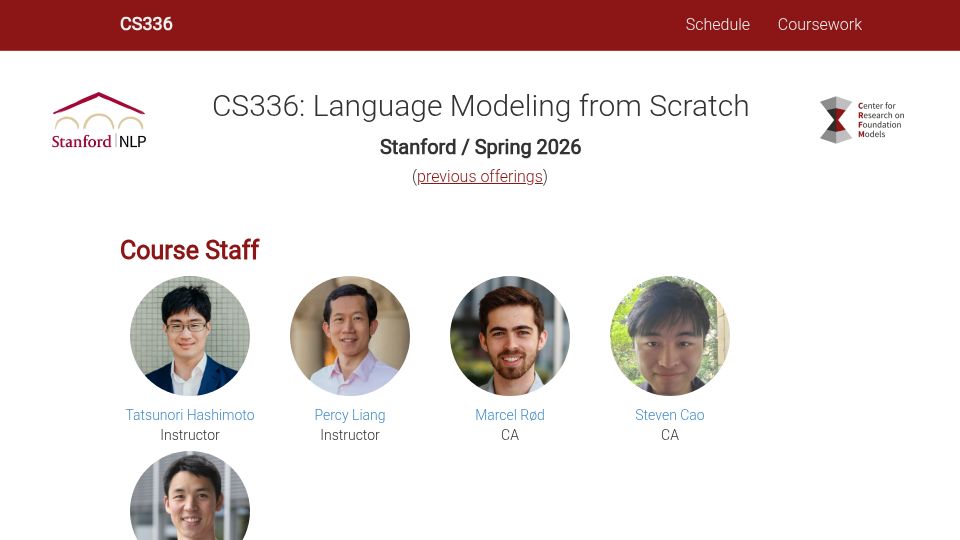
Course homepage for Stanford's CS336: Language Modeling from Scratch (Spring 2026), listing instructors Tatsunori Hashimoto and Percy Liang and course staff.
320 points by jamie-simon | 142 comments
An arXiv position paper arguing that a scientific theory of deep learning is emerging, surveying five strands of research such as solvable models, scaling limits, and universal behaviors.
562 points by albelfio | 325 comments
Product section of the tinygrad website describing the tinybox, a computer built for deep learning workloads; the page rendered blank when captured.
372 points by 0bytematt | 25 comments
A visual, beginner-friendly tutorial introducing PyTorch, covering tensors, autograd, and building a simple neural network.
468 points by auraham | 85 comments
Jay Alammar's illustrated blog post explaining the Transformer neural network architecture and its self-attention mechanism with visual diagrams.
665 points by saikatsg | 162 comments
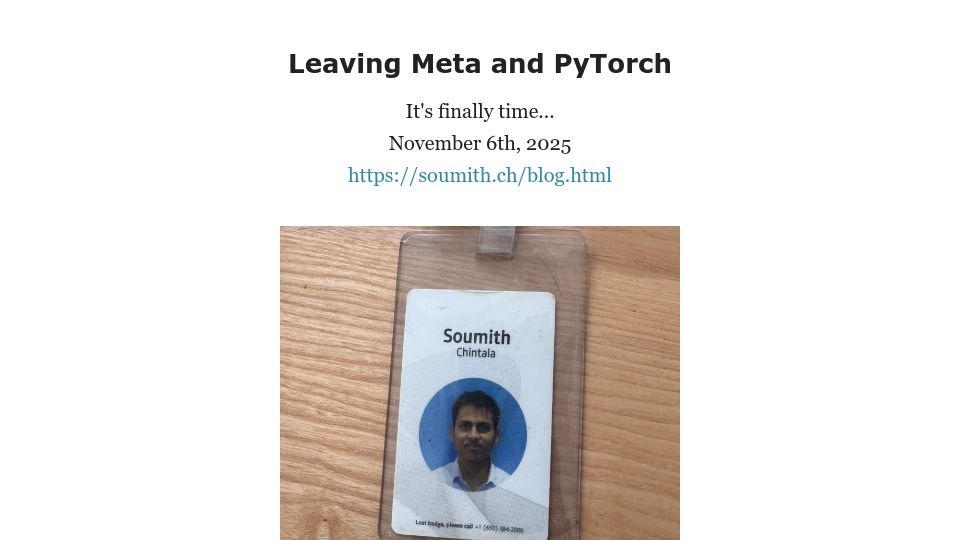
Blog post by PyTorch co-creator Soumith Chintala announcing his departure from Meta and the PyTorch project, dated November 6, 2025.
335 points by swatson741 | 132 comments
Andrej Karpathy's 2016 Medium essay arguing that practitioners should understand backpropagation because it is a leaky abstraction.
426 points by bblcla | 78 comments
Blog post recounting how a training loss plateau turned out to be a PyTorch bug, traced through optimizer internals down to GPU kernels.
625 points by diyer22 | 86 comments
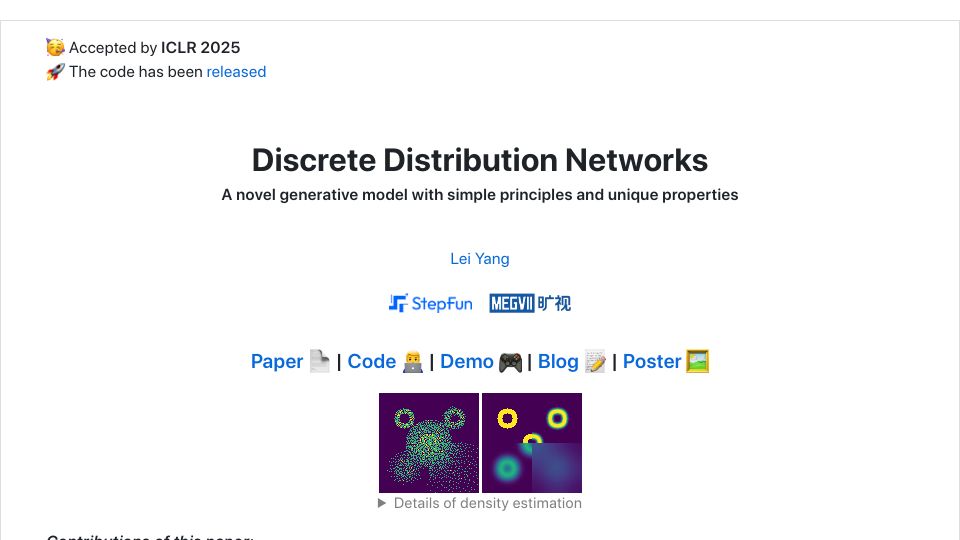
Project page for Discrete Distribution Networks, an ICLR 2025 paper proposing a generative model that outputs multiple samples per forward pass to approximate distributions.
335 points by JnBrymn | 218 comments
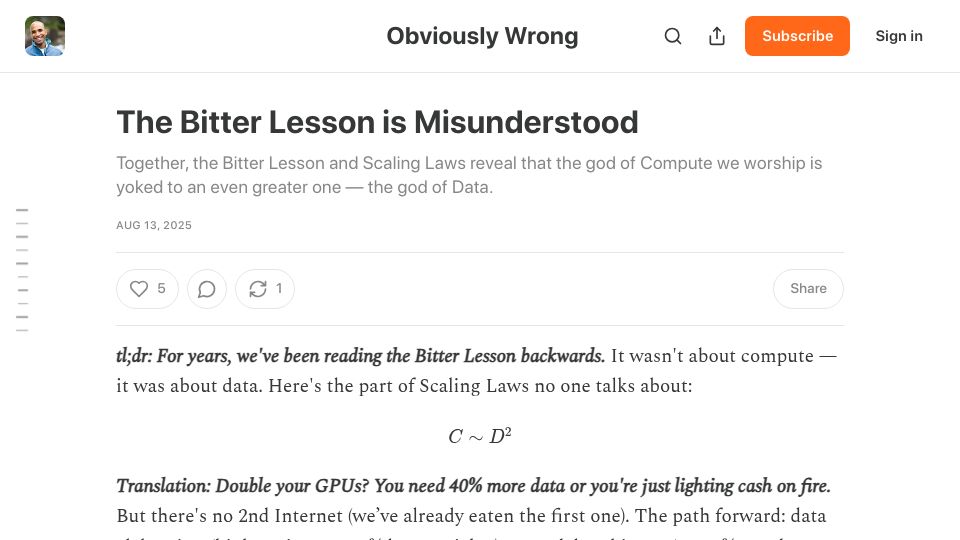
A Substack essay arguing the Bitter Lesson is really about data rather than compute, citing scaling laws where compute scales with data squared.
448 points by bilsbie | 240 comments
Jack Morris essay arguing that major AI breakthroughs, including LLMs, came from new datasets rather than new ideas or methods.
549 points by chmaynard | 134 comments
Rachel Thomas blog post on how a high-profile Nature paper using a Transformer to predict enzyme functions contained many errors that received far less attention than the original result.
473 points by theahura | 176 comments
A Substack essay from 12 Grams of Carbon arguing that deep learning is applied topology, explaining how neural networks transform data lying on manifolds.
445 points by wuubuu | 112 comments
arXiv paper by Andrew Gordon Wilson arguing deep learning generalization phenomena like benign overfitting and double descent are explainable by soft inductive biases.
414 points by anonymousiam | 268 comments
Live Science news article on AI models using deep learning to design wireless chips with unusual, hard-to-understand layouts that outperform human-made designs.
459 points by leroman | 34 comments
YouTube video by Andrej Karpathy giving a deep dive into how large language models like ChatGPT work.
348 points by misonic | 31 comments
A Distill article giving an interactive, illustrated introduction to graph neural networks and the design choices behind their components.
326 points by xnx | 139 comments
Google for Developers blog post announcing François Chollet, creator of Keras, is leaving Google and thanking him for his contributions.
321 points by rejuvyesh | 137 comments
Launch HN post for Silurian, a YC S24 startup building AI foundation models to simulate Earth's weather, including its 1.5B-parameter GFT forecasting model.
910 points by mdp2021 | 110 comments
Sebastian Raschka's Ahead of AI newsletter post presenting a 3-hour video coding workshop on implementing, training, and using LLMs from scratch.
387 points by huhhuh | 46 comments
A 3Blue1Brown YouTube video giving a visual introduction to GPT and the transformer architecture, chapter 5 of its deep learning series.
350 points by marban | 218 comments
Wired Backchannel feature by Steven Levy on the eight Google researchers who wrote the Transformers paper that underpins modern AI.
645 points by alphabetting | 223 comments
Google Open Source Blog post announcing Magika, an open-source AI-powered tool for fast and efficient file type identification.
408 points by LaserPineapple | 94 comments
A hackerllama blog post walking through an end-to-end worked example of transformer math using small random vectors and matrices.

412 points by Anon84 | 132 comments
arXiv listing for a book by Jentzen, Kuckuck, and von Wurstemberger giving a mathematically rigorous introduction to deep learning methods, implementations, and theory.
391 points by johnma2006 | 107 comments
GitHub repository with a simple, minimal single-file PyTorch implementation of the Mamba state-space model architecture.
347 points by georgehill | 79 comments
Homepage for Simon J.D. Prince's book Understanding Deep Learning (MIT Press, 2023), offering a free draft PDF of chapters 1-21 under a CC license.
376 points by Tomte | 43 comments
François Fleuret's University of Geneva deep learning course page offering slides, recordings, and a virtual machine, with examples in PyTorch.
642 points by qwertyforce | 55 comments
Animated AI is a site of 3D animations and instructional videos explaining neural network concepts, starting with the basic convolution algorithm.
422 points by Anon84 | 149 comments
A Substack primer by Abhinav Upadhyay explaining GPU architecture and computing concepts for software developers familiar mainly with CPUs.
373 points by PaulHoule | 114 comments
arXiv paper introducing TimeGPT, a foundation model for time series forecasting that performs zero-shot predictions on unseen datasets.
387 points by jdkee | 117 comments
A fast.ai blog post by Jeremy Howard and Jonathan Whitaker on unusual fine-tuning loss curves suggesting LLMs can memorize examples after seeing them once.
372 points by mikece | 214 comments
BleepingComputer article on a research attack that uses deep learning on recorded keyboard sounds to infer keystrokes with 95% accuracy.
446 points by nihit-desai | 196 comments
Andreessen Horowitz's "AI Canon," a curated list of resources for learning about modern AI and generative AI, by Derrick Harris, Matt Bornstein, and Guido Appenzeller.
515 points by Sai_ | 196 comments
Ask HN thread requesting a simple explanation of transformer models and the "Attention Is All You Need" paper, with community replies and resource links.
883 points by ramraj07 | 510 comments
New York Times article reporting that AI pioneer Geoffrey Hinton left Google so he could speak openly about the risks of artificial intelligence.
420 points by dataminer | 29 comments
A PDF of François Fleuret's The Little Book of Deep Learning, a short introductory textbook on deep learning.
594 points by jasim | 46 comments
A long-form tutorial explaining how transformer neural networks work from the ground up, covering matrix multiplication, attention, and backpropagation.
546 points by whereistimbo | 64 comments
Course page for Andrej Karpathy's Neural Networks: Zero to Hero, a video series building neural networks from scratch in code up to GPT-style language models.
538 points by noob_eng | 101 comments
Overview page for fast.ai's Practical Deep Learning Part 2 course, a 30+ hour video course implementing Stable Diffusion from scratch.