First screen, captured .
Looks similar
Related stories
What are transformer models and how do they work?(txt.cohere.ai)
380 points by tomcam | 91 comments
Cohere blog post explaining what transformer models are and how they work in natural language processing.
Deep learning gets the glory, deep fact checking gets ignored(rachel.fast.ai)
549 points by chmaynard | 134 comments
Rachel Thomas blog post on how a high-profile Nature paper using a Transformer to predict enzyme functions contained many errors that received far less attention than the original result.
Transformers from Scratch (2021)(e2eml.school)
594 points by jasim | 46 comments
A long-form tutorial explaining how transformer neural networks work from the ground up, covering matrix multiplication, attention, and backpropagation.
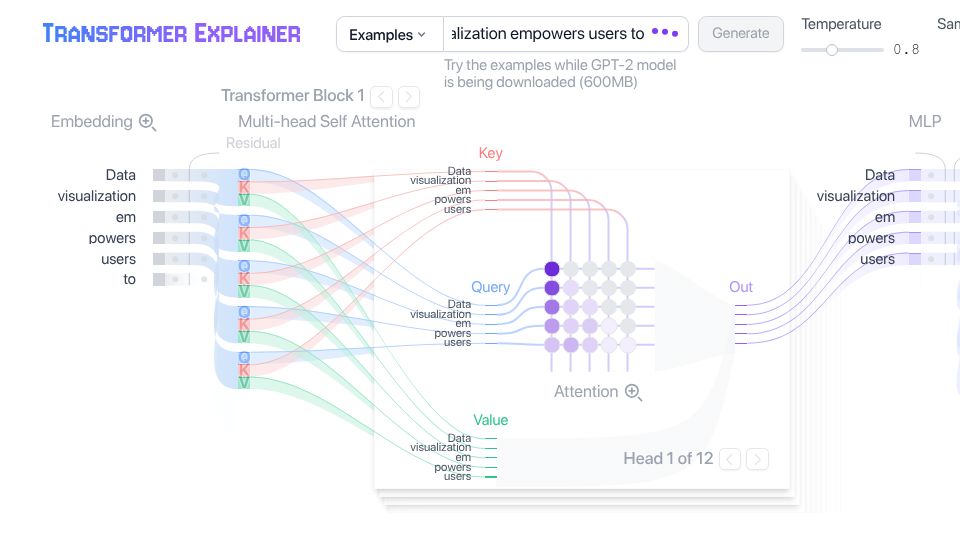
Transformers Explained Visually(poloclub.github.io)
576 points by aray07 | 85 comments
Transformer Explainer is an interactive in-browser visualization that runs GPT-2 and shows how embeddings, multi-head self-attention, and MLP layers process text.
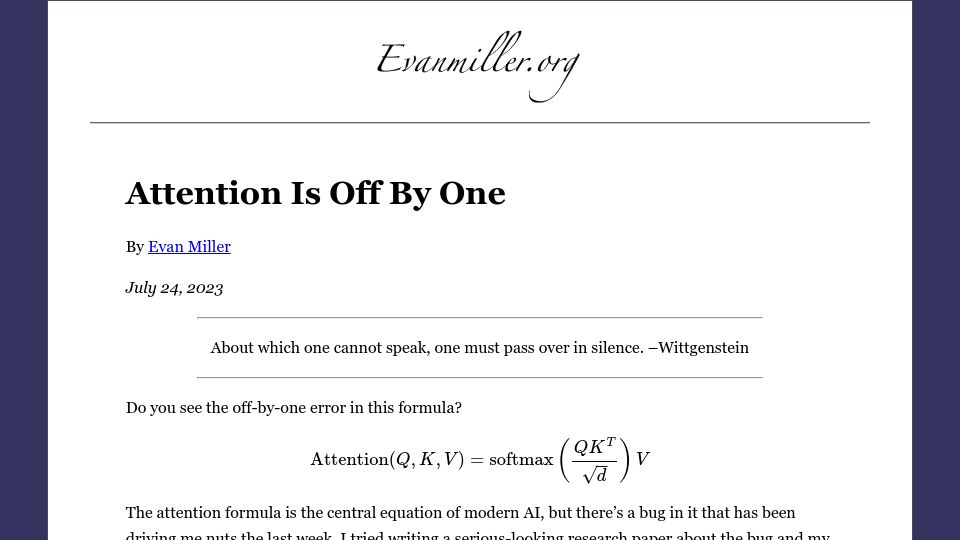
Attention Is Off By One(evanmiller.org)
959 points by elbasti | 307 comments
Evan Miller's blog post arguing that the softmax in the transformer attention formula has an off-by-one flaw and proposing a modified softmax.
RWKV: Reinventing RNNs for the Transformer Era(arxiv.org)
318 points by ianbutler | 164 comments
arXiv paper introducing RWKV, a model architecture combining Transformer-style parallel training with efficient RNN inference via linear attention.