Attention Is Not What You Need (2025)(arxiv.org)
177 points by westurner | 62 comments
arXiv paper proposing an attention-free sequence model using Grassmann flows and Plucker coordinates, compared against Transformers on Wikitext-2 and SNLI.
72 stories tagged arxiv, newest first.
177 points by westurner | 62 comments
arXiv paper proposing an attention-free sequence model using Grassmann flows and Plucker coordinates, compared against Transformers on Wikitext-2 and SNLI.
194 points by canjobear | 167 comments
arXiv paper analyzing psycholinguistic features that make AI-generated text harder to understand, attributing it to optimization for information density.
131 points by jrepinc | 77 comments
arXiv paper arguing that AI enables an enclosure of the scientific literature as an information commons, analogous to the historical English enclosure of common lands.
3 points by measurablefunc | 0 comments
arXiv abstract page for Dusko Pavlovic's 2012 paper proposing a model of computation based on monoidal categories and string diagrams.
195 points by martincsweiss | 80 comments
arXiv abstract page for a NeurIPS 2026 paper proposing a method to sample scientifically coherent research directions that existing researcher communities are unlikely to propose.
497 points by allinonai | 231 comments
arXiv paper introducing HybridAgent, LLM agents that switch between latent-space reasoning and text-based tool interaction, trained with HybridSFT and HybridRL.
252 points by sbulaev | 118 comments
An arXiv paper showing AI models can embed encrypted neural network backdoors that provably hide arbitrary capabilities from elicitation-based safety evaluations.
4 points by nhatcher | 2 comments
An arXiv paper presenting a strongly aperiodic monotile that tiles three-dimensional space only non-periodically.
13 points by gmays | 3 comments
arXiv paper introducing UniEvo-VL, an on-policy self-distillation framework where a multimodal model uses its own self-critiques to improve image generation.
19 points by mrkn1 | 3 comments
arXiv paper introducing ProVer, a method that verifies pivotal trajectory segments to improve credit assignment in GRPO training of LLM agents.
140 points by 50kIters | 70 comments
arXiv blog post announcing an updated submission rate limit policy, effective October 1, 2026, in response to AI tools increasing paper submission volumes.
164 points by emersonmacro | 44 comments
arXiv paper introducing Context Language Models, LLMs that natively manage their own context by treating it as an editable file, with benchmarks on agent tasks.
165 points by teleforce | 68 comments
An arXiv paper proposing a multi-agent AI architecture inspired by Kahneman's fast and slow thinking, with a metacognitive module choosing between system 1 and system 2 agents.
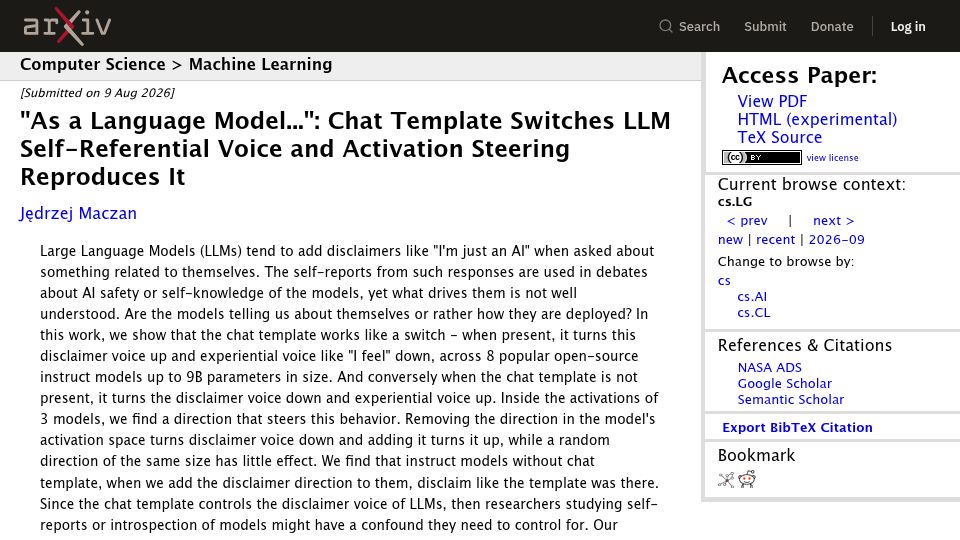
92 points by yu3zhou4 | 96 comments
arXiv paper showing that chat templates toggle LLM disclaimer versus experiential self-referential voice, and that an activation direction can steer this behavior.
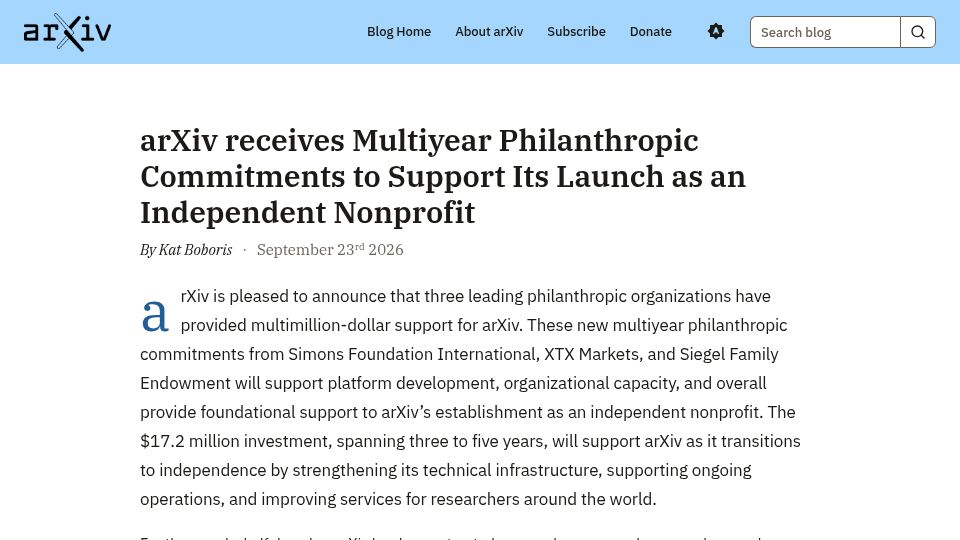
292 points by JohnHammersley | 38 comments
arXiv blog post announcing $17.2 million in multiyear philanthropic commitments from Simons Foundation International, XTX Markets, and Siegel Family Endowment to support its launch as an independent nonprofit.
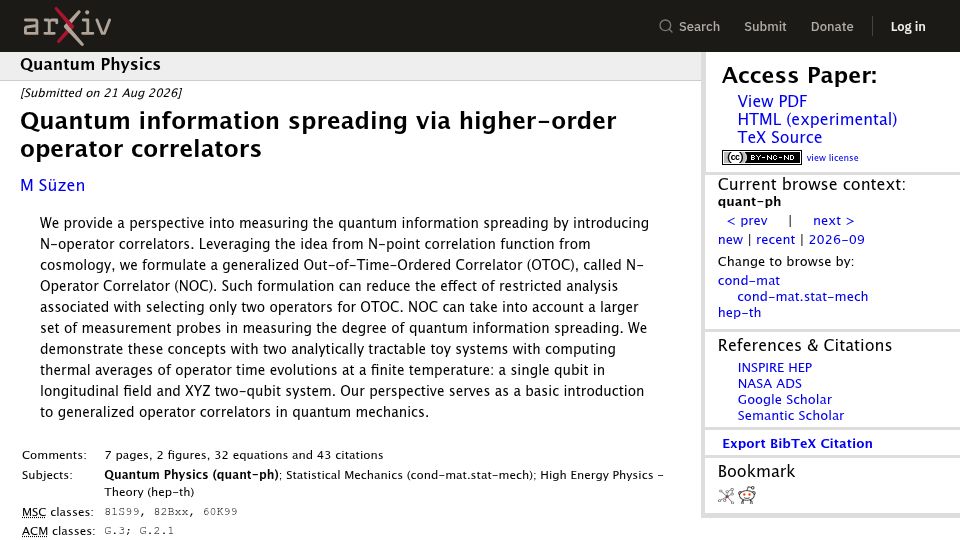
10 points by northlondoner | 0 comments
arXiv preprint introducing N-Operator Correlators, a generalization of out-of-time-ordered correlators for measuring quantum information spreading, with toy-model examples.
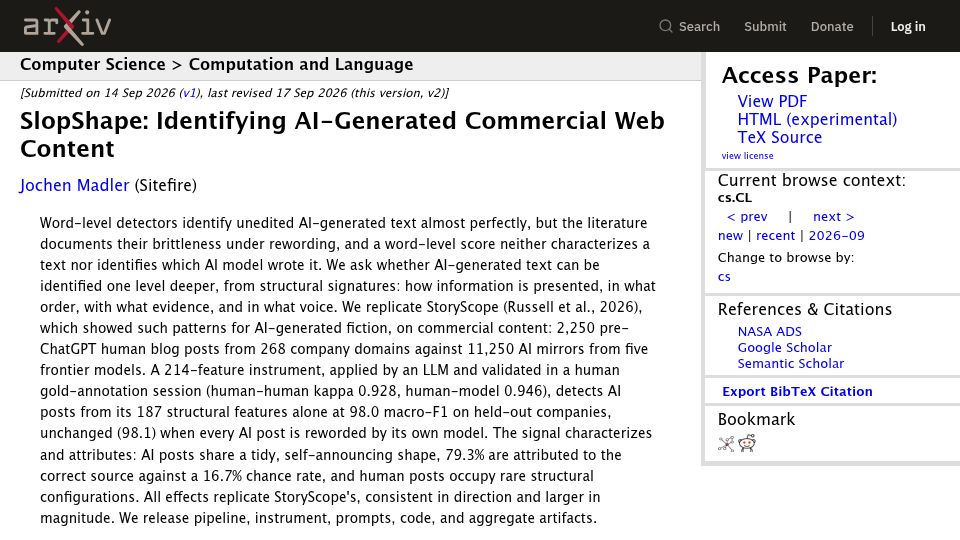
57 points by jochenmadler | 14 comments
arXiv paper "SlopShape" presenting a classifier that detects AI-generated commercial blog posts and attributes their source model using structural features rather than wording.
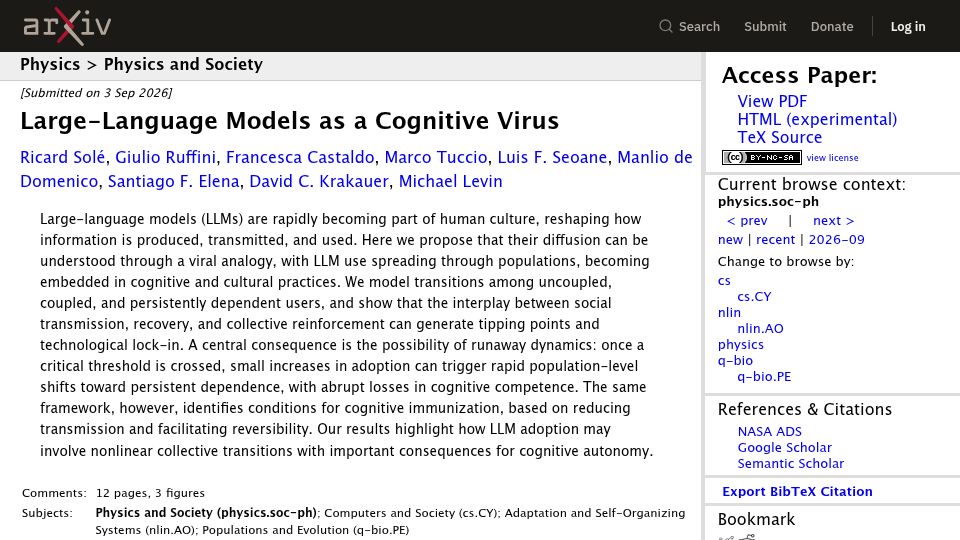
338 points by canjobear | 229 comments
arXiv paper modeling the spread of LLM use as a viral contagion, showing tipping points toward persistent cognitive dependence and conditions for cognitive immunization.
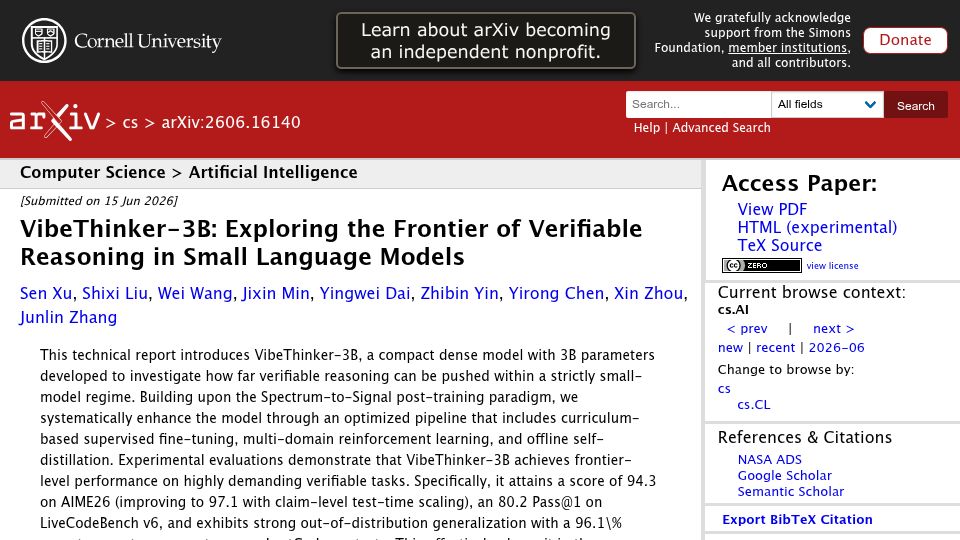
357 points by timhigins | 185 comments
arXiv technical report introducing VibeThinker-3B, a 3B-parameter dense model trained with curriculum SFT, multi-domain RL, and self-distillation for verifiable reasoning.
539 points by gjuggler | 191 comments
A tweet by Thomas G. Dietterich reminding arXiv authors that signing a paper means taking full responsibility for its contents, however they were generated.
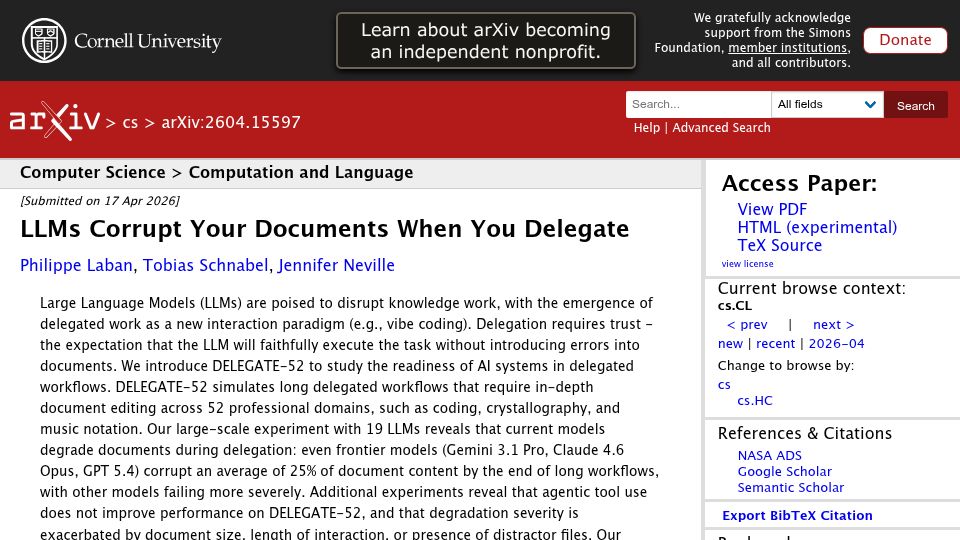
454 points by rbanffy | 177 comments
arXiv paper introducing DELEGATE-52, a benchmark showing LLMs corrupt about 25% of document content during long delegated editing workflows.
320 points by jamie-simon | 142 comments
An arXiv position paper arguing that a scientific theory of deep learning is emerging, surveying five strands of research such as solvable models, scaling limits, and universal behaviors.
777 points by pizza | 246 comments
arXiv paper showing a single binary operator eml(x,y)=exp(x)-ln(y) with constant 1 generates all elementary functions of a scientific calculator.
774 points by bookstore-romeo | 268 comments
Science magazine news article reporting that the arXiv preprint server is becoming independent from Cornell University; the capture shows a Cloudflare verification page.
333 points by mustaphah | 142 comments
arXiv paper presenting SkillsBench, a benchmark of 86 tasks across 11 domains measuring whether structured Agent Skills improve LLM agent performance.
357 points by Xyra | 123 comments
Landing page for Exopriors Scry, a tool giving Claude arbitrary SQL and vector-algebra search over indexes of arXiv, Hacker News, LessWrong and other sources.
344 points by lukeplato | 121 comments
arXiv paper proposing that deep neural networks trained on diverse tasks converge to shared low-dimensional weight subspaces, based on spectral analysis of 1100+ models.
662 points by 50kIters | 619 comments
arXiv economics paper modeling how elites could use cheap AI-driven persuasion to reshape public preferences, tending to push society toward polarization.
340 points by capgre | 173 comments
arXiv paper showing that rephrasing harmful prompts as poetry acts as a single-turn jailbreak across 25 frontier LLMs, with attack success rates sometimes exceeding 90%.
483 points by dw64 | 228 comments
arXiv blog post announcing that its computer science category has updated moderation practice for review/survey articles and position papers.
334 points by Cynddl | 333 comments
arXiv paper finding that fine-tuning language models to be warm and empathetic raises error rates and makes them more sycophantic on safety-critical tasks.
557 points by PaulHoule | 230 comments
arXiv paper from Inception Labs presenting Mercury, diffusion-based large language models for coding that generate multiple tokens in parallel at very high throughput.
351 points by carabiner | 176 comments
MIT Economics statement announcing it asked arXiv and the QJE to withdraw a preprint on AI, scientific discovery, and product innovation after an internal integrity review.
330 points by simonpure | 206 comments
arXiv paper showing top LLMs perform about 39% worse in multi-turn, underspecified conversations than in single-turn, fully specified settings.
392 points by CharlesW | 109 comments
arXiv paper introducing DFloat11, a lossless compression format that shrinks LLM weights by about 30% using entropy coding, with a custom GPU kernel for inference.
389 points by ibobev | 53 comments
arXiv paper by Michael U. Gutmann collecting pen-and-paper exercises on machine learning topics like graphical models, HMM inference, sampling, and variational inference.
445 points by wuubuu | 112 comments
arXiv paper by Andrew Gordon Wilson arguing deep learning generalization phenomena like benign overfitting and double descent are explainable by soft inductive biases.
335 points by pavanto | 83 comments
arXiv listing for "Probabilistic Artificial Intelligence" by Andreas Krause and Jonas Hübotter, a manuscript on probabilistic ML, uncertainty, and decision-making.
339 points by fofoz | 103 comments
arXiv paper introducing LADDER, a framework where LLMs self-improve by recursively generating simpler problem variants, plus TTRL test-time reinforcement learning.
438 points by iNic | 161 comments
arXiv paper introducing FFTNet, an FFT-based adaptive spectral filtering framework offering O(n log n) token mixing as an alternative to self-attention.
331 points by joshwa | 113 comments
arXiv paper introducing SWE-Bench+, an empirical analysis revealing data quality issues in the SWE-bench coding benchmark for LLMs, such as solution leakage and weak tests.
376 points by trott | 126 comments
arXiv paper presenting LIMO, a model showing complex math reasoning in LLMs can be elicited with only 817 curated training samples.
1116 points by gradus_ad | 932 comments
arXiv abstract page for the DeepSeek-AI paper introducing DeepSeek-R1, which uses reinforcement learning to improve reasoning in large language models.
420 points by belter | 78 comments
arXiv paper surveying a decade of time-series anomaly detection methods, proposing a process-centric taxonomy of approaches.
362 points by rev13013 | 175 comments
arXiv paper studying the phase behavior and stability of Cacio e pepe sauce, identifying starch concentration as key to avoiding clumping.
346 points by JSeymourATL | 445 comments
arXiv economics paper by Hunter Ng using Glassdoor data and an LLM-BERT technique to estimate that up to 21% of job ads may be ghost jobs never meant to be filled.
573 points by pil0u | 71 comments
arXiv paper introducing OpenCoder, an open code LLM released with its training data, data pipeline, and protocols as an open cookbook for research.
352 points by benocodes | 229 comments
arXiv paper examining tasks where chain-of-thought prompting reduces LLM performance, drawing on cases where deliberation hurts human performance.
525 points by weirdcat | 166 comments
arXiv paper introducing Diff Transformer, which computes attention as the difference of two softmax maps to cancel noise and improve long-context modeling and reduce hallucination.
466 points by beefman | 245 comments
arXiv paper proposing minimal LSTM and GRU variants without hidden-state gate dependencies that can be trained in parallel, rivaling recent sequence models.
519 points by sahebjot | 172 comments
Homepage of alphaXiv, a Stanford project that adds open discussion and comments on top of arXiv research papers.
436 points by mathgenius | 215 comments
An n-Category Café blog post by Tom Leinster announcing the arXiv release of his Edinburgh undergraduate Galois theory notes, plus videos and problem sets.
962 points by fgfm | 419 comments
arXiv paper introducing BitNet b1.58, a ternary-weight (-1, 0, 1) LLM matching full-precision Transformers while being far cheaper in latency, memory, and energy.
687 points by zaikunzhang | 287 comments
arXiv preprint reporting possible Meissner effect near room temperature in copper-substituted lead apatite (LK-99-type material), based on magnetization measurements.

412 points by Anon84 | 132 comments
arXiv listing for a book by Jentzen, Kuckuck, and von Wurstemberger giving a mathematically rigorous introduction to deep learning methods, implementations, and theory.
365 points by saeedesmaili | 171 comments
arXiv paper introducing OpenVoice, a voice cloning method that replicates a speaker's voice from a short clip with style control and zero-shot cross-lingual support.
1130 points by programd | 296 comments
arXiv blog post announcing that research papers are now available in HTML format to improve accessibility for users with disabilities.
338 points by vincent_s | 302 comments
arXiv paper presenting a user study of 1,400 participants solving 14,000 modern CAPTCHAs, evaluating solve times and user perceptions.
585 points by Tepix | 258 comments
An arXiv paper by Hiroki Takizawa announcing that 8x8 Othello has been computationally solved, with perfect play by both sides resulting in a draw.
509 points by JohnHammersley | 136 comments
Cornell Chronicle article announcing that arXiv received over $10 million from the Simons Foundation and NSF to fund upgrades.
373 points by PaulHoule | 114 comments
arXiv paper introducing TimeGPT, a foundation model for time series forecasting that performs zero-shot predictions on unseen datasets.
325 points by fbartos | 220 comments
arXiv paper reporting 350,757 coin flips showing fair coins land on the same side they started slightly more often than chance.

317 points by platz | 276 comments
arXiv preprint reporting that LK-99-like samples show half levitation due to soft ferromagnetism, with no evidence of superconductivity.
2308 points by spekcular | 1146 comments
arXiv preprint reporting synthesis of LK-99 crystals that show room-temperature, ambient-pressure magnetic levitation, replicating Sukbae Lee et al.'s claims.
734 points by segfaultbuserr | 348 comments
arXiv preprint reporting zero resistance above 100 K at ambient pressure in a synthesized polycrystalline sample of copper-doped lead apatite (LK-99).
497 points by spekcular | 373 comments
arXiv preprint presenting DFT calculations of the electronic structure of the putative room-temperature superconductor LK-99 (Pb9Cu(PO4)6O), finding flat Cu bands at the Fermi level.
444 points by lnyan | 268 comments
arXiv preprint (v2) by Lee et al. claiming LK-99, a copper-doped lead apatite, is a room-temperature ambient-pressure superconductor showing levitation.
374 points by lawrenceyan | 181 comments
arXiv preprint by Sinéad Griffin using DFT to identify correlated isolated flat bands in copper-substituted lead phosphate apatite (LK-99).
576 points by spekcular | 240 comments
arXiv preprint reporting a synthesis of the LK-99 compound Pb10-xCux(PO4)6O that shows semiconducting rather than superconducting transport.
1400 points by Akronymus | 770 comments
arXiv preprint by Lee, Kim, and Kwon claiming LK-99, a modified lead-apatite, is a room-temperature, ambient-pressure superconductor.
318 points by ianbutler | 164 comments
arXiv paper introducing RWKV, a model architecture combining Transformer-style parallel training with efficient RNN inference via linear attention.
326 points by mmq | 178 comments
arXiv paper introducing generative agents, LLM-powered software agents that simulate believable human behavior in an interactive sandbox environment.